Showing 28 of 1504 results
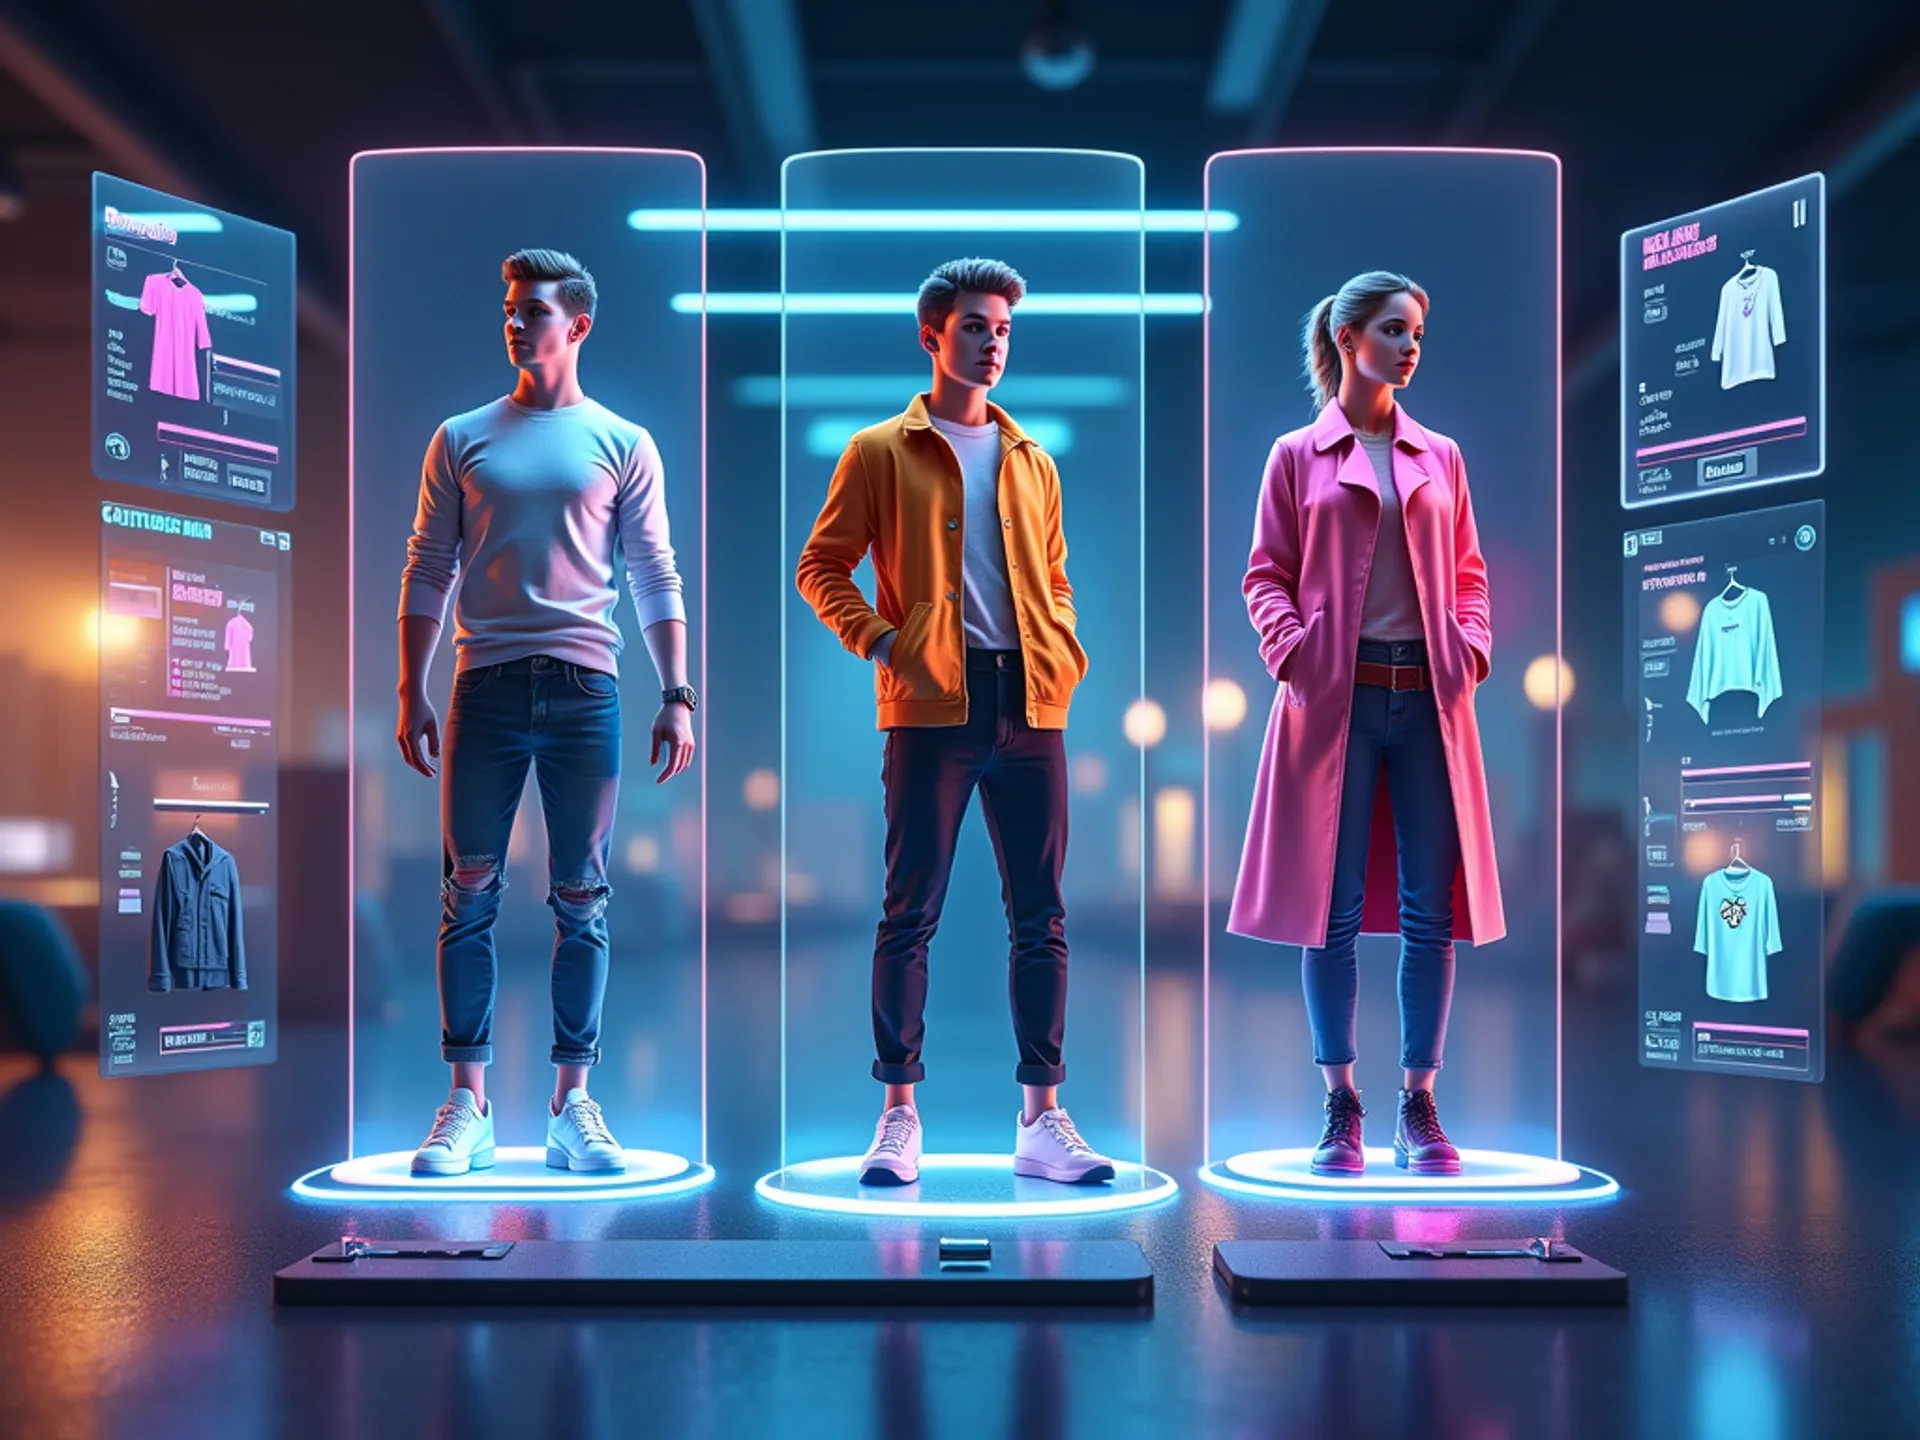


Kling Kolors Virtual TryOn v1.5 is a high quality image based Try-On endpoint which can be used for commercial try on.
try-on
fashion
clothing
image-to-image
stable-diffusion-v35-large
Stable Diffusion 3.5 Large is a Multimodal Diffusion Transformer (MMDiT) text-to-image model that features improved performance in image quality, typography, complex prompt understanding, and resource-efficiency.
diffusion
typography
style
text-to-image


Happy Horse 1.1 is Alibaba's #1-ranked video model. This reference-to-video endpoint turns up to 9 reference images into 1080p video with synchronized native audio and multilingual lip-sync for consistent characters.
happy-horse
video
reference
image-to-video


FLUX General Image-to-Image is a versatile endpoint that transforms existing images with support for LoRA, ControlNet, and IP-Adapter extensions, enabling precise control over style transfer, modifications, and artistic variations through multiple guidance methods.
lora
controlnet
ip-adapter
image-to-image

Create blazing fast and economical videos with MiniMax Hailuo-02 Image To Video API at 512p resolution
stylized
transform
image-to-video
tripo3d/triposplat
TripoSplat is an open-source model from TripoAI / VAST AI Research that converts a single 2D image into high-quality 3D Gaussians using a novel learned density-control approach
3d
gaussian-splat
image-to-3d
finegrain-eraser/mask
Finegrain Eraser removes any object selected with a mask—along with its shadows, reflections, and lighting artifacts—seamlessly reconstructing the scene with contextually accurate content.
utility
editing
image-to-image

Pixverse's latest v6 Model.
first-frame-last-frame
transition
image-to-video
Generate music from text prompts using the MiniMax model, which leverages advanced AI techniques to create high-quality, diverse musical compositions.
music
text-to-audio


Transform existing images with Ideogram V3's editing capabilities. Modify, adjust, and refine images while maintaining high fidelity and realistic outputs with precise prompt control.
realism
typography
image-to-image
florence-2-large/object-detection
Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks
detection
multimodal
vision
image-to-image
Generate a video by taking a start frame and an end frame, animating the transition between them while following text-driven style and scene guidance.
image-to-video
recraft/v3/image-to-image
Recraft V3 is a text-to-image model with the ability to generate long texts, vector art, images in brand style, and much more. As of today, it is SOTA in image generation, proven by Hugging Face's industry-leading Text-to-Image Benchmark by Artificial Analysis.
vector
typography
style
image-to-image
feynobg
FeyNobg is a state of the art AI model for background removal from feyninc
utility
editing
image-to-image

Wan 2.6 image-to-video flash model.
image-to-video
vidu/q3/image-to-video
Vidu's latest Q3 pro models.
image-to-video
Generate video clips from your images using Kling 2.0 Master
image-to-video
Animate images into cinematic videos with PixVerse C1, supporting 1080p resolution and native audio generation.
video-generation
pixverse
animation
image-to-video


GPT Image 1 mini combines OpenAI's advanced language capabilities, powered by GPT-5, with GPT Image 1 Mini for efficient image generation.
image-to-image
pika/v2.2/image-to-video
Turn photos into mind-blowing, dynamic videos in up to 1080p. Experience better image clarity and crisper, sharper visuals.
editing
effects
animation
image-to-video
new
meshy/v7/text-to-3d
Turns text into a fully textured, PBR-ready 3D mesh with complete geometry, in game-ready Smart Topology at a target polygon count
stylized
transform
text-to-3d

LTX-2.3 is a high-quality, fast AI video model available in Pro and Fast variants for text-to-video, image-to-video, and audio-to-video.
stylized
transform
lipsync
text-to-video


Seed Speech developed by ByteDance, is a family of large-scale text-to-speech models capable of synthesizing speech that is virtually indistinguishable from human speech.
stylized
transform
lipsync
text-to-speech
meshy/v6-preview/image-to-3d
Meshy-6-Preview is the latest model from Meshy. It generates realistic and production ready 3D models.
image-to-3d
sana
Sana can synthesize high-resolution, high-quality images with strong text-image alignment at a remarkably fast speed, with the ability to generate 4K images in less than a second.
text-to-image
smart-resize
Smart image resize to arbitrary dimensions, powered by Nano Banana Pro with vision-LLM-guided prompting for composition-aware recomposition. Crop, cropping, resize ads.
realism
typography
visual
image-to-image
florence-2-large/more-detailed-caption
Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks
captioning
multimodal
vision

References into video with synchronized audio using MiniMax H3
utility
editing
video-to-video
Showing 449 to 476 of 1504 results