Search models...Search by model, task, category and more
Studio-quality speech from noisy recordings
speech enhancement
noise reduction
audio denoise
audio-to-audio
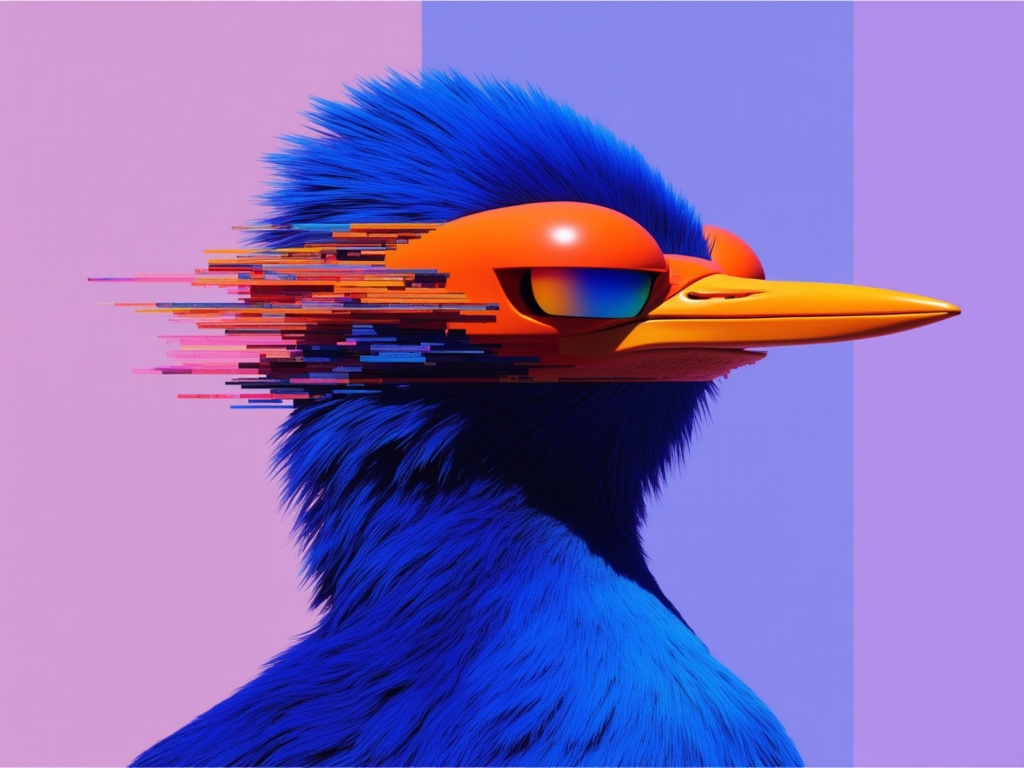
recraft/v4.1/flash/text-to-image
Recraft V4.1 Flash generates raster images from text prompts, including photography, illustrations, and mixed-media compositions, with controls for image size, color palette, and background color.
photography
editorial
illustration
text-to-image
hunyuan-3d/v3.1/rapid/image-to-3d
Rapidly generate 3D models from images using Hunyuan 3D.
3d
hunyuan
image-to-3d

recraft/v4.1/pro/text-to-image
Recraft V4.1 Pro pushes the V4.1 model into high-resolution territory — up to 2048×2048 and ultra-wide formats. Made for hero imagery, campaign work, and print, it preserves the same design taste at sizes ready for the final deliverable.
stylized
transform
typography
text-to-image



Super fast endpoint for the FLUX.1 [dev] inpainting model with LoRA support, enabling rapid and high-quality image inpaingting using pre-trained LoRA adaptations for personalization, specific styles, brand identities, and product-specific outputs.
lora
personalization
text-to-image

sam-3/image-rle
SAM 3 is a unified foundation model for promptable segmentation in images and videos. It can detect, segment, and track objects using text or visual prompts such as points, boxes, and masks.
segmentation
rle
real-time
image-to-image

A versatile endpoint for the FLUX.1 [dev] model that supports multiple AI extensions including LoRA, ControlNet conditioning, and IP-Adapter integration, enabling comprehensive control over image generation through various guidance methods.
lora
controlnet
ip-adapter
text-to-image



Kling O3 Omni generates new shots guided by an input reference video, preserving cinematic language such as motion, and camera style to produce seamless scene continuity.
video-to-video

sync-lipsync/v3/image-to-video
sync-3 image to video turns a single still into a talking character, and works with any illustration or animated frame paired with a voice track
animation
lip sync
text-to-speech
image-to-video

image-apps-v2/outpaint
Directional outpainting. Choose edges to expand. left, right, top, or center (uniform all sides). Only expanded areas are generated; an optional zoom-out pulls the frame back by the chosen amount.
outpainting
image-to-image



Wan 2.6 image-to-video flash model.
image-to-video
Expands existing videos to a selected aspect ratio with generative outpainting, preserving source audio and timing. Supports optional text guidance and 480p, 768p, or 1080p output.
video
outpainting
reframing
video-to-video

Text to Video endpoint for Seedance 1.0 Pro Fast, a next-generation video model designed to deliver maximum performance at minimal cost
bytedance
fast
motion
text-to-video
LTX-2.3 is a high-quality, fast AI video model available in Pro and Fast variants for text-to-video, image-to-video, and audio-to-video.
stylized
transform
lipsync
text-to-video

Professional transparent-image upscaling powered by Topaz Labs. Preserves the alpha channel end to end with PNG output. Best for logos, stickers and assets with transparency.
upscale
image
image-to-image
new
Generates editable SVG vector graphics from text prompts, with optional reference images, three quality levels, and aspect ratio controls.
svg
vector
illustration
text-to-image
hyper3d/rodin/v2
Rodin by Hyper3D generates realistic and production ready 3D models from text or images.
text-to-3d
image-to-3d
Edit and transform images using text instructions with the WAN 2.7 Pro model for precise, professional-grade image modifications.
wan
image-editing
pro
image-to-image


Luma Ray 3.2 re-renders an existing video into new cinematic motion guided by a text prompt, preserving the source's look and movement while controlling resolution, duration, and HDR.
stylized
transform
lipsync
video-to-video
Pixverse's latest v6 Model.
first-frame-last-frame
transition
image-to-video

mmaudio-v2/text-to-audio
MMAudio generates synchronized audio given text inputs. It can generate sounds described by a prompt.
audio
fast
text-to-audio
Transform Blender renders and 3D previs into photorealistic video. H3 Max uses the source clip to guide scene layout, camera movement, and timing, with optional image references for appearance.
3d
photorealistic
previs
video-to-video

seedvr/upscale/image/seamless
Use SeedVR2 to upscale images, retaining seamless tiling
upscale
seamless
tiling
image-to-image

Generate realistic videos using Kling O3 from Kling Team!
text-to-video
Showing 409 to 432 of 1432 results