


Every new model, one API
New models from leading labs go live on fal as they are released, behind the same client and request shape.
- Day-zero access to new releases
- Switch models in one line
fal is an AI inference platform built for image, video, audio, 3D and world models. Call 1,400+ model endpoints through one inference API, or run your own models and pipelines on serverless GPUs that autoscale from zero, with reserved capacity when you need a guaranteed floor.





Most teams start by calling a hosted model through the inference API. When the model is yours, they deploy it on fal Serverless. Both run on the same inference runtime and the same queue, so the client and the request stay the same.
 01
Call hosted image, video, audio and 3D models with one key. Built for consumer and creative apps shipping to millions.
1,400+model endpoints behind one inference API
 02
Deploy your own model, pipeline or container on the runtime behind every fal Model API. Built for model labs and media teams.
0 → 1,000sof GPUs, scaling with your traffic
The models teams build on, from the labs that make them, ready to call with one key. No GPUs to provision and no deploy step.


import { fal } from "@fal-ai/client"; const result = await fal.subscribe("meshy/v7.1/text-to-3d", { input: { prompt: "A rustic, antique wooden treasure chest with a curved, domed lid, constructed from weathered, dark brown planks exhibiting prominent wood grain and subtle distress. It's heavily reinforced with broad, dark grey, oxidized metal bands secured by numerous circular rivets. Ornate, dark iron decorative elements featuring swirling foliate patterns and dragon motifs adorn the corners and lid. A prominent, circular, intricately carved metal lock plate with a central keyhole dominates the front, flanked by two large, dark metallic pull rings.", target_polycount: 30000, },}); console.log(result.data.model_glb.url);New models from leading labs go live on fal as they are released, behind the same client and request shape.
Most models are priced per output, and the rest per second of GPU time. When nothing runs, nothing is billed.
Queued requests go through a managed queue. It absorbs traffic spikes, and requests that hit a transient failure go back into the queue and run again.
Organizations, access controls and data controls for teams shipping to production.
Compare models, automate creative work and chain models into pipelines, all on the same platform as the API.
The same runtime every fal Model API runs on. Deploy a model, pipeline or container, and fal handles the queue, the GPUs and the scaling.
Keep your Dockerfile and routes. Add your port to pyproject.toml, then run fal deploy.
FROM pytorch/pytorch:2.5.1-cuda12.4-cudnn9-runtime WORKDIR /appCOPY . .RUN pip install -r requirements.txt # Your existing FLUX server, unchangedCMD ["python", "server.py", "--host", "0.0.0.0", "--port", "8000"][tool.fal.apps.flux-server]machine_type = "GPU-H100"exposed_port = 8000keep_alive = 300max_concurrency = 1000 [tool.fal.apps.flux-server.image]dockerfile = "Dockerfile"const result = await fal.subscribe("acme/flux-server/generate", { input: { prompt: "a knight resting by a campfire" },});
Keep a reserved baseline of warm runners for steady traffic, and burst onto the shared fleet when demand spikes. Billed per second while runners are up.
Requests, latency, errors, runners and cold starts in one dashboard, with logs for every request. Add your own OpenTelemetry traces.
Bring your own container image or an existing Docker server. Guides cover moving from Modal, RunPod, Baseten and Replicate.
fal's optimization kit cuts startup time. Files on /data are cached automatically across three layers, FlashPack streams weights from disk to GPU, and compiled kernels can be shared across runners.
Serve a model on fal, then sell it on fal. Publish to the marketplace and reach the developers and enterprises already calling the inference API, with fal's team co-selling enterprise deals.
Talk to us about publishing




Your model sits in the fal gallery and API alongside the models teams already use, in front of the developers and enterprise teams building on fal.
fal launches your model with you, across its channels and community, with GTM support on joint calls and custom demos.
Callers pay with their own fal key. You report billable units per request, fal sets the unit price with you, and there is no billing or infrastructure to run.
fal doesn't act like an infrastructure vendor; it acts like a go-to-market partner. Our engineers deploy, iterate and release on their own schedule, and the time from a model being ready in research to being live for developers is measured in days, not weeks. Every launch fal amplifies brings a wave of new developers and teams. It's the reason we chose to build both on fal and with fal.
Each modality puts a different load on inference. Image wants throughput, video wants GPU memory, audio wants streaming, and world models want a live connection.
Music, speech and sound effects, with streaming output on supported speech models.
Browse audio models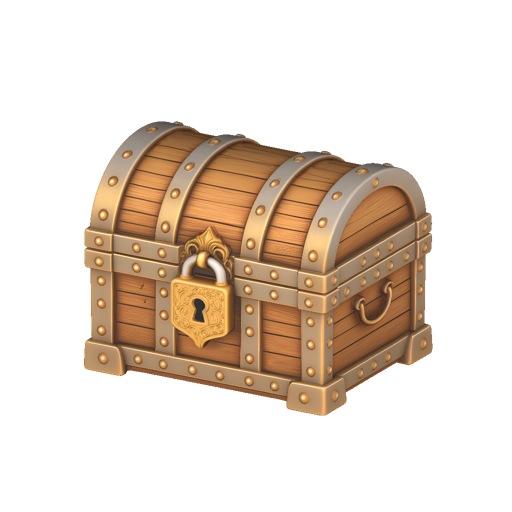
fal WMA, the World Model Accelerator, streams world models over a live WebRTC connection for interactive worlds, with the same inference, serverless compute and distribution as every other model on fal.
Every fal Model API runs on the runtime you deploy to. Billions of requests served a year across 1,300+ production endpoints harden it before it reaches yours.
fal Research post-trained H3 Max on fal Compute and serves it on fal Serverless across multiple nodes behind one endpoint, published as a Model API on the inference API. It ranks first for image-to-video on Artificial Analysis.
Read the case study →Elasticity is what's changed how we work. Standing up a new model fleet on fal Serverless, sizing it against real traffic, and scaling without hardware procurement helped make our Suno v6 rollout possible.
An inference platform runs trained AI models in production and serves their outputs over an API. It manages the GPUs, autoscaling, request queues and monitoring, so the team building the product does not have to.
AI inference is running a trained model on new inputs to produce outputs, such as generating an image from a prompt. Training builds the model once; inference runs every time a user makes a request, so its speed and cost decide the product's experience and margins.
fal runs world models through fal WMA, the World Model Accelerator. It streams causal and bidirectional diffusion models over WebRTC, scales from 1 to 1,000 GPUs across clouds and regions, and handles signaling and TURN relay. H3 Max Director and Abot World run on it today, and fal Worlds lets you browse them and start a live session.
fal is built specifically for generative media inference: an inference API for 1,400+ image, video, audio and 3D model endpoints, serverless inference for your own models with reserved capacity and burst, real-time WebSocket and WebRTC transport, and a marketplace to distribute the models you serve.
Serverless inference runs a model on GPUs that start when requests arrive and stop when they do not. On fal Serverless you set floors, caps and warm buffers per app, and you are billed per second while a runner is alive.
The inference API calls models fal already hosts, priced per output or per GPU second. Serverless inference runs your own model, pipeline or container on fal's GPUs, billed per second of runner time. Both use the same client, queue and calling patterns.
Yes. New models from leading labs go live on fal as they are released, with an API endpoint and a playground on day one.
Every account has a concurrency limit on how many requests run at once. New accounts start at 2 and the limit rises automatically with purchased credits, up to 40. Requests above the limit wait in the queue. Contact sales for higher limits.
Generated files are stored on the fal CDN for at least 7 days by default. You can set the retention period per request with the X-Fal-Object-Lifecycle-Preference header, and delete a request's stored payloads and output files through the Platform API.
Yes. A reservation guarantees a baseline of GPUs for your Serverless endpoints, and traffic above it bursts onto fal's shared fleet automatically. Contact sales to size one.
Write a fal.App class in Python with @fal.endpoint routes, bring a container image, or expose an existing HTTP server with exposed_port. Test with fal run and deploy with fal deploy.
Weights on /data are cached between startups automatically. FlashPack, fal's open-source loader, streams tensors from disk to GPU, and compiled kernels can be shared across runners. For latency-critical apps, min_concurrency and concurrency_buffer keep runners warm.
Inference API models are priced per output unit or, for some models, per GPU second, as listed on each model page, and time waiting in the queue is not billed. Serverless inference is billed per second while a runner is alive, by GPU type; time spent pending or pulling the image is not billed. Serverless GPU list prices per hour: B300 $12.99, GB200 $9.99, B200 $7.99, H200 $6.00, H100 $4.50, RTX PRO 6000 $4.00, with lower rates for volume and commitments. Reserved capacity is priced through sales. See all pricing
Yes, for supported models. Real-time endpoints keep a persistent WebSocket open to a runner, models with a streaming endpoint send outputs over server-sent events, and fal WMA streams over WebRTC for interactive applications.
Yes. Publish a Serverless app to the fal marketplace. Callers pay with their own fal key for their own usage, and the fal team configures unit pricing and the model card with you.
For large training runs, fal Compute provides dedicated GPU clusters on reserved terms. Contact sales to size one. You can deploy the trained weights to fal Serverless for inference.
Tell us what you are serving, the traffic you expect and the latency you need. The team comes back with a plan for the inference API, serverless inference or a reserved floor, and stays with you from the first deploy to launch day.