Every model on fal runs on Serverless.
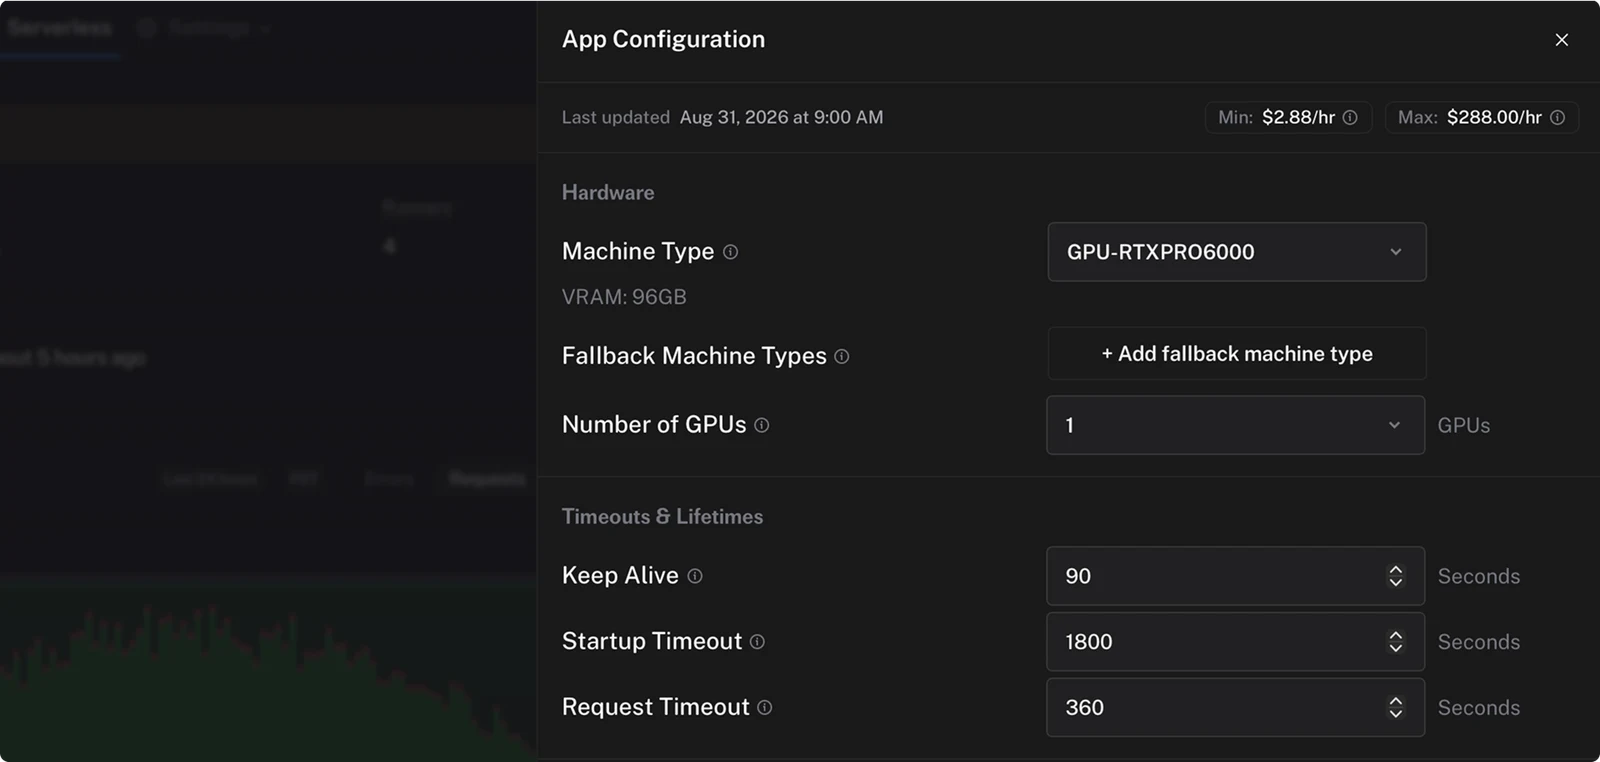
Serverless is fal's inference runtime, built for generative media workloads. Bring a container, a Python app, or an existing inference server, and run it on managed GPUs with autoscaling, logs, and analytics built in.
A member of our team will reach out to schedule a live walkthrough of Serverless on your workload.
Requests by app
How Serverless works
3 steps from application code to a production endpoint.
However your application arrives, it lands on the same managed infrastructure.
Bring what you have
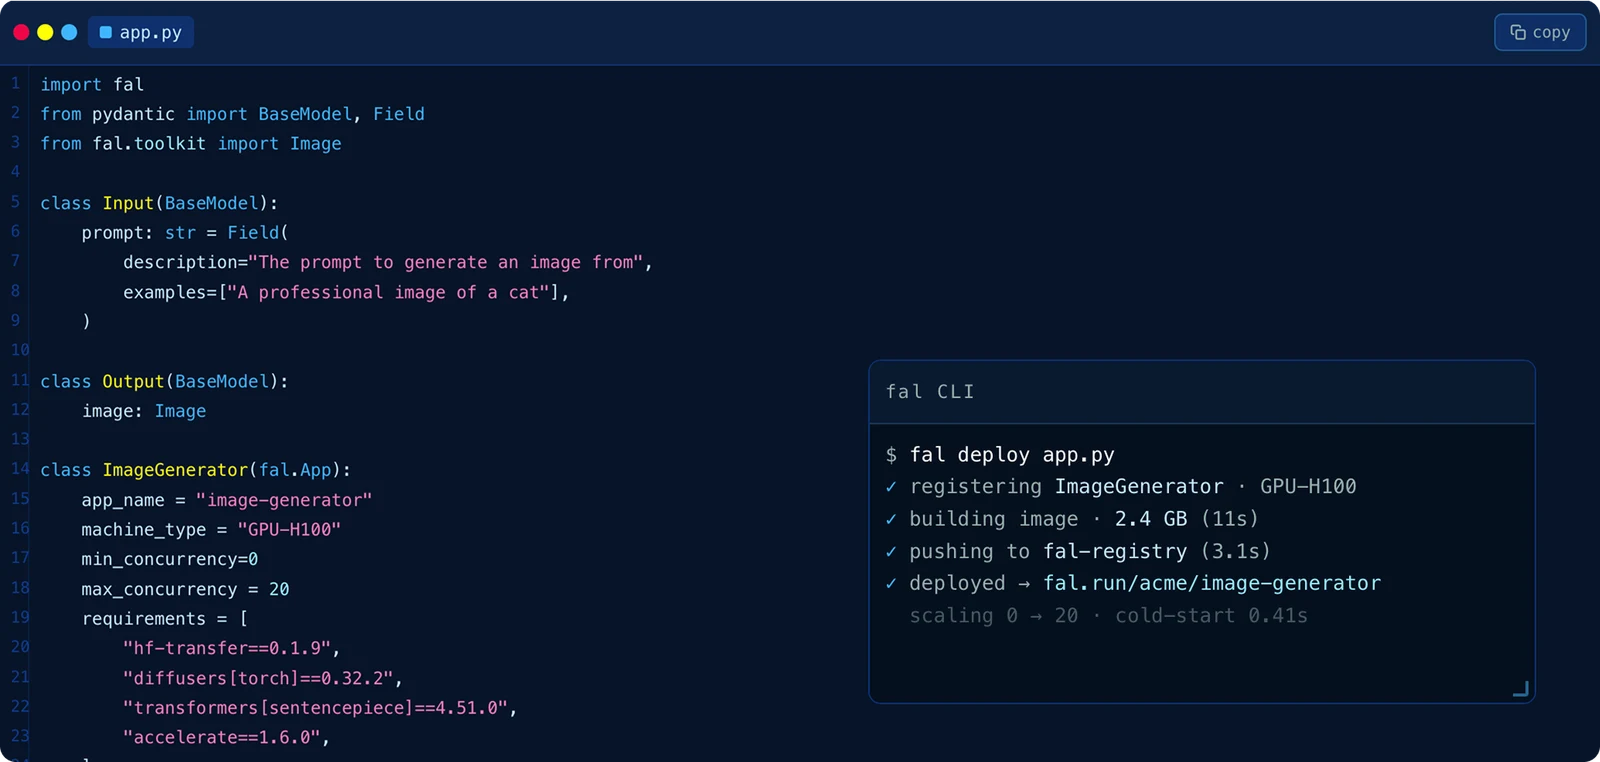
Your Dockerfile, your weights, your dependencies. Migration guides for Modal, Baseten, and RunPod, or wrap a model in a fal.App class.
Deploy on managed GPUs
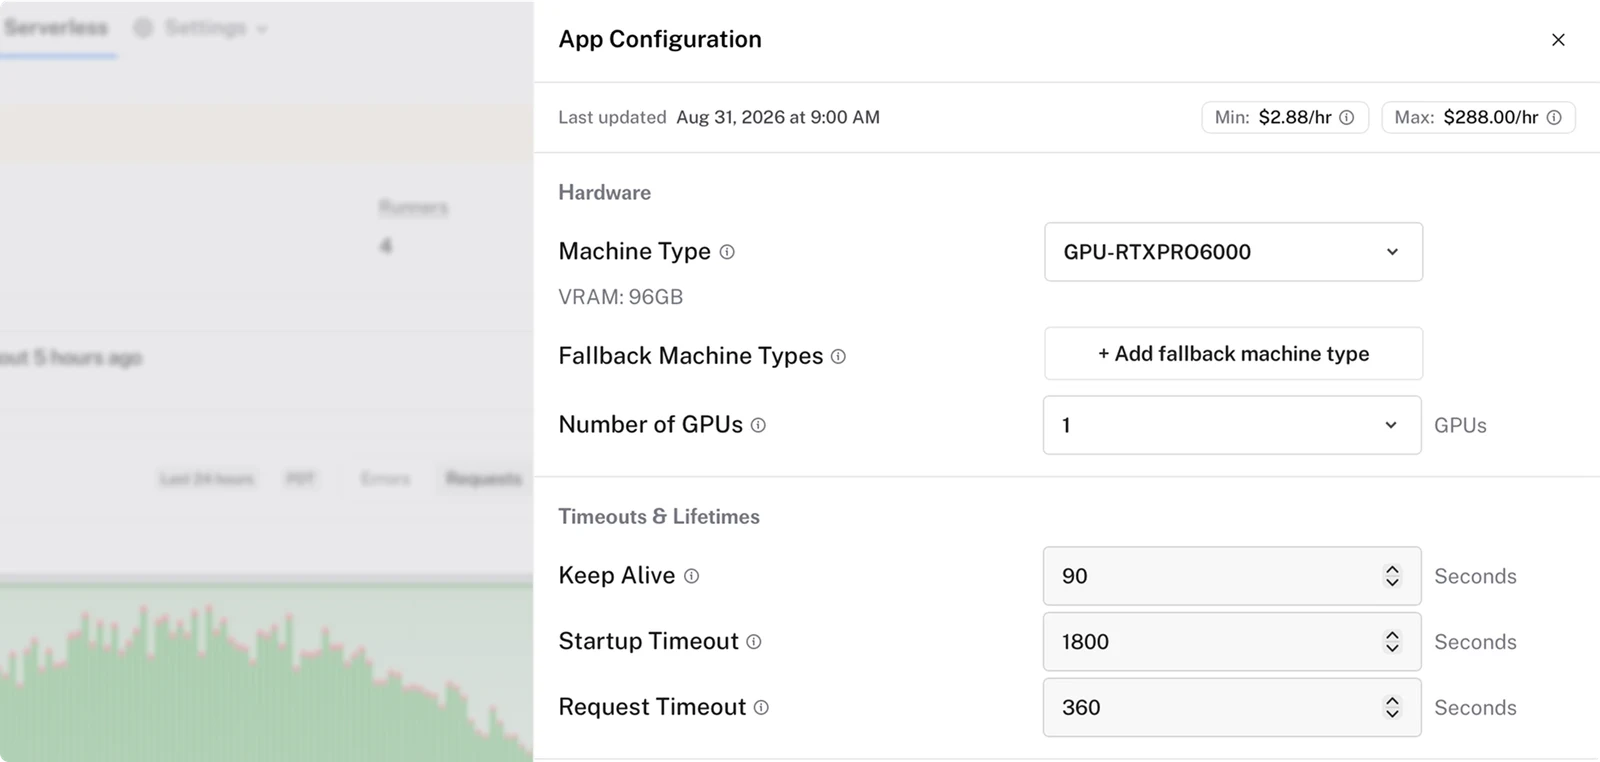
fal deploy builds, pushes, warms, and serves your app behind a stable endpoint on H100s through B300s.
Run and scale
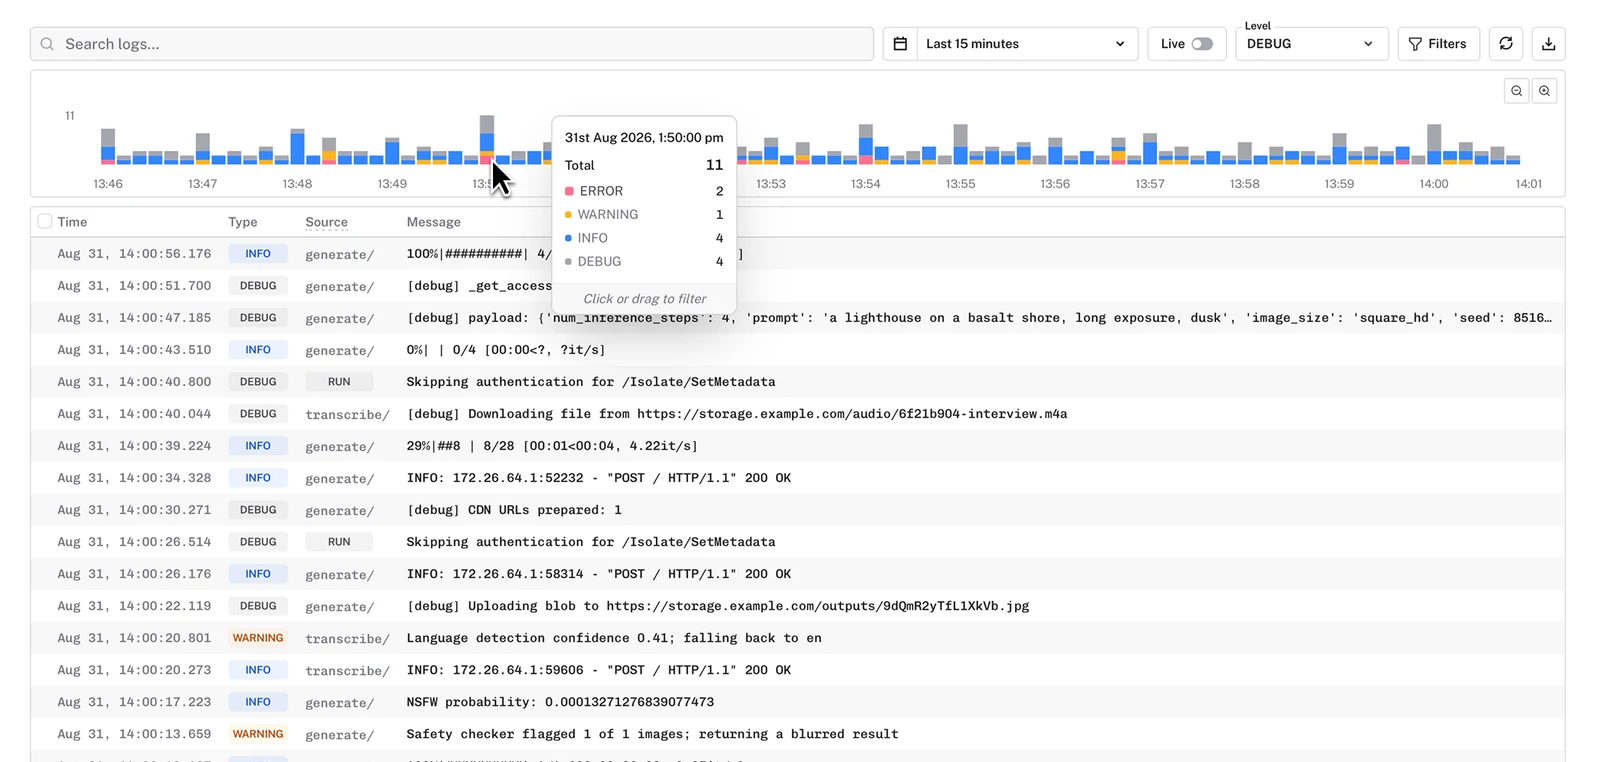
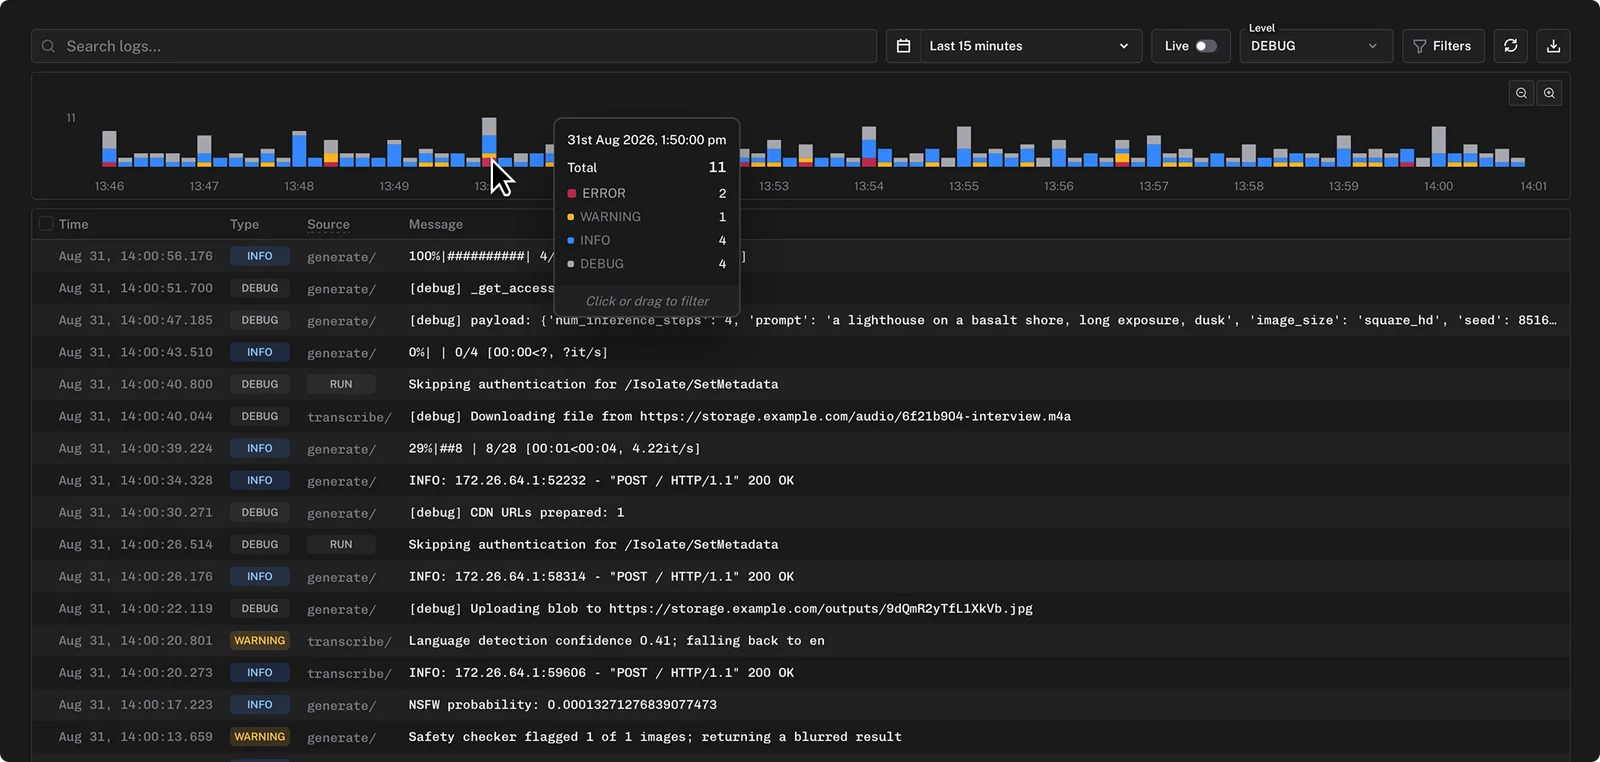
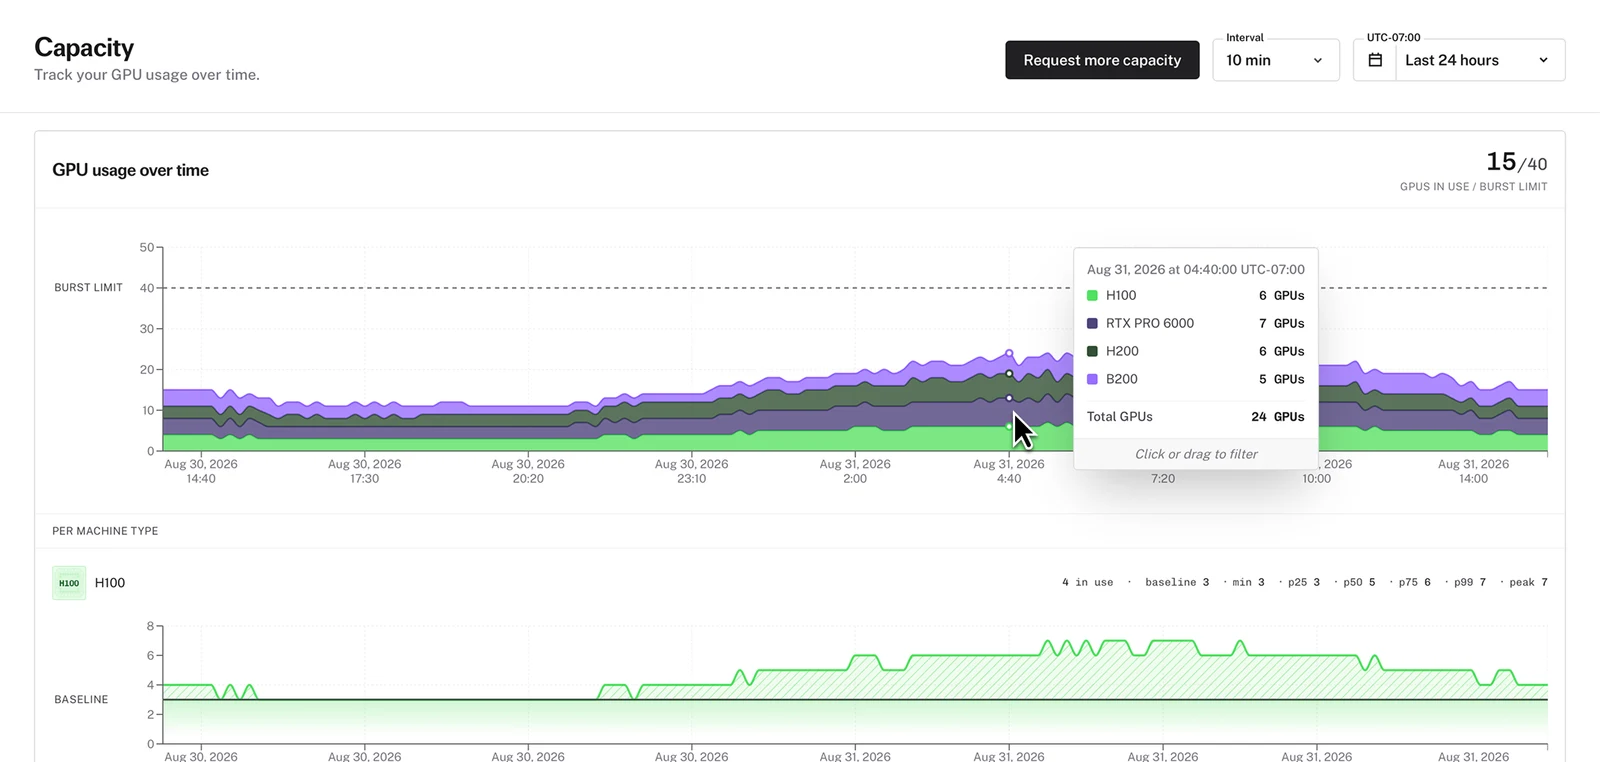
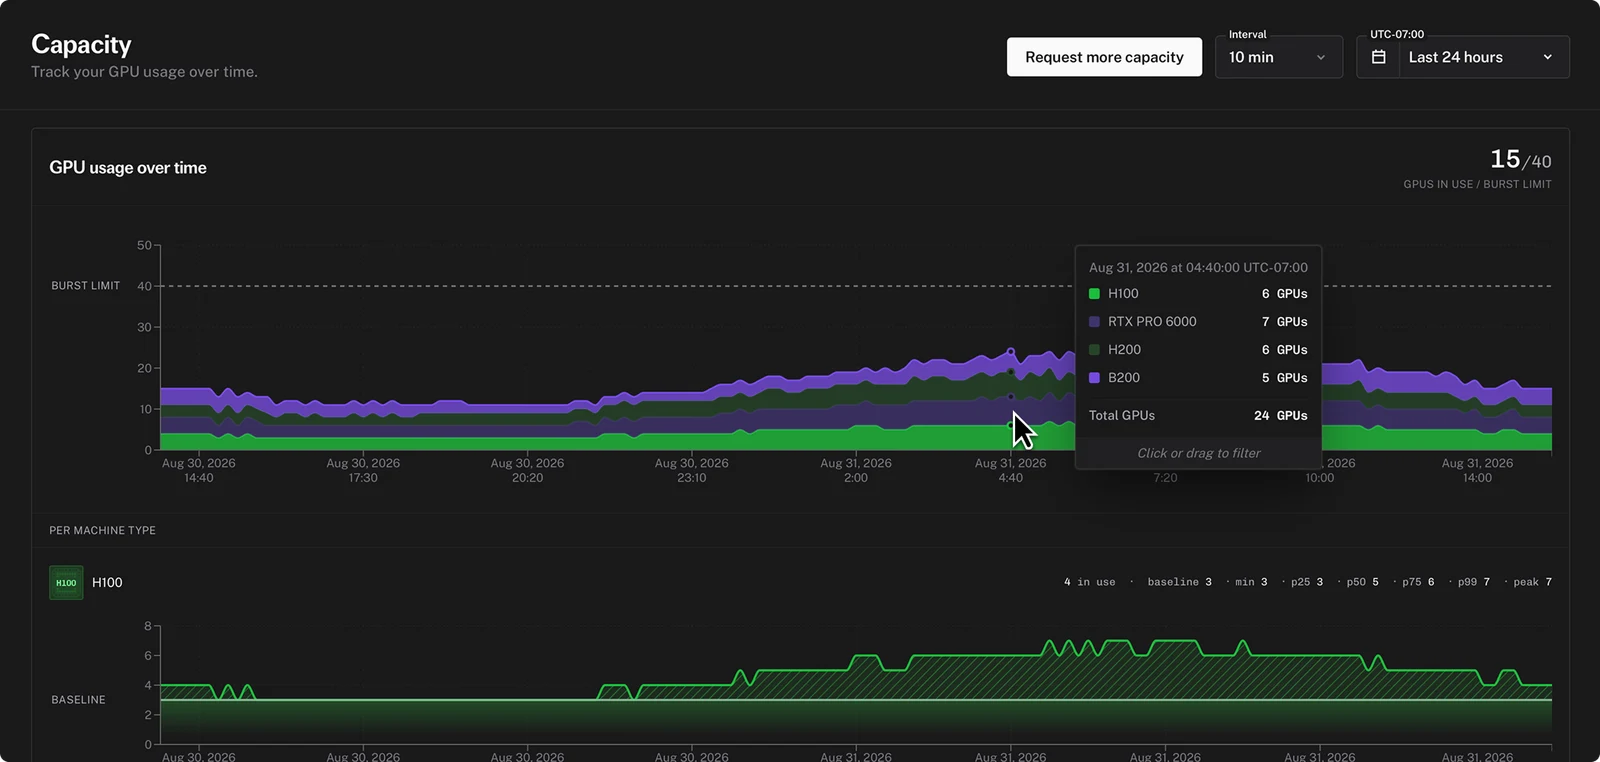
Runners start on demand, scale with traffic, and return to zero. Logs, analytics, and request traces are built in.
What's included
Demo applications
Open an application to see its metrics, logs, and runner activity.
Generate images from text
Generate an image from a prompt.
Convert speech to text
Transcribe audio to text with word-level timestamps.
Animate an image into video
Generate a short video from an image and a prompt.
Sync a portrait to audio
Animate a portrait so it speaks an audio track.
Tutorials & guides
Step-by-step guides for deploying and migrating your own workloads.
Migrate from Modal
Move an existing Modal app to fal, step by step.
Migrate from RunPod
Move RunPod Serverless workers to fal.
Migrate from Baseten
Bring your Baseten Truss deployments across.
Deploy with Custom Containers
Use your own Dockerfile for complex dependencies.
Deploy with WAN LoRA training
Fine-tune WAN video generation with LoRA.
Ready to deploy your own?
Bring an existing container, migrate an inference server, or build with fal.App — on managed GPUs, with logs and analytics built in.