Search models...Search by model, task, category and more



Transfer movements from a reference video to any character image. Cost-effective mode for motion transfer, perfect for portraits and simple animations.
video-to-video

Generate images from text using xAi's Grok Imagine 2.0 model.
xai
grok
text-to-image
Generate high-quality images, posters, and logos with Ideogram 4.5, with accurate text rendering and low, medium, or high quality tiers.
realism
typography
stylized
text-to-image
sam-audio/separate
Audio separation with SAM Audio. Isolate any sound using natural language—professional-grade audio editing made simple for creators, researchers, and accessibility applications.
sam-audio
audio-to-audio



Edits images from one to three reference images and a natural-language instruction, preserving key details such as facial features and identity while applying the requested changes
stylized
transform
typography
image-to-image

openrouter/router/video
Run any video-capable LLM with fal. Analyze, summarize, and understand video files using Gemini (Google) models. Supports mp4, mpeg, mov, webm, and YouTube links. Powered by OpenRouter.
video-to-text
MiniMax H3 is a frontier video model. This endpoint generates video from a text prompt alone, rendering at 2K in durations from 5 to 15 seconds across seven aspect ratios.
stylized
transform
lipsync
text-to-video
Gemini Omni Flash 1.1 is Google's multimodal video model. This endpoint generates video from combined multimodal references, images, videos and text together. Reasoning across all inputs to produce a single coherent result, with characters retaining their face, clothing, and voice throughout
stylized
transform
lipsync
image-to-video

aura-sr
Upscale your images with AuraSR.
upscaling
high-res
image-to-image
new
Gemini Omni Flash 1.2 is Google's multimodal video model. This endpoint generates video with synchronized native audio from a text prompt, at 360p, 720p, 1080p, or 4K, in 16:9 or 9:16, with durations from 3 to 15 seconds.
stylized
transform
lipsync
text-to-video

Generate music from text prompts using the MiniMax Music 2.0 model, which leverages advanced AI techniques to create high-quality, diverse musical compositions.
music
audio
text-to-audio

Bring speech to your texts using Qwen3-TTS Custom-Voice model with pre-trained voices or use your custom voice with Qwen3-TTS Clone Voice model
text-to-speech

MiniMax Hailuo-02 Image To Video API (Standard, 768p, 512p): Advanced image-to-video generation model with 768p and 512p resolutions
image-to-video
fast-sdxl
Run SDXL at the speed of light
diffusion
lora
embeddings
text-to-image

Transfer movements from a reference video to any character image. Cost-effective mode for motion transfer, perfect for portraits and simple animations.
stylized
transform
editing
video-to-video

Seed Audio 1.0 is a new audio model from Bytedance that can generate high-quality, natural sounding audio using text, reference audios or an image.
text-to-audio

sam-3-1/image
SAM 3.1 builds comes with Object Multiplex, a shared-memory approach for joint multi-object tracking that delivers faster speeds with larger number of objects tracked.
segmentation
mask
real-time
image-to-image



FLUX.1 Image-to-Image is a high-performance endpoint for the FLUX.1 [dev] model that enables rapid transformation of existing images, delivering high-quality style transfers and image modifications with the core FLUX capabilities.
style transfer
image-to-image
Kling 4.0 Flash animates a starting image into a 720p video, with optional text prompts and durations from 3 to 20 seconds.
kling
v4
flash
image-to-video
sonilo/v1.1/text-to-music
Generates licensed, commercial-use-safe music from a single text prompt, with full control over style, mood, instrumentation, and exact duration.
stylized
transform
lipsync
text-to-audio
sam2/image
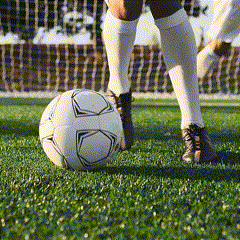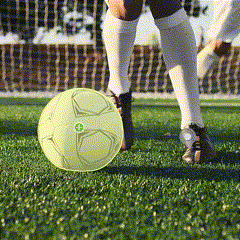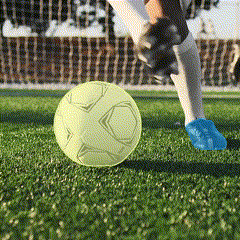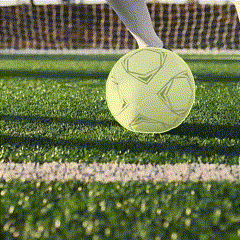
SAM 2 is a model for segmenting images and videos in real-time.
segmentation
mask
real-time
image-to-image

Change the voices in your audios with voices in ElevenLabs!
voice-change
audio-to-audio

Transform images, elements, and text into consistent, high-quality video scenes, ensuring stable character identity, object details, and environments.
reference-to-video
image-to-video

Isolate audio tracks using ElevenLabs advanced audio isolation technology.
audio
audio-to-audio
Showing 193 to 216 of 1432 results