Showing 28 of 1504 results

Generate music from text prompts using the MiniMax Music 2.0 model, which leverages advanced AI techniques to create high-quality, diverse musical compositions.
music
audio
text-to-audio


Qwen-Image is an image generation foundation model in the Qwen series that achieves significant advances in complex text rendering and precise image editing.
text-to-image


Experimental version of FLUX.1 Kontext [max] with multi image handling capabilities
image-to-image
seedvr/upscale/video
Upscale your videos using SeedVR2 with temporal consistency!
upscale
video-to-video


Generate video clips from your images using Kling 1.6 (std)
image-to-video
clarityai/crystal-upscaler
An advanced image enhancement tool designed specifically for facial details and portrait photography, utilizing Clarity AI's upscaling technology.
image-to-image
sync-lipsync/v2/pro
Generate high-quality realistic lipsync animations from audio while preserving unique details like natural teeth and unique facial features using the state-of-the-art Sync Lipsync 2 Pro model.
animation
lip sync
high-quality
video-to-video
new


Gemini Omni Flash 1.1 is Google's multimodal video model. This endpoint generates video with synchronized native audio from a text prompt, grounded in Gemini's real-world knowledge and physics understanding, with cinematic camera control expressed in natural language.
stylized
transform
lipsync
text-to-video
imageutils/nsfw
Predict the probability of an image being NSFW.
filter
safety
utility
vision


Splits a finished image into independent, editable transparent-PNG layers — background plus separate elements, from a text description, returning 2 to 17 layers per call for non-destructive reuse in design tools.
utility
editing
image-to-image
Lyria 3 Pro is the latest music model from Google
audio
sfx
text-to-audio

Image-to-image editing with FLUX.2 [dev] from Black Forest Labs. Precise modifications using natural language descriptions and hex color control—all at turbo speed.
image-to-image

Text-to-image generation with FLUX.2 [klein] 4B from Black Forest Labs. Enhanced realism, crisper text generation, and native editing capabilities.
text-to-image

Image-to-image editing with FLUX.2 [klein] 4B from Black Forest Labs. Precise modifications using natural language descriptions and hex color control.
image-to-image

Generates images from a text prompt at resolutions up to 2048×2048, with automatic prompt rewriting and prompt-guided resolution selection, building on Qwen's strength in complex text rendering and precise prompt adherence
stylized
transform
typography
text-to-image
Generates video with audio from combined multimodal references. Accepts text, images, audio, and video together as input to guide subject, motion, style, and sound in the output.
stylized
transform
lipsync
image-to-video
sam2/image
SAM 2 is a model for segmenting images and videos in real-time.
segmentation
mask
real-time
image-to-image
FLUX.3 Edit Video [FAST] is Black Forest Labs' frontier video model. This endpoint edits an existing video from natural-language instructions, applying targeted changes while preserving the rest of the scene.
stylized
transform
lipsync
video-to-video
workflow-utilities/trim-video
FFMPEG Utility for Trim Video
video-to-video
Transfer movements from a reference video to any character image. Pro mode delivers higher quality output, ideal for complex dance moves and gestures.
video-to-video
FLUX 3 is Black Forest Labs' frontier video model. This endpoint generates video directly from a text prompt, translating a written description into motion, composition, and scene.
stylized
transform
lipsync
text-to-video
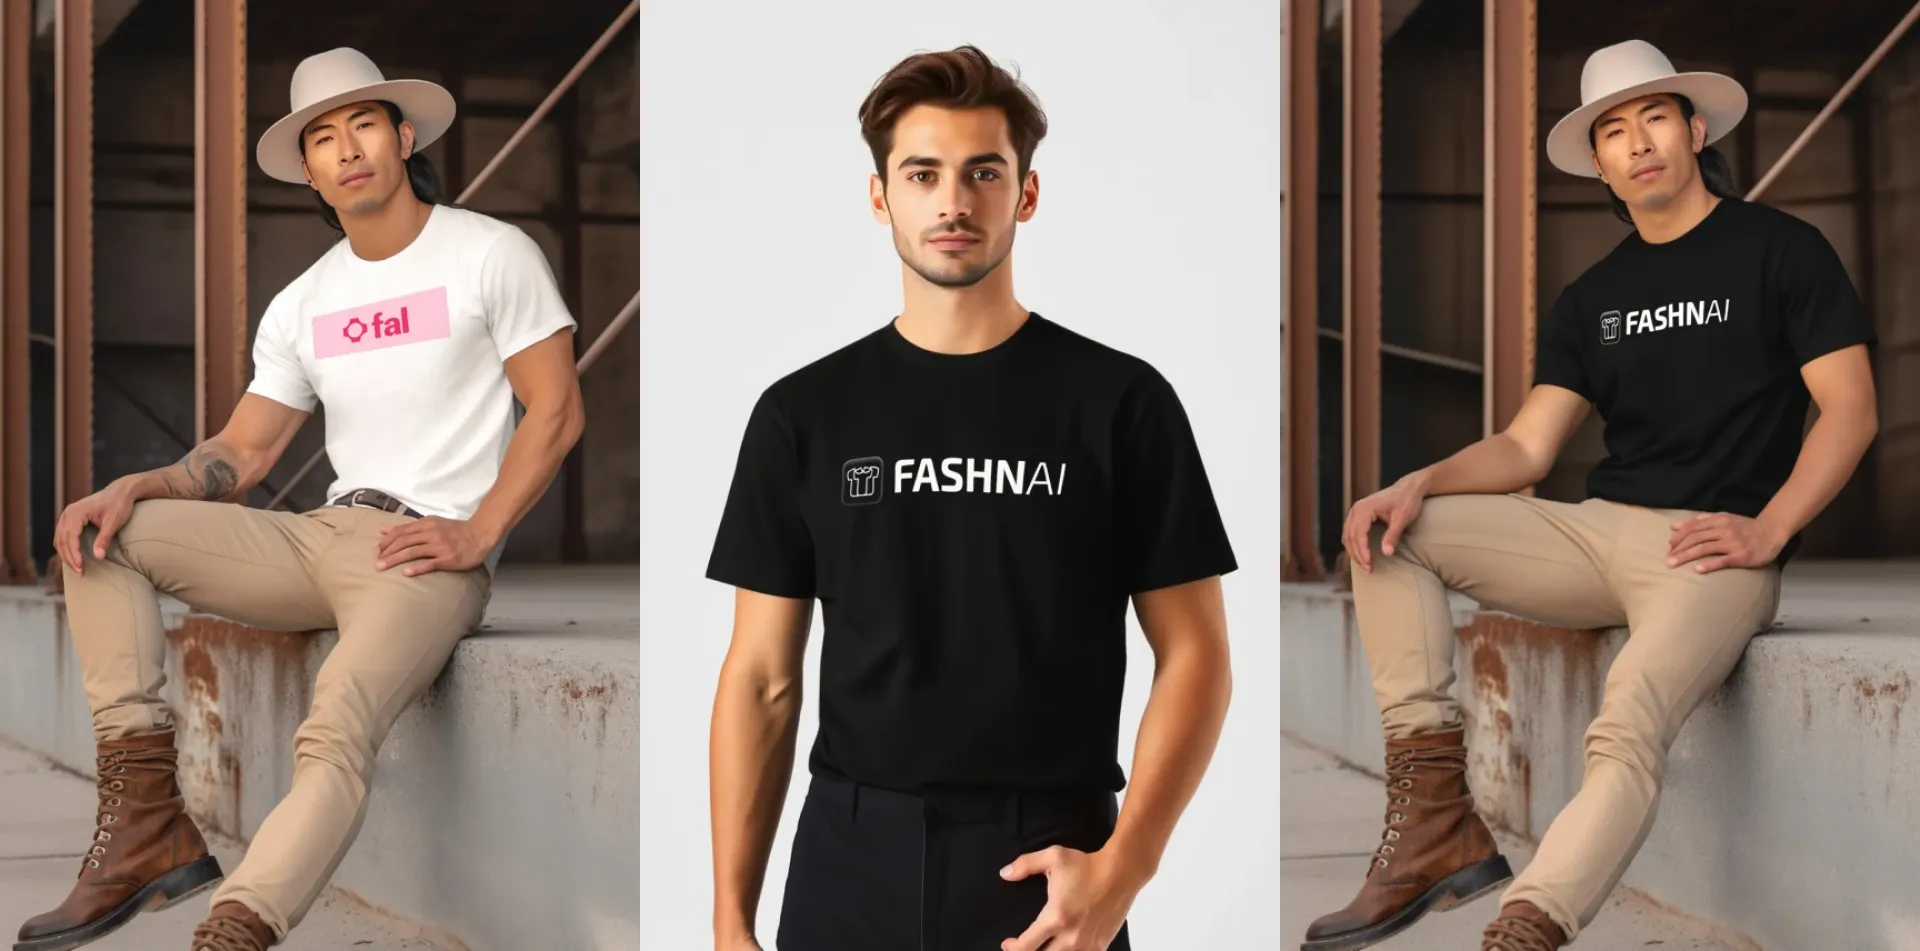
fashn/tryon/v1.6
FASHN v1.6 delivers precise virtual try-on capabilities, accurately rendering garment details like text and patterns at 864x1296 resolution from both on-model and flat-lay photo references.
try-on
fashion
clothing
image-to-image
Veo 3.1 Lite balances practical utility with professional capabilities, supporting Text-to-Video and Image-to-Video
stylized
transform
lipsync
text-to-video
recraft/v4/text-to-image
Recraft V4 was developed with designers to bring true visual taste to AI image generation. Built for brand systems and production-ready workflows, it goes beyond prompt accuracy delivering stronger composition, refined lighting, realistic materials, and a cohesive aesthetic. The result is imagery shaped by professional design judgment, ready for immediate real-world use without additional post-processing.
text-to-image
Generate videos from a first/last frame using Google's Veo 3.1 Fast
image-to-video
Generate Videos from images using Google's Veo 3.1
image-to-video
Generate fast speech from text prompts and different voices using the MiniMax Speech-02 Turbo model, which leverages advanced AI techniques to create high-quality text-to-speech.
speech
text-to-speech
mmaudio-v2
MMAudio generates synchronized audio given video and/or text inputs. It can be combined with video models to get videos with audio.
ai video
fast
video-to-video
Showing 197 to 224 of 1504 results