
Generate high quality and fast video clips from text and image prompts using PixVerse v4.5 fast
stylized
transform
text-to-video
phota/create-profile
Generate profiles using 30-50 images of a subject with Phota.
stylized
transform
typography
training

kandinsky5/text-to-video
Kandinsky 5.0 is a diffusion model for fast, high-quality text-to-video generation.
text-to-video
hunyuan3d/v2/mini/turbo
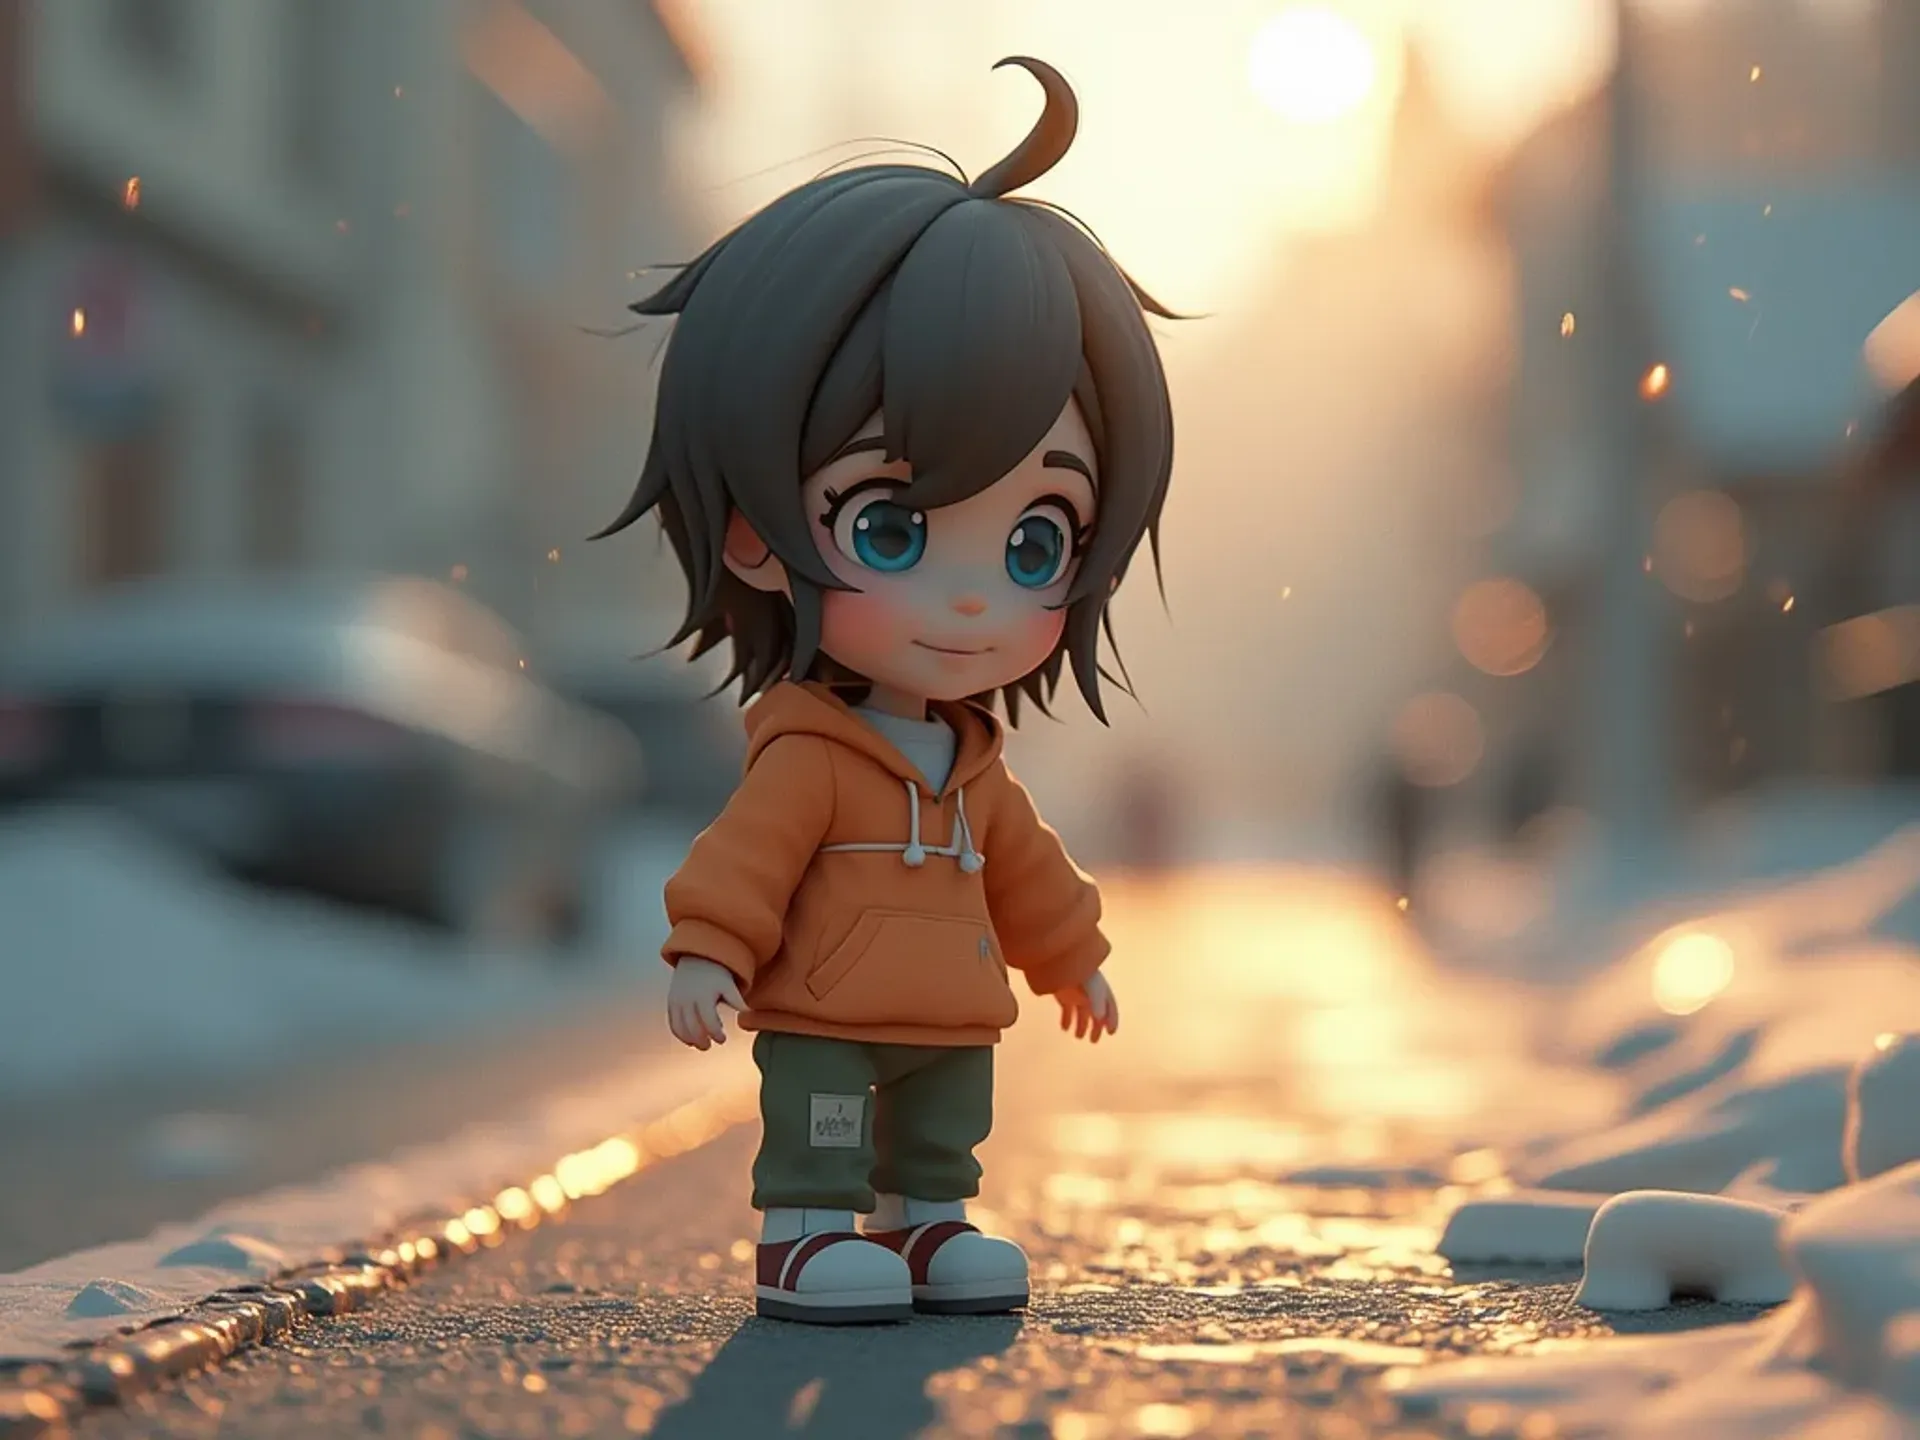
Generate 3D models from your images using Hunyuan 3D. A native 3D generative model enabling versatile and high-quality 3D asset creation.
stylized
image-to-3d
image-apps-v2/product-holding
Place products naturally in a person’s hands for realistic marketing visuals.
product
marketing
image-to-image
hunyuan3d/v2/mini
Generate 3D models from your images using Hunyuan 3D. A native 3D generative model enabling versatile and high-quality 3D asset creation.
stylized
image-to-3d

Generate videos from prompts using LTX Video-0.9.5
video
text-video
text-to-video
infinitalk/single-text
Infinitalk model generates a talking avatar video from a text and audio file. The avatar lip-syncs to the provided audio with natural facial expressions.
text-to-video

lcm-sd15-i2i
Produce high-quality images with minimal inference steps. Optimized for 512x512 input image size.
diffusion
lcm
real-time
image-to-image
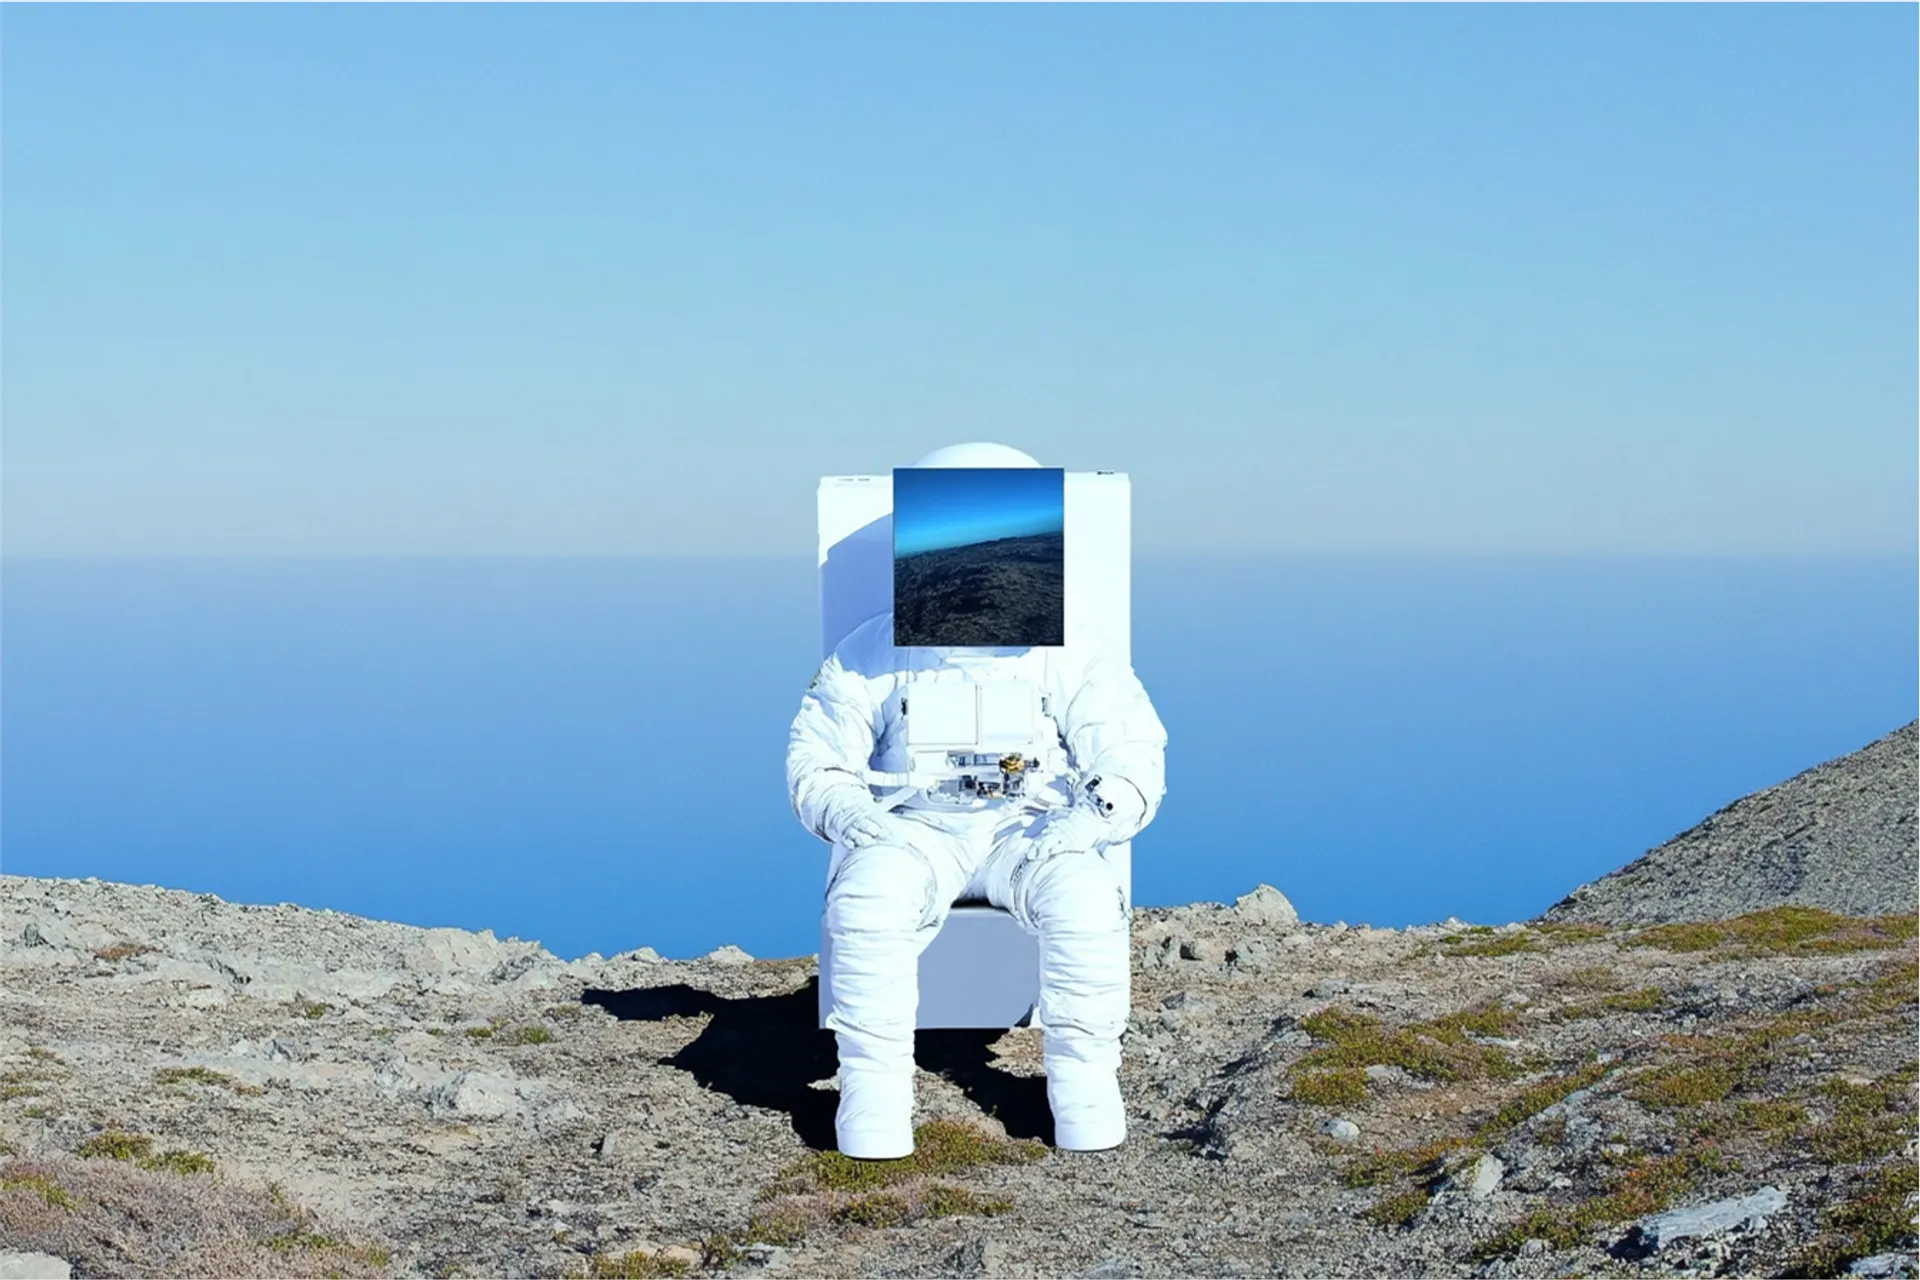
finegrain-eraser
Finegrain Eraser removes objects—along with their shadows, reflections, and lighting artifacts—using only natural language, seamlessly filling the scene with contextually accurate content.
utility
editing
image-to-image
hunyuan3d/v2/multi-view/turbo
Generate 3D models from your images using Hunyuan 3D. A native 3D generative model enabling versatile and high-quality 3D asset creation.
stylized
image-to-3d
Generate high quality video clips from text and image prompts using PixVerse v4
text-to-video
tripo3d/p1/text-to-3d
Generate 3D models from text descriptions using Tripo P1.
3d
3d-generation
tripo
text-to-3d
zonos
Clone voice of any person and speak anything in their voice using zonos' voice cloning.
voice cloning
text-to-audio
kokoro/mandarin-chinese
A highly efficient Mandarin Chinese text-to-speech model that captures natural tones and prosody.
speech
text-to-audio
hunyuan-video/video-to-video
Hunyuan Video is an Open video generation model with high visual quality, motion diversity, text-video alignment, and generation stability. Use this endpoint to generate videos from videos.
video to video
motion
video-to-video


Edit images from your prompts using Luma Photon. Photon is the most creative, personalizable, and intelligent visual models for creatives, bringing a step-function change in the cost of high-quality image generation.
image-to-image
personaplex
PersonaPlex is a real-time, full-duplex speech-to-speech conversational model that enables persona control through text-based role prompts and audio-based voice conditioning.
audio
audio-to-audio
longcat-video/image-to-video/480p
Generate long videos from images using LongCat Video
image-to-video
dreamshaper
Dreamshaper model.
stylized
diffusion
text-to-image
moonvalley/marey/i2v
Generate a video starting from an image as the first frame with Marey, a generative video model trained exclusively on fully licensed data.
image-to-video
sa2va/8b/image
Sa2VA is an MLLM capable of question answering, visual prompt understanding, and dense object segmentation at both image and video levels
multimodal
vision


Add custom LoRAs to Wan-2.1 is a text-to-video model that generates high-quality videos with high visual quality and motion diversity from images
"text to video"
"motion"
"lora"
text-to-video
omnigen-v2
OmniGen is a unified image generation model that can generate a wide range of images from multi-modal prompts. It can be used for various tasks such as Image Editing, Personalized Image Generation, Virtual Try-On, Multi Person Generation and more!
multimodal
editing
try-on
text-to-image
Showing 1105 to 1128 of 1496 results