Search models...Search by model, task, category and more
hunyuan3d/v2/multi-view/turbo
Generate 3D models from your images using Hunyuan 3D. A native 3D generative model enabling versatile and high-quality 3D asset creation.
stylized
image-to-3d
Generate high-quality videos with UGC-like avatars from audio
lipsync
audio-to-video



Super fast endpoint for the FLUX.1 [dev] model with LoRA support, enabling rapid and high-quality image generation using pre-trained LoRA adaptations for personalization, specific styles, brand identities, and product-specific outputs.
lora
personalization
text-to-image

FLUX1.1 [pro] ultra fine-tuned is the newest version of FLUX1.1 [pro] with a fine-tuned LoRA, maintaining professional-grade image quality while delivering up to 2K resolution with improved photo realism.
high-res
realism
text-to-image
id-v2v/relight
Change a video’s lighting using a relit reference frame while preserving the scene, subjects, and original performance. ID-V2V Relight propagates the new illumination across the video.
relighting
editing
cinematic
video-to-video
auto-caption
Automatically generates text captions for your videos from the audio as per text colour/font specifications
captioning
video
video-to-video

stable-audio-3/small/music/base/text-to-audio
Stable Audio 3 Small Music Base is the foundational 459 million parameter checkpoint generating full music compositions up to 2 minutes from text prompts, intended as the unmodified base for fine-tuning.
music
on-device
lightweight
text-to-audio

lightx/recamera
Use the capabilities of lightx to relight and recamera your videos.
recamera
relight
video-to-video
Generate high quality video clips with different effects using PixVerse v4
image-to-video

lumina-image/v2
Lumina-Image-2.0 is a 2 billion parameter flow-based diffusion transforer which features improved performance in image quality, typography, complex prompt understanding, and resource-efficiency.
diffusion
typography
style
text-to-image

image-apps-v2/product-photography
Generate professional product photography with realistic lighting and backgrounds.
product
marketing
image-to-image
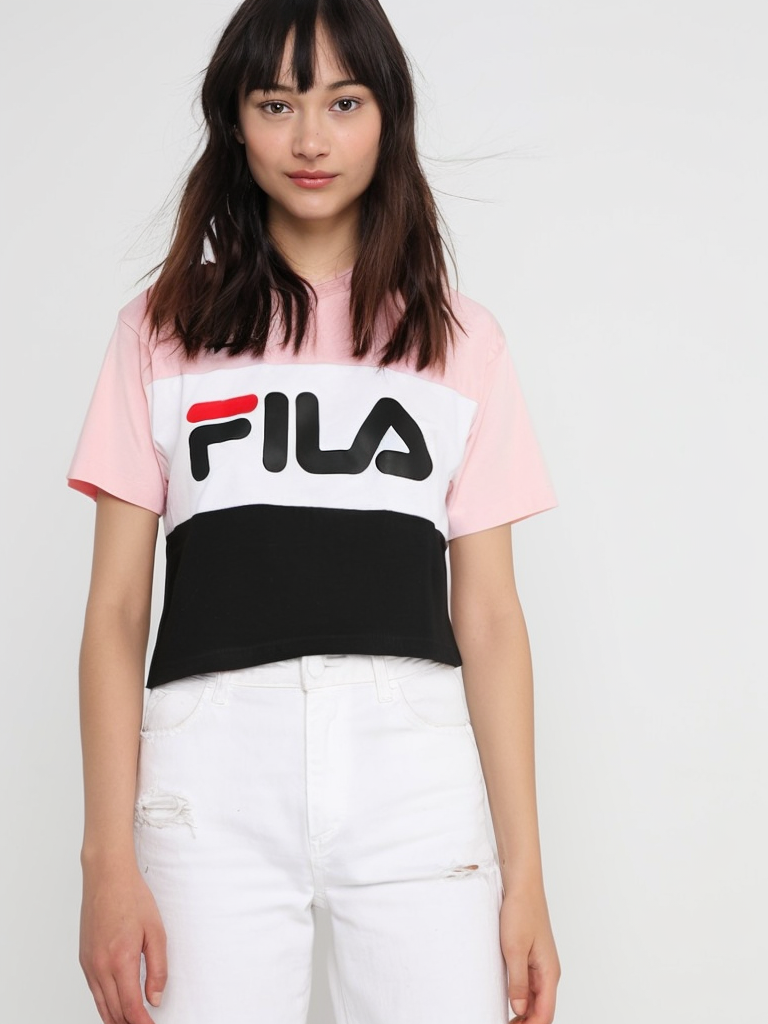
leffa/virtual-tryon
Leffa Virtual TryOn is a high quality image based Try-On endpoint which can be used for commercial try on.
try-on
fashion
clothing
image-to-image

longcat-video/text-to-video/720p
Generate long videos in 720p/30fps from text using LongCat Video
text-to-video

FLUX.3 is Black Forest Labs' frontier audio/video model. Re-render a previously generated draft at full quality — same seed, same motion, no re-planning.
stylized
transform
lipsync
video-to-video

longcat-image
LongCat image is a 6B parameter model excelling at multilingual text rendering, photorealism and deployment efficiency.
text-to-image

finegrain-eraser/bbox
Finegrain Eraser removes any object selected with a bounding box—along with its shadows, reflections, and lighting artifacts—seamlessly reconstructing the scene with contextually accurate content.
utility
editing
image-to-image
Train a MiniMax H3 LoRA on your own captioned clips for pure text-to-video generation with matching audio.
utility
editing
training

sdxl-controlnet-union/image-to-image
An efficent SDXL multi-controlnet image-to-image model.
diffusion
controlnet
composition
image-to-image
kokoro/mandarin-chinese
A highly efficient Mandarin Chinese text-to-speech model that captures natural tones and prosody.
speech
text-to-audio

ernie-image/lora
High-quality text-to-image model by Baidu. Supports English, Chinese, and Japanese prompts with built-in prompt expansion.
text-to-image
Generates 768p video with audio in a 16-bit pixel-art style from text prompts or an optional first-frame image. Supports durations of 5–15 seconds.
pixel-art
16-bit
animation
text-to-video
image-preprocessors/hed
Holistically-Nested Edge Detection (HED) preprocessor.
preprocess
detection
utility
image-to-image

marlin/find
Marlin is a 2B video VLM tuned for the two questions developers actually want to ask of their videos: what is happening, and when?
utility
editing
vision
stable-diffusion-v3-medium/image-to-image
Stable Diffusion 3 Medium (Image to Image) is a Multimodal Diffusion Transformer (MMDiT) model that improves image quality, typography, prompt understanding, and efficiency.
diffusion
editing
style
image-to-image
Showing 1129 to 1152 of 1432 results