Search models...Search by model, task, category and more
ByteDance's Seedream 5.0 Pro is flagship text-to-image model, with deep-thinking prompt understanding, native text in 14 languages, and precise control over dense layouts and structured designs.
realism
typography
stylized
text-to-image



Text-to-image generation with FLUX.2 [pro] from Black Forest Labs. Optimized for maximum quality, exceptional photorealism and artistic images.
image-to-image
new
Generate sound effects up to 30 seconds from a text prompt with ElevenLabs SFX v3, with optional seamless looping.
sound
sfx
audio
text-to-audio
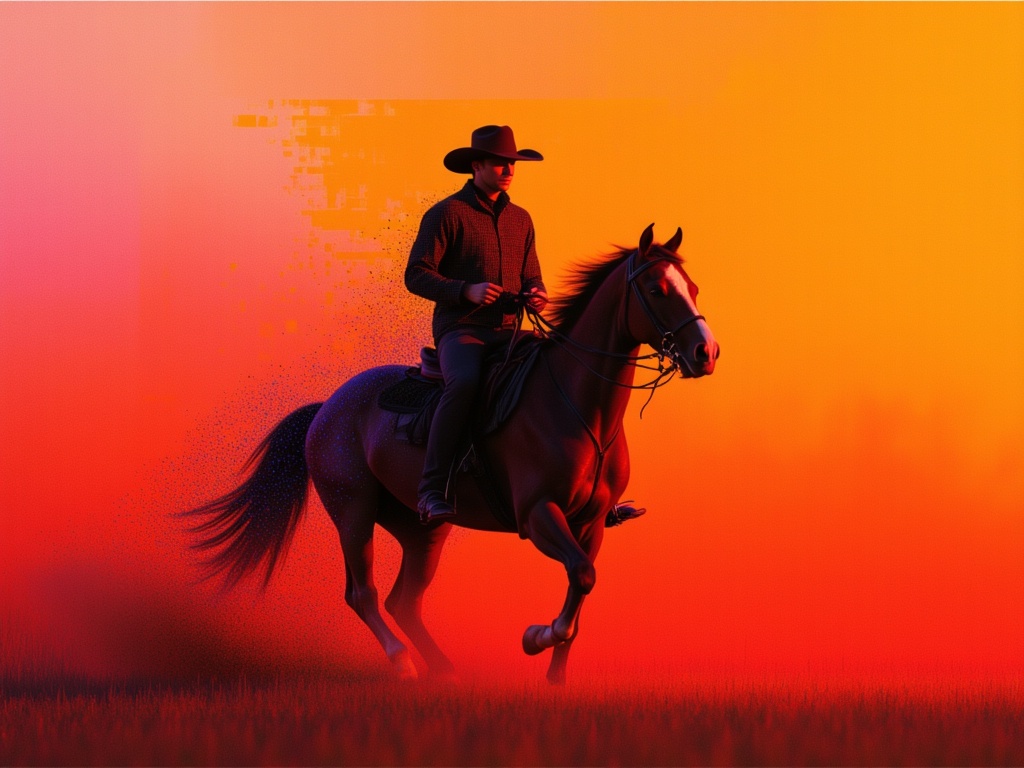
fal’s FLUX 3 Max is a post-trained variant of FLUX 3 Video, tuned for stronger prompt adherence and better visual quality while optimized for lower latency.
fast
audio
image-to-video

Generate speech from text prompts and different voices using the MiniMax Speech-2.8 HD model, which leverages advanced AI techniques to create high-quality text-to-speech.
text-to-speech


Z-Image Turbo is a super fast text-to-image model of 6B parameters developed by Tongyi-MAI.
turbo
z-image
fast
text-to-image
US-hosted ByteDance Seedance 2.5 generates video with native audio from up to 30 images, 10 videos, and 10 audio references. Supports reference-guided generation, video editing, and extension at 480p, 720p or 1080p.
stylized
transform
lipsync
image-to-video
Wan 3.0 is the latest generation AI video model, delivering enhanced motion smoothness, superior scene fidelity, and greater visual coherence.
stylized
transform
lipsync
video-to-video
new
Seedream 5.5 generates images from text prompts with configurable dimensions, batch generation, and support for transparent PNG backgrounds.
image-generation
transparent-background
text-to-image
Generate expressive speech with Gemini 3.8 Flash TTS. Choose from 30 voices, direct delivery with style instructions, and create single-speaker narration or two-speaker dialogue.
audio
dialogue
voiceover
text-to-speech


Kling AI Avatar v2 Standard: Endpoint for creating avatar videos with realistic humans, animals, cartoons, or stylized characters
image-to-video
fal's H3 Max is a post-trained variant of MiniMax H3, tuned for stronger prompt adherence and better aesthetics while co-optimized with our custom inference stack for higher throughput with no compromises on output quality
stylized
transform
lipsync
text-to-video
FLUX 3 Image Edit from Black Forest Labs makes precise local edits without changing the rest of the image, and combines up to 10 references into one balanced, well-composed result.
flux-3-image
black-forest-labs
multi-reference
image-to-image

Kling 2.6 Pro: Top-tier image-to-video with cinematic visuals, fluid motion, and native audio generation.
image-to-video
hunyuan-3d/v3.1/pro/image-to-3d
Generate 3D models from images with Hunyuan 3D Pro
3d
hunyuan
image-to-3d

wizper
[Experimental] Whisper v3 Large -- but optimized by our inference wizards. Same WER, double the performance!
transcription
speech
speech-to-text
Kling 4.0 generates videos from text prompts and image or video references at 720p or 1080p, with durations from 3 to 30 seconds and per-shot prompts.
reference-to-video
multi-shot
image-reference
video-to-video

A new-generation image creation model ByteDance, Seedream 4.0 integrates image generation and image editing capabilities into a single, unified architecture.
stylized
transform
editing
image-to-image

sync-lipsync/v3
sync-3 most powerful lipsync model yet, featuring native visual intelligence for professional-quality video.
stylized
transform
lipsync
video-to-video
Wan 3.0 is the latest generation AI video model, delivering enhanced motion smoothness, superior scene fidelity, and greater visual coherence.
stylized
transform
lipsync
image-to-video
meta/muse-image/edit
Meta's Muse Image model does precise edits that change only what you ask, stay coherent across turns, and compose from multiple reference images.
realism
typography
stylized
image-to-image

birefnet
bilateral reference framework (BiRefNet) for high-resolution dichotomous image segmentation (DIS)
background removal
segmentation
high-res
image-to-image
Wan 3.0 Prime Image-to-Video turns still images into dynamic, cinematic sequences with rapid turnaround, natural motion, and excellent visual continuity. It preserves the identity, composition, and atmosphere of the source image while introducing expressive movement, camera dynamics, and richly detailed animation.
image
video
image-to-video
H3 Max Lip Sync generates a video from an image and supplied audio, synchronizing mouth movements to the soundtrack. It supports optional transcription guidance and output resolutions from 480p to 2K.
lipsync
animation
audio
image-to-video
Showing 49 to 72 of 1432 results