Search models...Search by model, task, category and more
new
meshy/rigging/multi-animation
Meshy auto-rigs a humanoid 3D model fitting a skeleton and binding the mesh, then applies several motion presets from its animation library
stylized
transform
3d
3d-to-3d
Adds synchronized sound effects to a video and returns the video with the sound mixed in. Speech is preserved by default, with text prompts for off-screen sounds and ambience.
sound-effects
foley
speech-aware
video-to-video
sam2/auto-segment
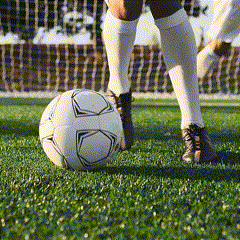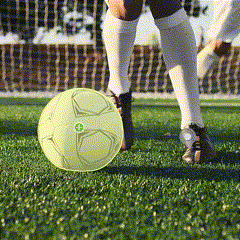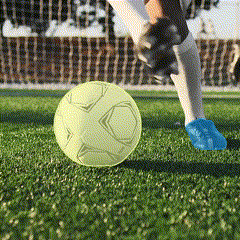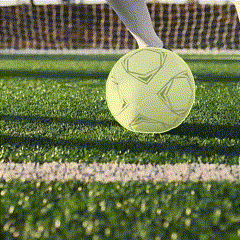
SAM 2 is a model for segmenting images automatically. It can return individual masks or a single mask for the entire image.
segmentation
mask
image-to-image
new
HeyGen Voice Turbo is the fast, low-cost tier of HeyGen Voice, with library voices and instant cloning from a reference clip.
heygen
tts
voice cloning
text-to-speech

Seedance 1.0 Pro, a high quality video generation model developed by Bytedance.
text-to-video
tripo3d/p1/image-to-3d
Generate 3D models from a single image using Tripo P1.
3d
3d-generation
tripo
image-to-3d

pixelcut/video-background-removal
Pixelcut's Video Background Remover is an AI segmentation model that erases backgrounds frame by frame, with seamless temporal consistency.
transform
utility
rembg
video-to-video
stable-audio-3/medium/audio-to-audio
Stable Audio 3 Medium audio-to-audio is a 1.4 billion parameter latent diffusion model that transforms an input audio clip into new stereo variations up to 6 minutes guided by a text prompt.
music
style-transfer
remix
audio-to-audio
new
Gemini Omni Flash 1.2 is Google's multimodal video model. This endpoint upscales a video of up to 15 seconds to a selected resolution of up to 4K, with an optional text instruction to guide the result.
upscale
utility
video-to-video

zonos2
Zonos2 is a text-to-speech model that clones a voice from a short sample and speaks naturally across many languages.
tts
voice cloning
text-to-speech


Bria Virtual Try-On edits a person photo to show the subject wearing garments or accessories from one to three reference images, guided by optional text instructions. Built on FIBO-Edit-1.5, it supports multi-garment changes and preserves the source aspect ratio by default.
virtual try-on
fashion tech
apparel
image-to-image

LTX-2.3 is a high-quality, fast AI video model available in Pro and Fast variants for text-to-video, image-to-video, and audio-to-video.
stylized
transform
lipsync
audio-to-video
new
meshy/rigging
Rig humanoid 3D models from GLB URLs with Meshy, returning rigged GLB/FBX files plus basic animations.
rigging
3d-to-3d
video-upscaler
The video upscaler endpoint uses RealESRGAN on each frame of the input video to upscale the video to a higher resolution.
video generation
video to video
ai video
video-to-video

image-apps-v2/virtual-try-on
Try on clothes virtually by combining person and clothing images.
fashion
try-on
virtual-try-on
image-to-image

microsoft/mai-image-2.5/edit
MAI-Image-2.5 is Microsoft's photorealistic image generation and editing model that turns text prompts or uploaded images into high-quality, design-ready visuals with fine-grained, pixel-level control.
realism
typography
stylized
image-to-image



Image-to-image editing with LoRA support for FLUX.2 [klein] 9B Base from Black Forest Labs. Specialized style transfer and domain-specific modifications.
image-to-image

Edits generated video across multiple conversational turns while preserving scene coherence. Applies iterative changes through natural-language instructions without regenerating the full sequence from scratch.
stylized
transform
lipsync
video-to-video

LTX-2.5 is Lightricks' open-source audio-video model. This endpoint generates synchronized video and audio from a text prompt in a single pass, in a quality-optimized mode for final, high-fidelity output.
stylized
transform
lipsync
text-to-video
new
LTX 2.5 Upscale increases the resolution of existing H.264 or HEVC video to 1080p, 4K, or 8K. It preserves the source aspect ratio, retains audio in stereo, and rounds the source frame rate to an integer.
upscale
restoration
4k
video-to-video
tripo3d/tripo/v2.5/multiview-to-3d
State of the art Multiview to 3D Object generation. Generate 3D models from multiple images!
stylized
multiview
image-to-3d
hitem3d/hi3d/v3.0/image-to-3d
Generate 3D models from a single image with Hi3D V3.0.
3d
mesh
image-to-3d


Wan 2.7 is the latest generation AI video model, delivering enhanced motion smoothness, superior scene fidelity, and greater visual coherence.
stylized
transform
lipsync
image-to-video

Seed Speech developed by ByteDance, is a family of large-scale text-to-speech models capable of synthesizing speech that is virtually indistinguishable from human speech.
stylized
transform
lipsync
text-to-speech
Showing 505 to 528 of 1432 results