Showing 28 of 1491 results


Text-to-image generation with FLUX.2 [klein] 9B from Black Forest Labs and custom LoRA.
text-to-image
openrouter/router/enterprise
Run any LLM (Large Language Model) with fal, powered by OpenRouter.
llm


Wan-2.1 is a text-to-video model that generates high-quality videos with high visual quality and motion diversity from text prompts
text to video
motion
text-to-video


VEED Fabric 1.0 is an image-to-video API that turns any image into a talking video
lipsync
avatar
image-to-video

Generate character-consistent videos from reference images using PixVerse C1, with subject and background references.
video-generation
reference-to-video
pixverse
image-to-video


Prompt-free object removal from an image and mask, erasing objects with their shadows and reflections and reconstructing the scene cleanly.
utility
editing
image-to-image


Extend Veo-Created Videos up to 30 seconds
extend-video
video-to-video
microsoft/mai-image-2.5-pro
Generate high-fidelity, design-ready images with precise typography, strong prompt alignment, and rich visual detail using Microsoft's flagship MAI Image 2.5 Pro.
photorealism
typography
illustration
text-to-image
FLUX Control LoRA Depth is a high-performance endpoint that uses a control image to transfer structure to the generated image, using a depth map.
lora
style transfer
text-to-image
florence-2-large/open-vocabulary-detection
Florence-2 is an advanced vision foundation model that uses a prompt-based approach to handle a wide range of vision and vision-language tasks
multimodal
vision
detection
image-to-image
pixal3d
Pixal3D turns a single image into a high-fidelity 3D model with detailed geometry and realistic textures.
stylized
transform
image-to-3d
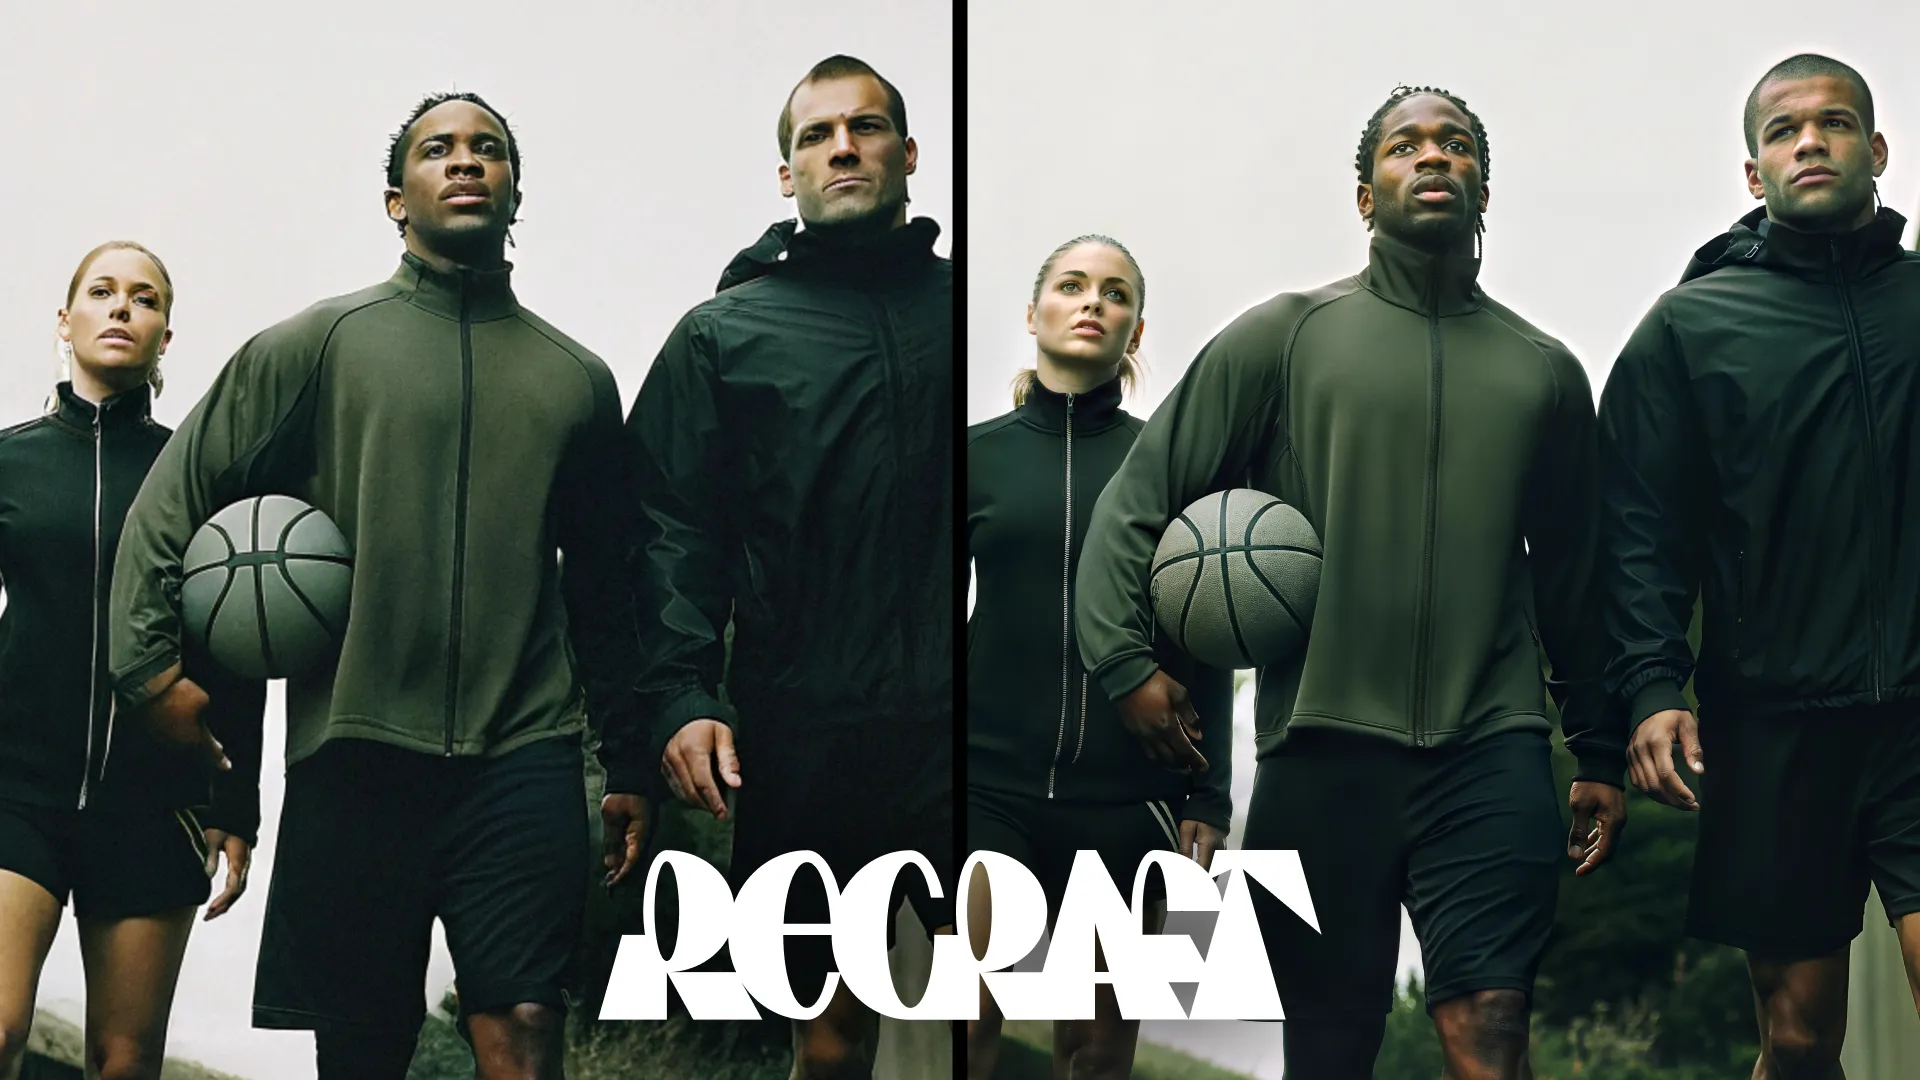
recraft/upscale/creative
Enhances a given raster image using the 'creative upscale' tool, increasing image resolution, making the image sharper and cleaner.
upscaling
image-to-image

musetalk
MuseTalk is a real-time high quality audio-driven lip-syncing model. Use MuseTalk to animate a face with your own audio.
animation
lip sync
real-time
image-to-video
Precise camera position and angle control (rotation, zoom, vertical movement)
stylized
transform
image-to-image
tripo3d/p1/image-to-3d
Generate 3D models from a single image using Tripo P1.
3d
3d-generation
tripo
image-to-3d

flashtalk
Audio-driven talking avatar generation powered by the SoulX-FlashTalk 14B model.
avatar
talking-head
audio-driven
audio-to-video

Generate videos from prompts and images using LTX Video-0.9.7 13B Distilled and custom LoRA
video
ltx-video
image-to-video


Luma Uni-1 Max Edit applies text-guided edits to a source image at maximum fidelity, holding the original structure while honoring reference images for precise, high-detail revisions.
realism
typography
stylized
image-to-image


Edit an existing video using natural-language instructions, transforming subjects, settings, and style while retaining the original motion structure.
video-to-video
new


US hosted version of ByteDance's most advanced text-to-video model. Cinematic output with native audio, multi-shot editing, real-world physics, and director-level camera control.
stylized
transform
lipsync
text-to-video
Generate long videos from prompts and images using LTX Video-0.9.8 13B Distilled and custom LoRA
video
ltx-video
image-to-video
image2svg
Image2SVG transforms raster images into clean vector graphics, preserving visual quality while enabling scalable, customizable SVG outputs with precise control over detail levels.
utility
editing
image-to-image

hy-wu-edit
Image editing with HY-WU. Transfer outfits, swap faces, and blend textures instantly—no finetuning needed, just describe what you want and provide reference images.
image-to-image

Pixverse Effects
image-to-video
object-removal/mask
Removes mask-selected objects and their visual effects, seamlessly reconstructing the scene with contextually appropriate content.
utility
editing
image-to-image
Happy Horse 1.1 is Alibaba's #1-ranked video model. This text-to-video endpoint generates 1080p video with synchronized native audio and multilingual lip-sync from a text prompt alone.
happy-horse
video
text
text-to-video
recraft/v4.1/pro/text-to-vector
Recraft V4.1 Pro Vector generates large-format, fully editable SVGs with the structural clarity professional illustrators expect. Built for poster art, complex brand assets, and detailed scene illustration, it scales without losing geometric integrity.
stylized
transform
typography
text-to-image
Wan-2.1 flf2v generates dynamic videos by intelligently bridging a given first frame to a desired end frame through smooth, coherent motion sequences.
image to video
motion
image-to-video
Showing 561 to 588 of 1491 results