Search models...Search by model, task, category and more
new
Seedream 5.5 decomposes an image into a base image and independently editable PNG layers, with layer positions, stacking order, and optional text recognition.
image-layers
image-decomposition
transparency
image-to-image
recraft/v4.1/text-to-image
Recraft V4.1 builds on the design-first foundation of V4 with sharper prompt control and cleaner composition. Tuned for brand systems and editorial work, it delivers production-ready raster images that hold up next to a designer's hand.
stylized
transform
typography
text-to-image



Train styles, people and other subjects at blazing speeds.
lora
personalization
training

meshy/rigging/multi-animation
Meshy auto-rigs a humanoid 3D model fitting a skeleton and binding the mesh, then applies several motion presets from its animation library
stylized
transform
3d
3d-to-3d
ace-step
Generate music with lyrics from text using ACE-Step
text-to-music
text-to-audio
Image editing endpoint for the fast Lite version of Seedream 5.0, supporting high quality intelligent image editing with multiple inputs.
bytedance
seedream-5.0-lite
edit
image-to-image

Generate speech from text prompts and different voices using the MiniMax Speech-2.6 HD model, which leverages advanced AI techniques to create high-quality text-to-speech.
text-to-speech



Qwen-Image is an image generation foundation model in the Qwen series that achieves significant advances in complex text rendering and precise image editing.
text-to-image
meshy/v7.1/multi-image-to-3d
Meshy 7.1 is the latest standard model from Meshy. It generates 3D models from one to four views of the same object, with optional textures and PBR maps.
3d
multi-image
textures
image-to-3d

video-understanding
A video understanding model to analyze video content and answer questions about what's happening in the video based on user prompts.
utility
vision
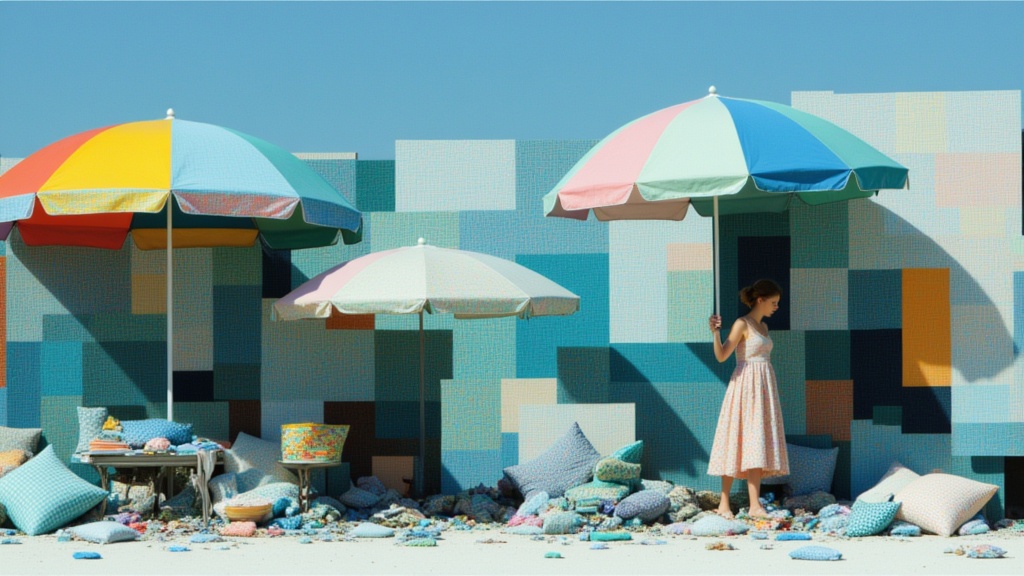
ByteDance's most advanced text-to-video model, fast tier. Lower latency and cost with cinematic output, native audio, multi-shot editing, and director-level camera control.
stylized
transform
lipsync
text-to-video

Generates images from a text prompt at resolutions up to 2048×2048, with automatic prompt rewriting and prompt-guided resolution selection, building on Qwen's strength in complex text rendering and precise prompt adherence
stylized
transform
typography
text-to-image
Generate realistic lipsync from any audio using VEED's model.
lipsync
avatar
video-to-video
Gemini Omni Flash 1.1 is Google's multimodal video model. This endpoint generates video with synchronized native audio from a text prompt, grounded in Gemini's real-world knowledge and physics understanding, with cinematic camera control expressed in natural language.
stylized
transform
lipsync
text-to-video


Edit an existing video using natural-language instructions, transforming subjects, settings, and style while retaining the original motion structure.
video-to-video
fal’s FLUX 3 Max is a post-trained variant of FLUX 3 Video, tuned for stronger prompt adherence and better visual quality while optimized for lower latency.
keyframes
control
image-to-video

stable-audio
Open source text-to-audio model.
music
text-to-audio
kokoro/american-english
Kokoro is a lightweight text-to-speech model that delivers comparable quality to larger models while being significantly faster and more cost-efficient.
speech
text-to-audio
Gemini 3.1 Flash Image (a.k.a. Nano Banana 2) is Google's new state-of-the-art fast image generation and editing model
image-to-image
Clone your voices using Qwen3-TTS Clone-Voice model with zero shot cloning capabilities and use it on text-to-speech models to create speeches of yours!
clone-voice
voice-clone
audio-to-audio

sam-3/3d-objects
SAM 3D enables precise 3D reconstruction of objects from real images, while accurately reconstructing their geometry and texture.
3d
object
image-to-3d

Generate high-fidelity images from text in seconds with Krea 2 Turbo, the speed-optimized open-source version of Krea 2, preserving its aesthetic range for rapid ideation.
stylized
transform
typography
text-to-image

Experimental version of FLUX.1 Kontext [max] with multi image handling capabilities
image-to-image

sam-3/video
SAM 3 is a unified foundation model for promptable segmentation in images and videos. It can detect, segment, and track objects using text or visual prompts such as points, boxes, and masks.
segmentation
mask
real-time
video-to-video
Showing 241 to 264 of 1432 results