Search models...Search by model, task, category and more

Generate video with audio from reference videos using LTX-2.3 Distilled
video-to-video



Remove video backgrounds in real time with Bria’s VRMBG 3.0 model. Built for live streaming, real-time video apps, content creation, and low-latency workflows that need fast, accurate background removal.
bria
video
background-removal
video-to-video

Convert line drawings and sketches into photorealistic, fully colored images with preserved structure. Trained exclusively on licensed data for safe commercial and design use.
sketch-to-image
bria
fibo-edit
image-to-image

kandinsky5-pro/image-to-video
Kandinsky 5.0 Pro is a diffusion model for fast, high-quality image-to-video generation.
image-to-video

image-editing/broccoli-haircut
Transform your character's hair into broccoli style while keeping the original characters likeness
stylized
transform
image-to-image
kotoba-technologies/kotoba-sts/v1/realtime_voice
Speak in one language, hear it in another. Streaming speech-to-speech translation with the translated text alongside the audio.
commercial-use
translation
japanese
speech-to-speech

vidu/reference-to-image
Vidu Reference-to-Image creates images by using a reference images and combining them with a prompt.
images-to-image
image-to-image

fooocus/image-prompt
Default parameters with automated optimizations and quality improvements.
stylized
text-to-image

moondream2/point-object-detection
Moondream2 is a highly efficient open-source vision language model that combines powerful image understanding capabilities with a remarkably small footprint.
image-to-image
vision

image composition model. Combine and blend multiple image parts into complex compositions through natural language and sequential editing.
bria
fibo-edit
blend
image-to-image

Generate video with audio from images using LTX-2.3 and custom LoRA
image-to-video
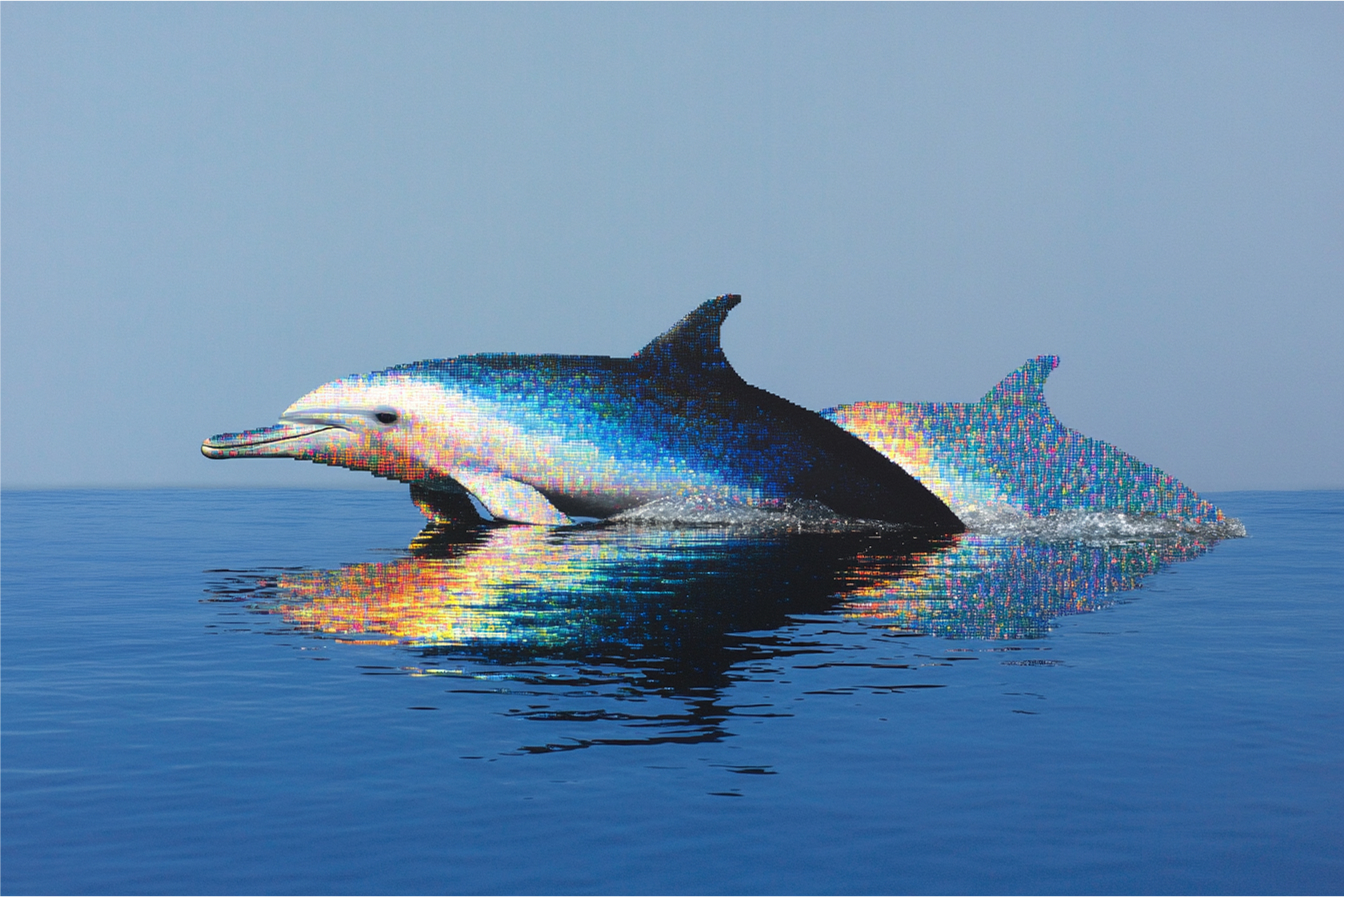
image-editing/weather-effect
Add realistic weather effects like snowfall, rain, or fog to your photos while maintaining the scene's mood.
stylized
transform
image-to-image

Generate video clips more accurately with respect to natural language descriptions and using camera movement instructions for shot control.
motion
transformation
camera-controls
text-to-video

Generate video with audio from videos using LTX-2.3 Distilled
video-to-video

one-to-all-animation/1.3b
One-to-All Animation is a pose driven video model that animates characters from a single reference image, enabling flexible, alignment-free motion transfer across diverse styles and scenes
video to video
motion
video-to-video
leffa/pose-transfer
Leffa Pose Transfer is an endpoint for changing pose of an image with a reference image.
pose
utility
image-to-image

Day to Night for high-quality video using LTX-2.3
day
night
video-to-video

thinksound/audio
Generate realistic audio from a video with an optional text prompt
audio-generation
video-to-audio
video-to-video

tada/1b/text-to-speech
A unified speech-language model that synchronizes speech and text into a single, cohesive stream via 1:1 alignment. Lighter 1B variant
audio-to-audio

emu-3.5-image/edit-image
Edit images with a text prompt using Emu 3.5 Image
image-to-image
Generate high quality video clips with different effects using PixVerse v3.5
image-to-video

Extend videos using LTX Video-0.9.7 13B Distilled and custom LoRA
video
ltx-video
extend-video
video-to-video
new
mureka/v8/generate/instrumental
Generates instrumental music from a text description or uploaded instrumental reference, with support for multiple variations.
music
instrumental
music generation
text-to-audio
Train a MiniMax H3 LoRA on first/last/both keyframe signatures, teaching it to generate video with audio that starts on one image and lands on another.
utility
editing
training
Showing 1249 to 1272 of 1432 results