Showing 1249 to 1272 of 1667 results
ace-step/audio-outpaint
Extend the beginning or end of provided audio with lyrics and/or style using ACE-Step
audio-outpaint
audio-extend
audio-to-audio
ace-step/audio-inpaint
Modify a portion of provided audio with lyrics and/or style using ACE-Step
audio-inpaint
audio-repaint
audio-to-audio
ace-step/audio-to-audio
Generate music from a lyrics and example audio using ACE-Step
audio-edit
audio-to-audio
ace-step/prompt-to-audio
Generate music from a simple prompt using ACE-Step
text-to-music
text-to-audio
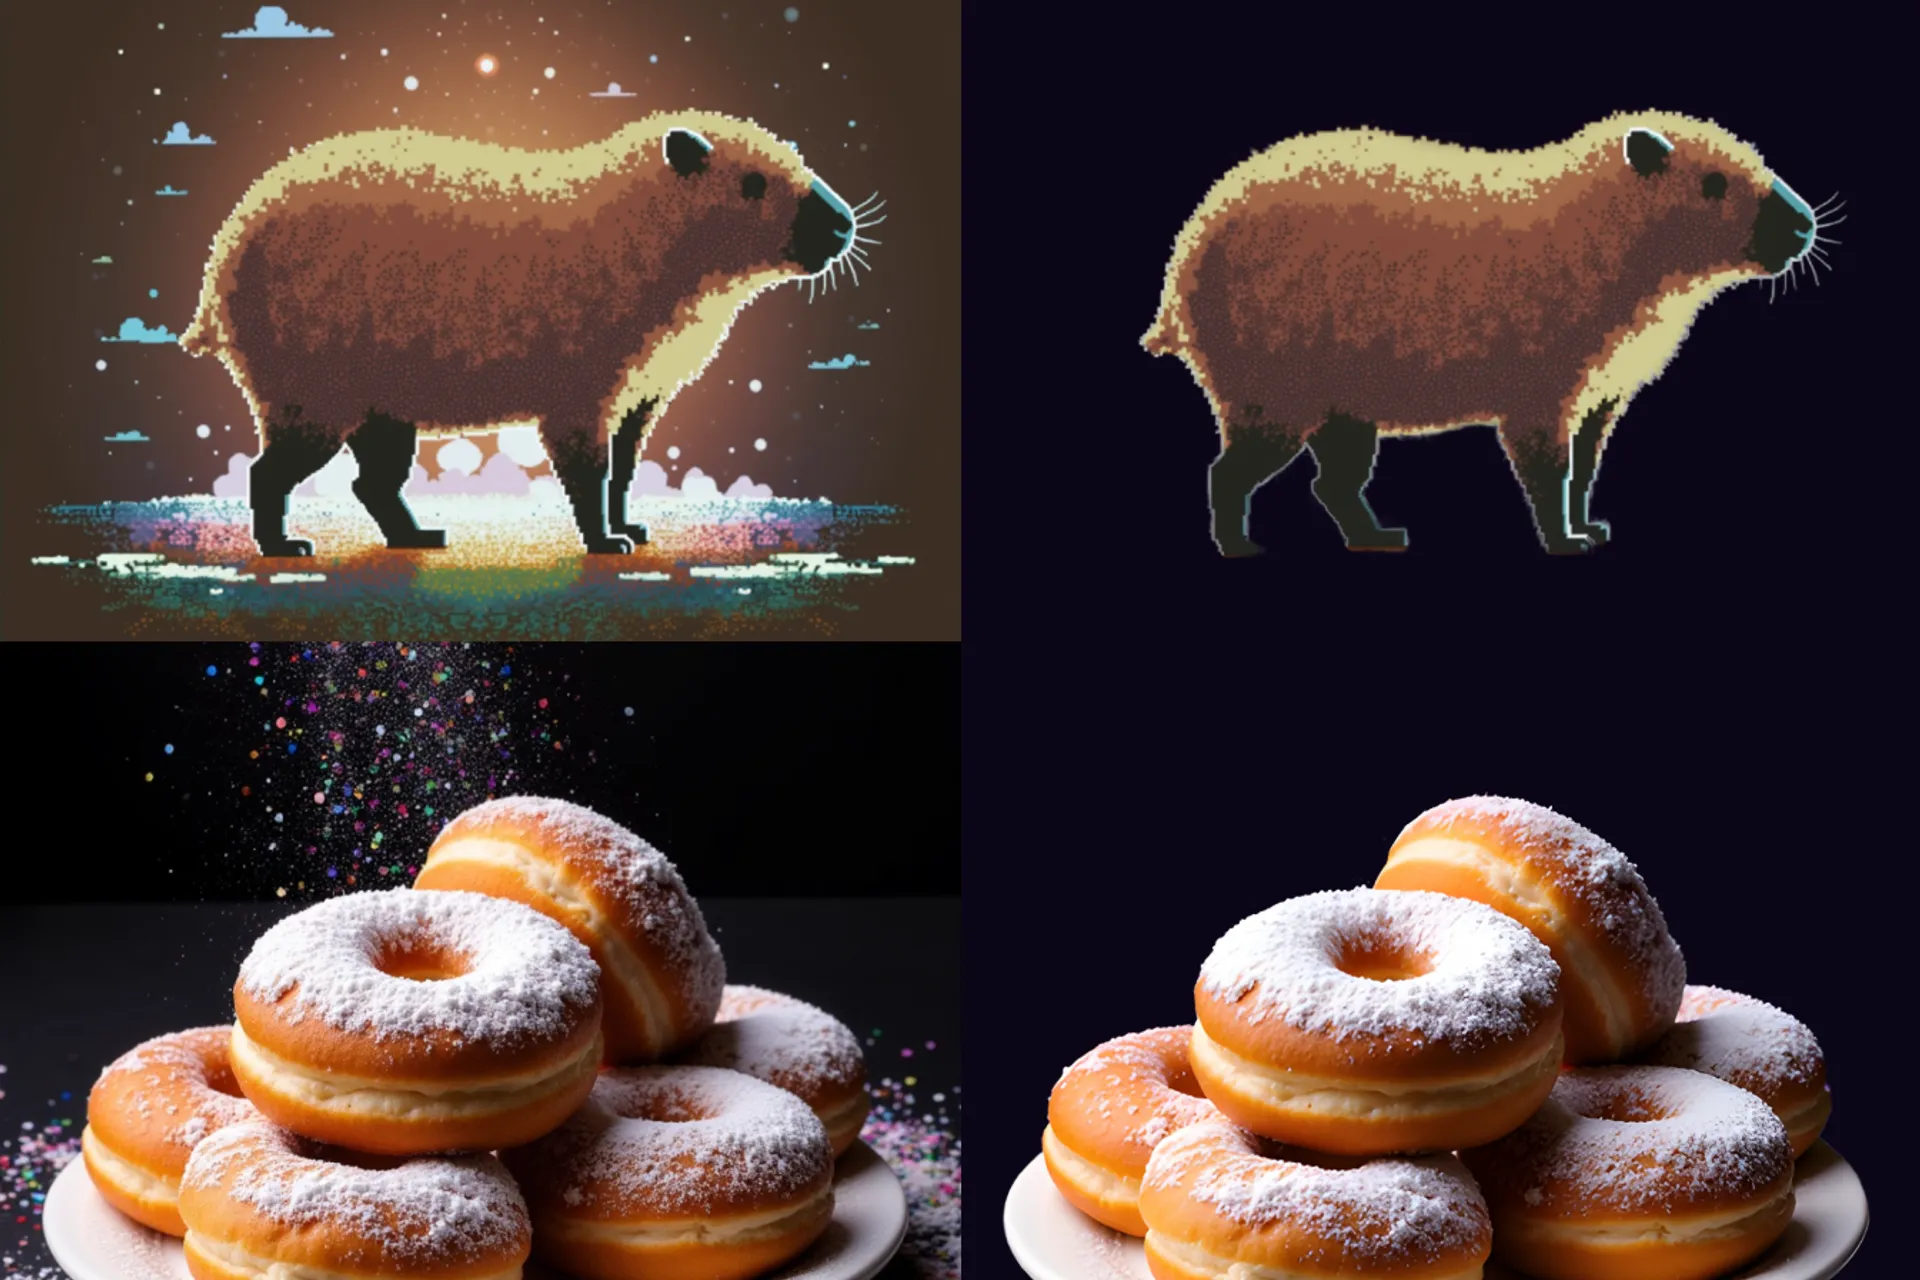
smoretalk-ai/rembg-enhance
Rembg-enhance is optimized for 2D vector images, 3D graphics, and photos by leveraging matting technology.
background removal
image editing
utility
image-to-image
vidu/q1/start-end-to-video
Vidu Q1 Start-End to Video generates smooth transition 1080p videos between specified start and end images.
stylized
transform
image-to-video
vidu/q1/text-to-video
Vidu Q1 Text to Video generates high-quality 1080p videos with exceptional visual quality and motion diversity
stylized
transform
text-to-video
vidu/q1/image-to-video
Vidu Q1 Image to Video generates high-quality 1080p videos with exceptional visual quality and motion diversity from a single image
stylized
transform
image-to-video
ace-step
Generate music with lyrics from text using ACE-Step
text-to-music
text-to-audio


Train LTX Video 0.9.7 for custom styles and effects.
deprecated
ltx-video
fine-tuning
training
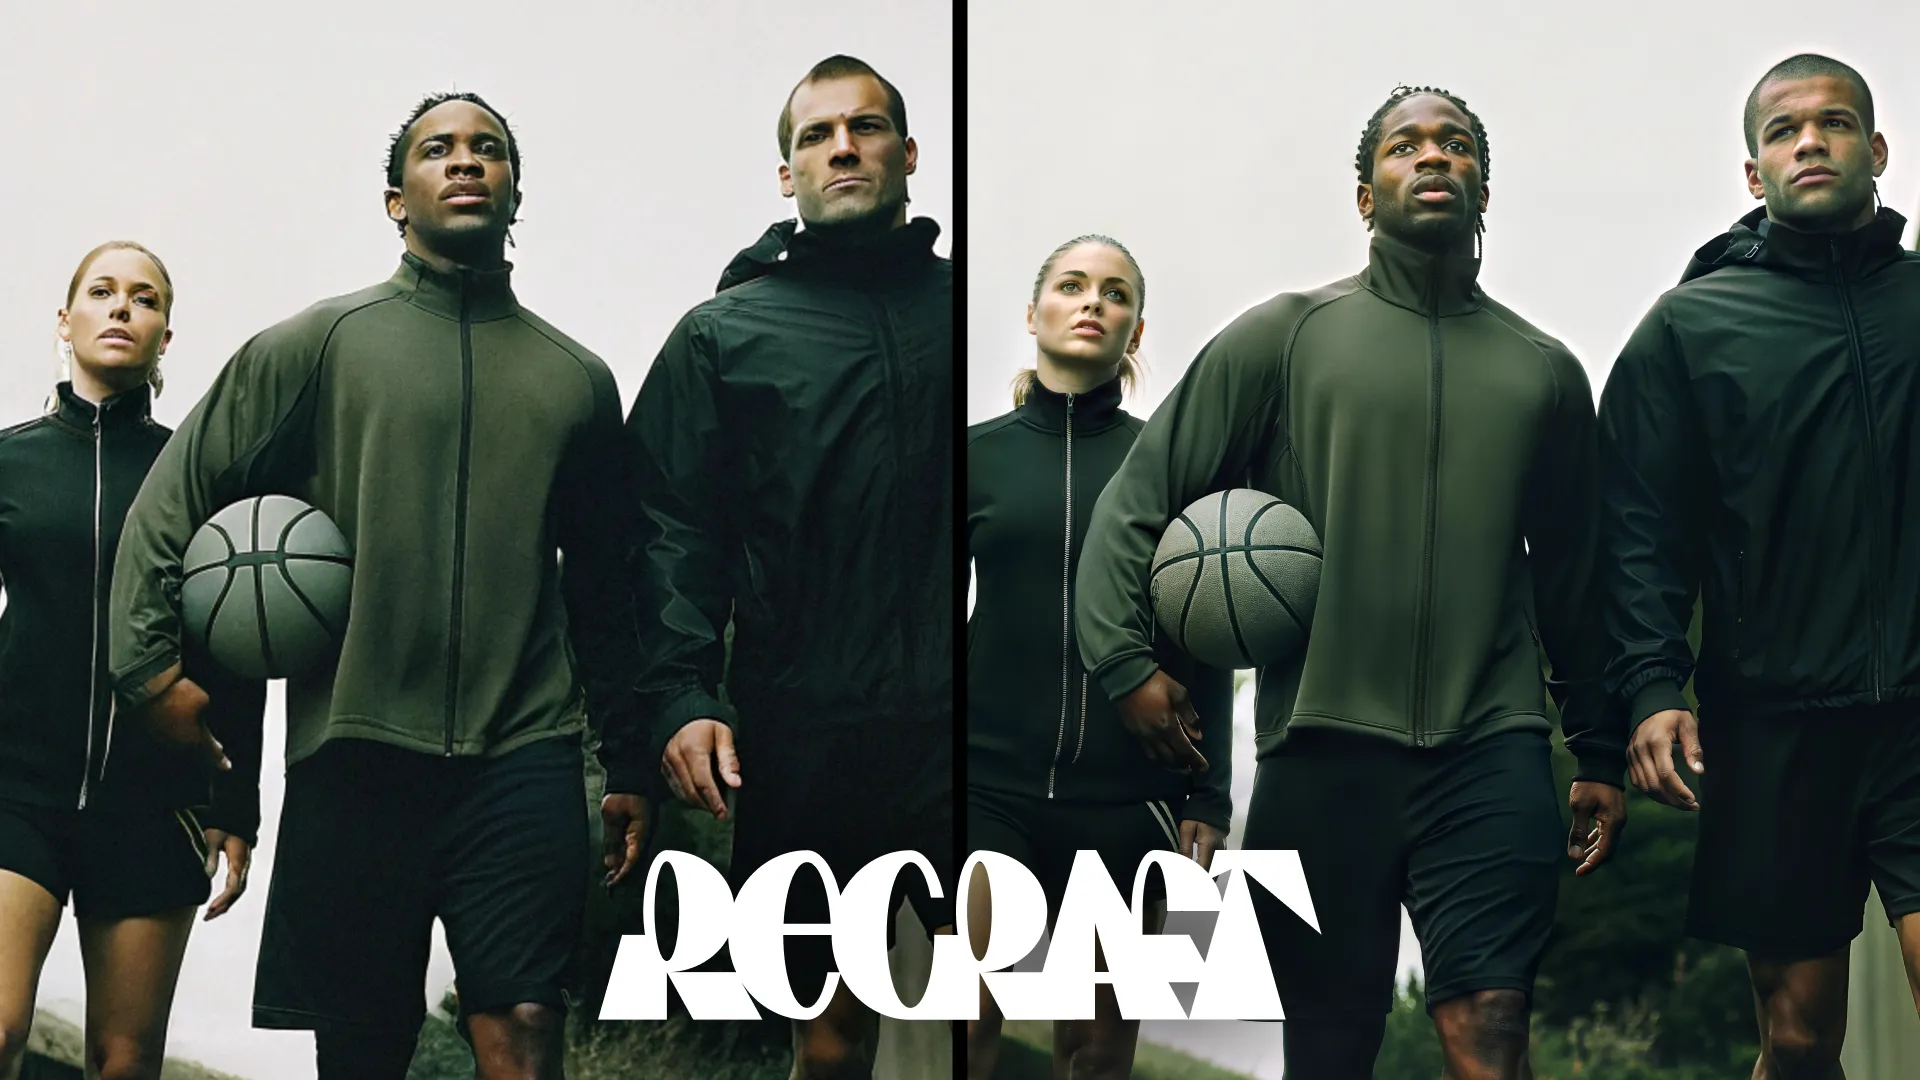
recraft/upscale/creative
Enhances a given raster image using the 'creative upscale' tool, increasing image resolution, making the image sharper and cleaner.
upscaling
image-to-image
recraft/upscale/crisp
Enhances a given raster image using 'crisp upscale' tool, boosting resolution with a focus on refining small details and faces.
upscaling
image-to-image
recraft/v3/create-style
Recraft V3 Create Style is capable of creating unique styles for Recraft V3 based on your images.
style
vector
personalization
training
recraft/v3/image-to-image
Recraft V3 is a text-to-image model with the ability to generate long texts, vector art, images in brand style, and much more. As of today, it is SOTA in image generation, proven by Hugging Face's industry-leading Text-to-Image Benchmark by Artificial Analysis.
vector
typography
style
image-to-image
recraft/v3/text-to-image
Recraft V3 is a text-to-image model with the ability to generate long texts, vector art, images in brand style, and much more. As of today, it is SOTA in image generation, proven by Hugging Face's industry-leading Text-to-Image Benchmark by Artificial Analysis.
vector
typography
style
text-to-image
Deprecated. Use fal-ai/ltx-video-13b-dev or fal-ai/ltx-video-13b-distilled instead.
deprecated
video-to-video

Clone a voice from a sample audio and generate speech from text prompts using the MiniMax model, which leverages advanced AI techniques to create high-quality text-to-speech.
speech
text-to-speech
Generate fast speech from text prompts and different voices using the MiniMax Speech-02 Turbo model, which leverages advanced AI techniques to create high-quality text-to-speech.
speech
text-to-speech
Deprecated. Use fal-ai/ltx-video-13b-dev or fal-ai/ltx-video-13b-distilled instead.
deprecated
video
image-to-video
text-to-video
video-to-video
Generate speech from text prompts and different voices using the MiniMax Speech-02 HD model, which leverages advanced AI techniques to create high-quality text-to-speech.
speech
text-to-speech
Deprecated. Use fal-ai/ltx-video-13b-dev or fal-ai/ltx-video-13b-distilled instead.
deprecated
video
image-to-video

Generate images from text and a reference image using MiniMax Image-01 for consistent character appearance.
stylized
transform
image-to-image
Generate high quality images from text prompts using MiniMax Image-01. Longer text prompts will result in better quality images.
stylized
realism
text-to-image
hidream-i1-full/image-to-image
HiDream-I1 full is a new open-source image generative foundation model with 17B parameters that achieves state-of-the-art image generation quality within seconds.
hidream
image-to-image
Showing 1249 to 1272 of 1667 results