fal-ai/flux-3-action/so101
FLUX 3 Action turns what the robot sees into what it does next. Give it the scene camera image, the wrist camera image, the current SO-101 joint state (shoulder pan, shoulder lift, elbow flex, wrist flex, wrist roll, gripper) and a plain-language instruction such as "Pick up the yellow cube and place it inside the black rectangle". It returns a chunk of 42 target joint positions at 30 Hz, that is 1.4 s of motion. In a control loop, execute the first 32 steps (about 1 s), then call again with fresh images and joint state.
Inference
Commercial use
Input
Hint: Drag and drop image files from your computer, images from web pages, paste from clipboard (Ctrl/Cmd+V), or provide a URL. Accepted file types: jpg, jpeg, png, webp, gif, avif, heic, heif
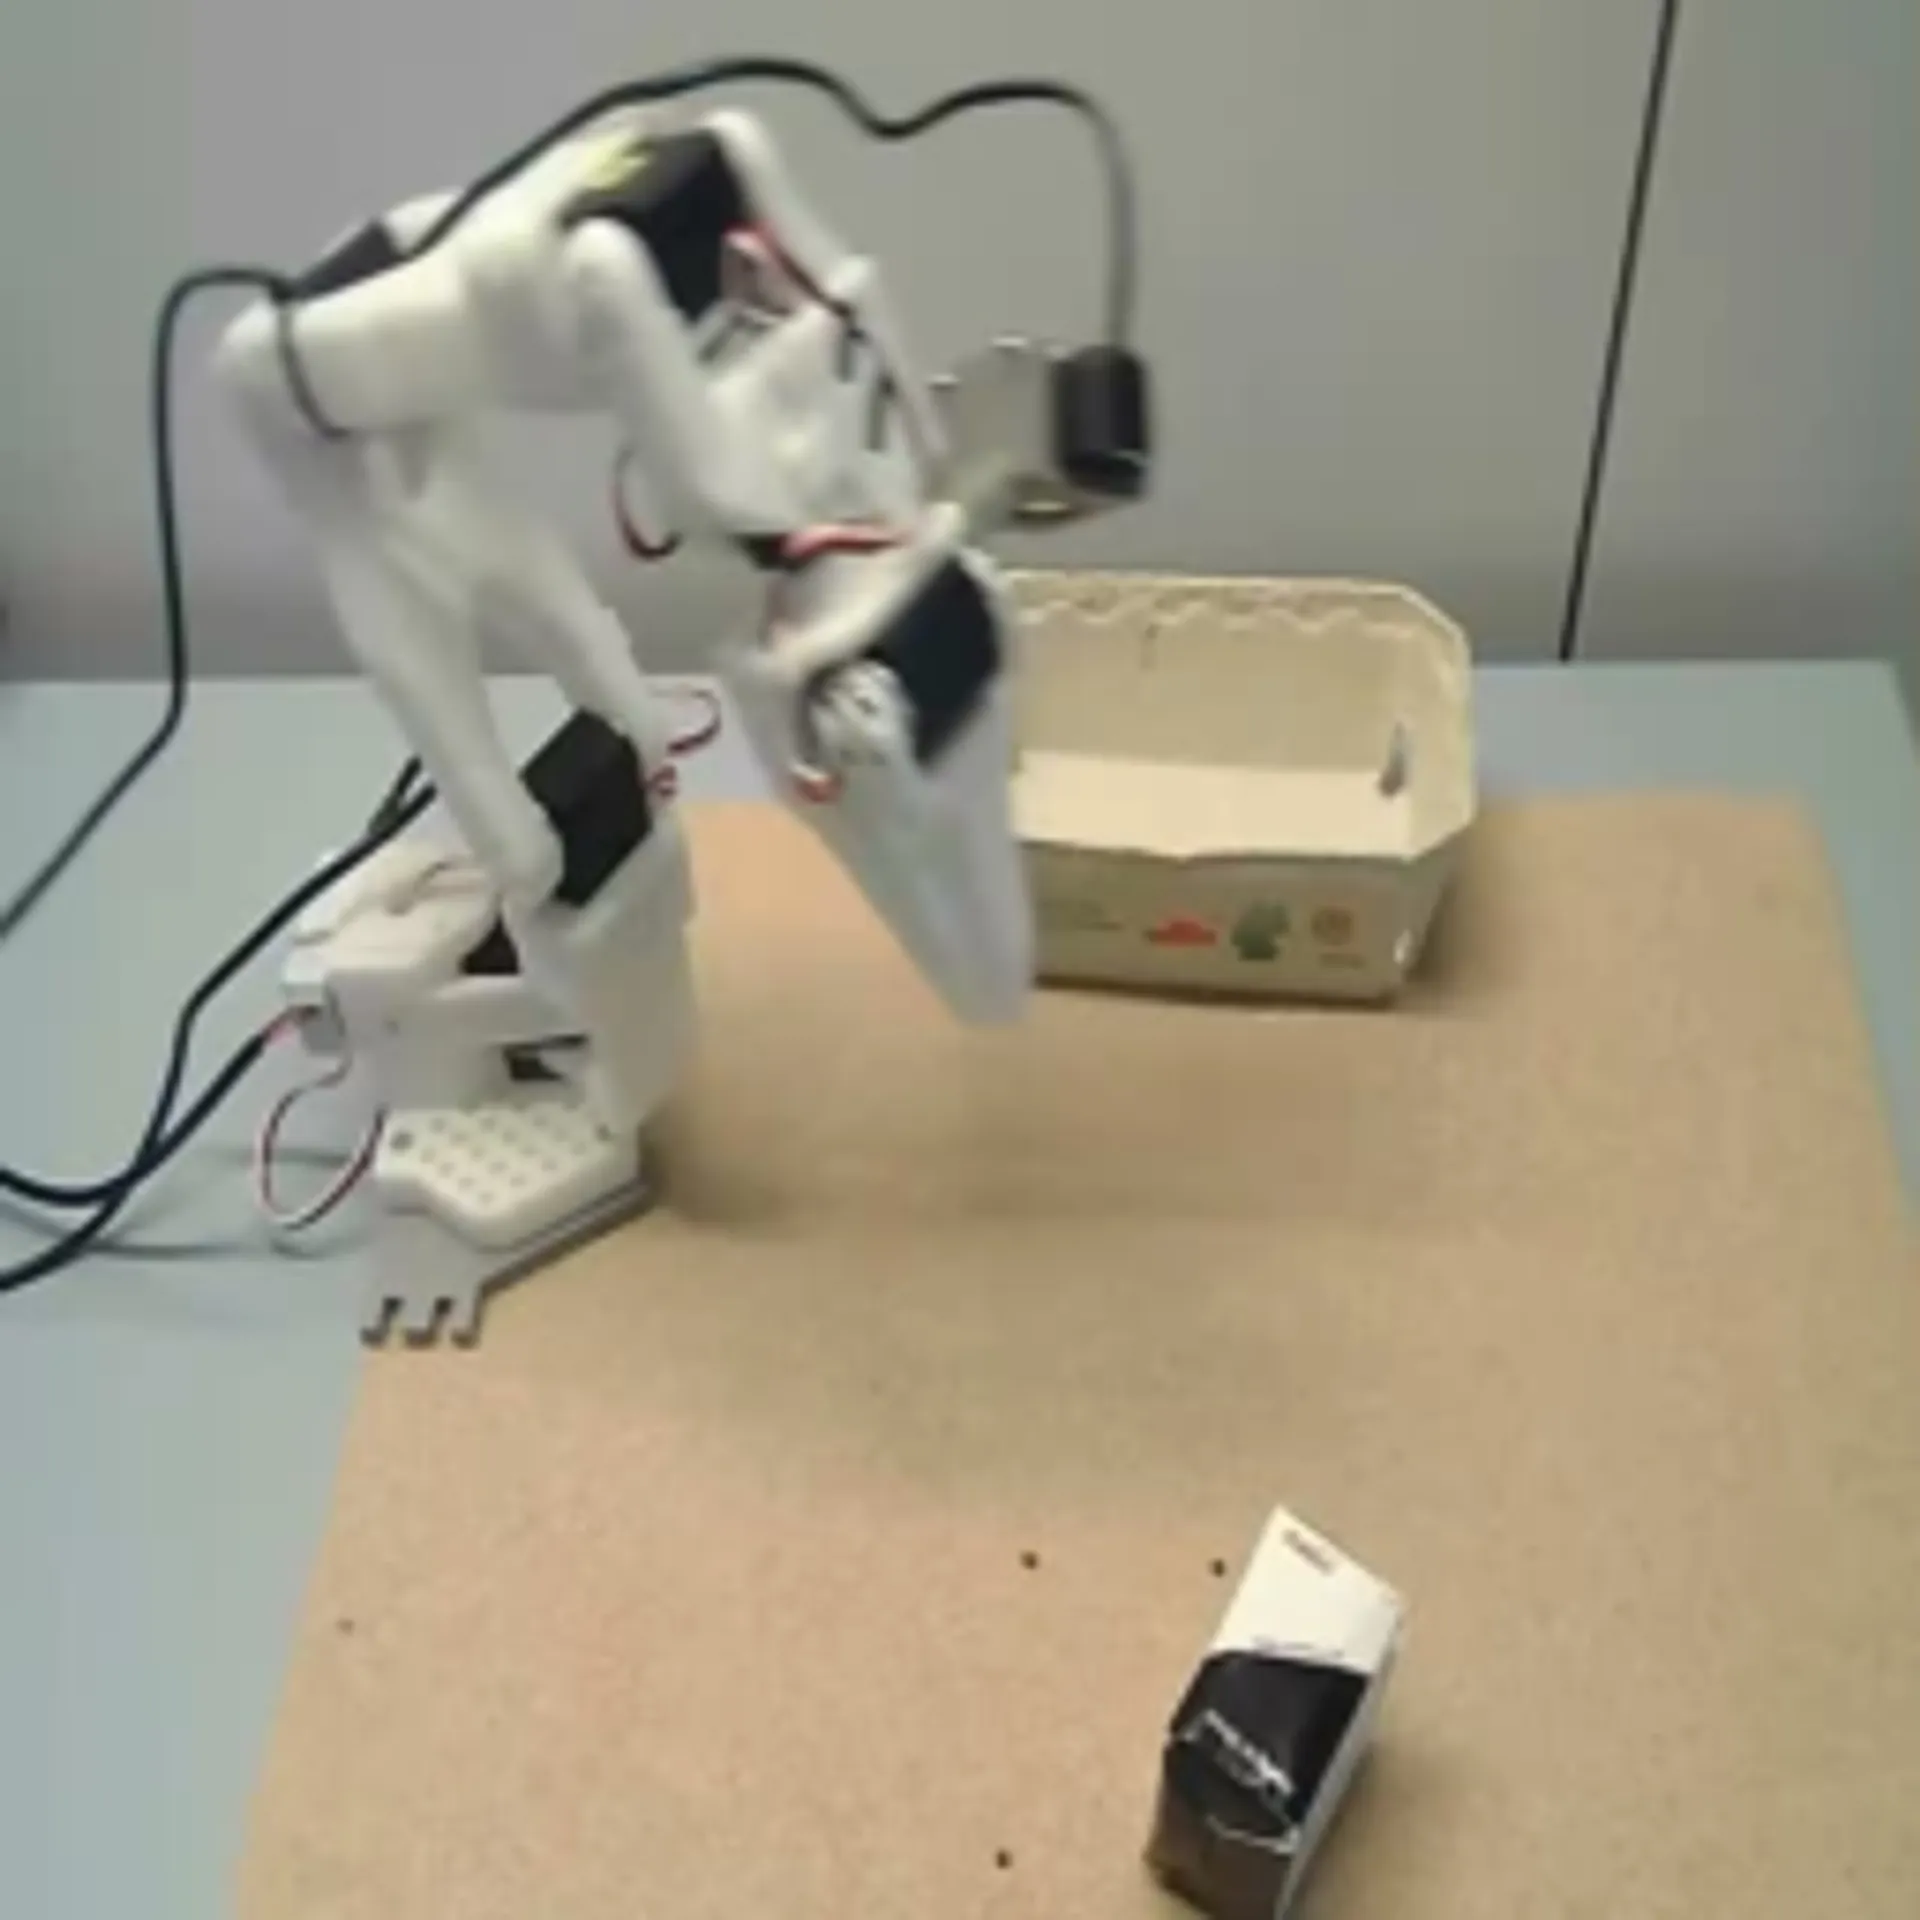
Hint: Drag and drop image files from your computer, images from web pages, paste from clipboard (Ctrl/Cmd+V), or provide a URL. Accepted file types: jpg, jpeg, png, webp, gif, avif, heic, heif
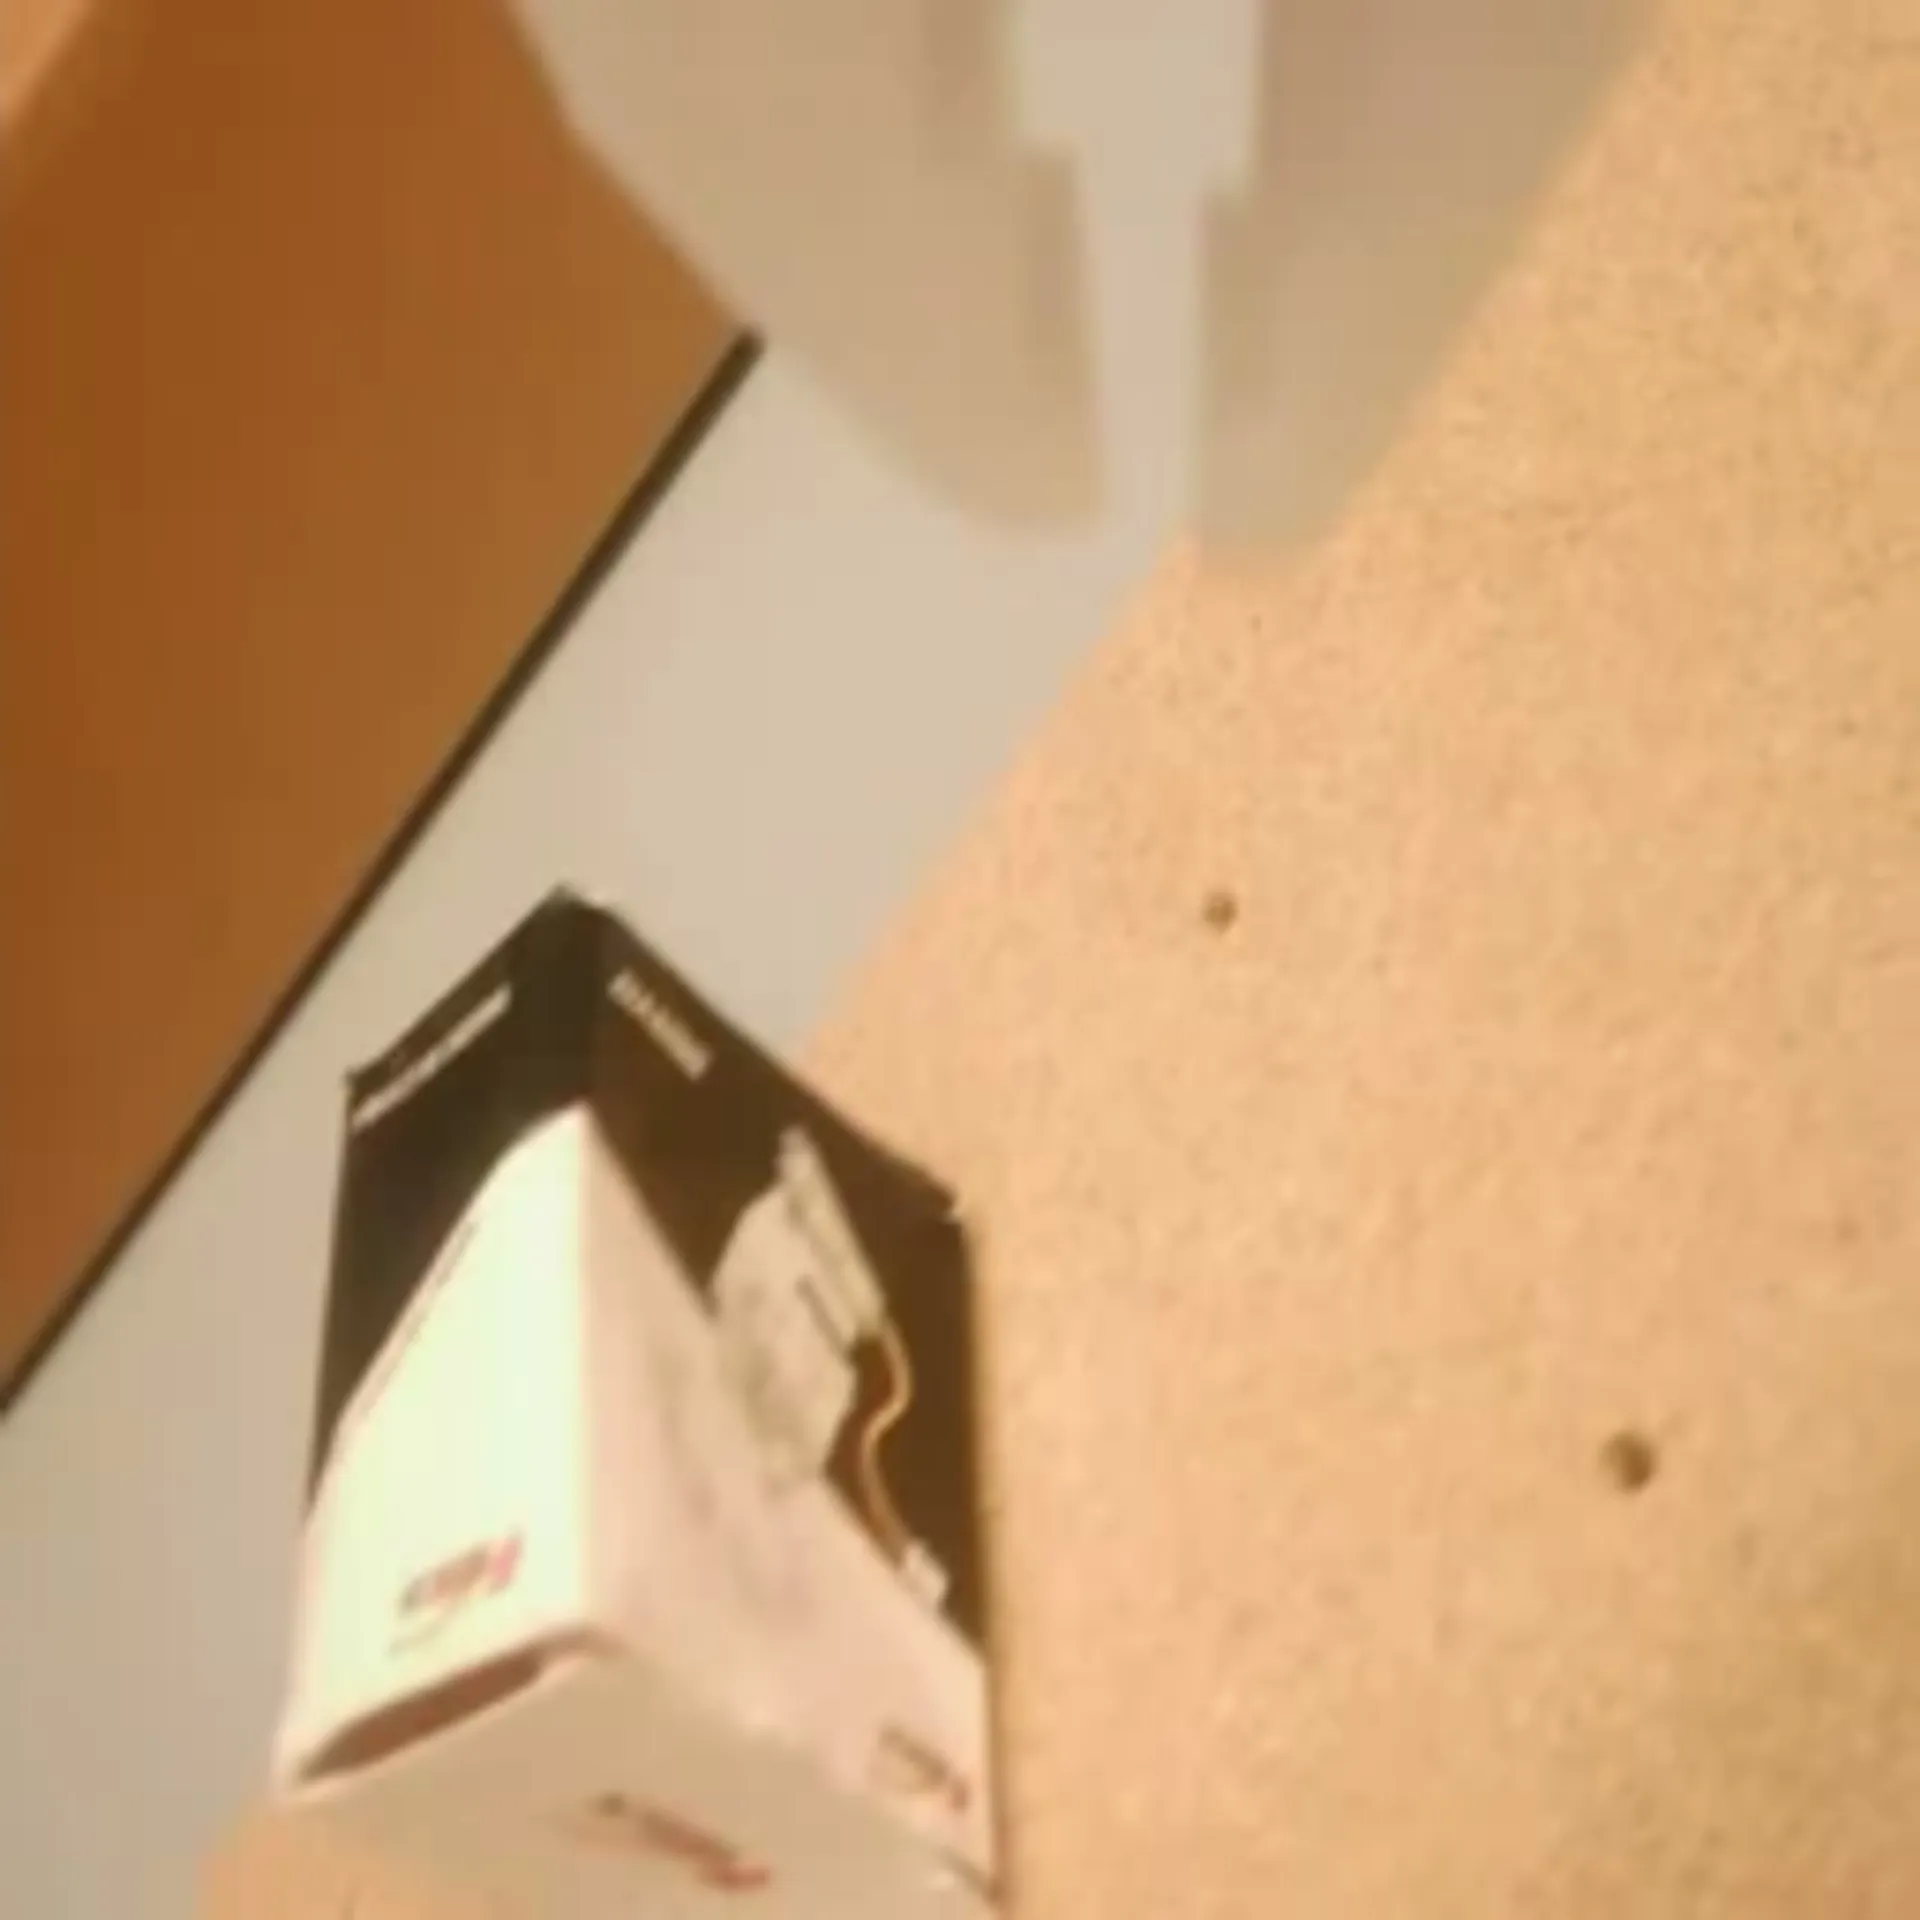
Additional Settings
Customize your input with more control.
Result
Idle
What would you like to do next?
Pricing can change for this endpoint. Your request will cost $0.003 per compute second. A typical call (one 42-step action chunk) is billed about 0.5 to 2 s of compute, so roughly $0.0015 to $0.006 per call, or about 1 s of robot motion.