Showing 985 to 1008 of 1684 results
hunyuan-video-v1.5/text-to-video
Hunyuan Video 1.5 is Tencent's latest and best video model
hunyuan-video
text-to-video


Generate images from text and edge, depth or pose images using custom LoRA and Z-Image Turbo, Tongyi-MAI's super-fast 6B model.
turbo
z-image
fast
image-to-image
vidu/q2/image-to-video/pro
Use the latest Vidu Q2 models which much more better quality and control on your videos.
image-to-video

Generate fast speech from text prompts and different voices using the MiniMax Speech-02 Turbo model, which leverages advanced AI techniques to create high-quality text-to-speech.
text-to-speech
new
kandinsky6-lite/image-to-video
Kandinsky 6.0 Lite animates a single image into a short video clip, with fast, lightweight inference and prompt-guided motion.
kandinsky
lightweight
image-to-video
new
meshy/v6-lite/retexture
Meshy 6 Lite retexture applies new textures to an existing 3D model from a text prompt or a reference image, with optional PBR maps.
3d
textures
pbr
3d-to-3d
stable-diffusion-v3-medium/image-to-image
Stable Diffusion 3 Medium (Image to Image) is a Multimodal Diffusion Transformer (MMDiT) model that improves image quality, typography, prompt understanding, and efficiency.
diffusion
editing
style
image-to-image
Generate video clips from your images using MiniMax Video model
motion
transformation
image-to-video


Accelerated image generation with Ideogram V2A Turbo. Create high-quality visuals, posters, and logos with enhanced speed while maintaining Ideogram's signature quality.
realism
typography
text-to-image
glm-image
Create high-quality images with accurate text rendering and rich knowledge details—supports editing, style transfer, and maintaining consistent characters across multiple images.
text-to-image


Generate images from your prompts using Luma Photon Flash. Photon Flash is the most creative, personalizable, and intelligent visual models for creatives, bringing a step-function change in the cost of high-quality image generation.
text-to-image


FLUX.1 SRPO [dev] is a 12 billion parameter flow transformer that generates high-quality images from text with incredible aesthetics. It is suitable for personal and commercial use.
text-to-image
Text-to-image generation with FLUX.2 [klein] 4B from Black Forest Labs and custom LoRA. Enhanced realism, crisper text generation, and native editing capabilities.
text-to-image
Remove unwanted elements (objects, people, text) while maintaining image consistency
stylized
transform
image-to-image
Precise camera position and angle control (rotation, zoom, vertical movement)
stylized
transform
image-to-image
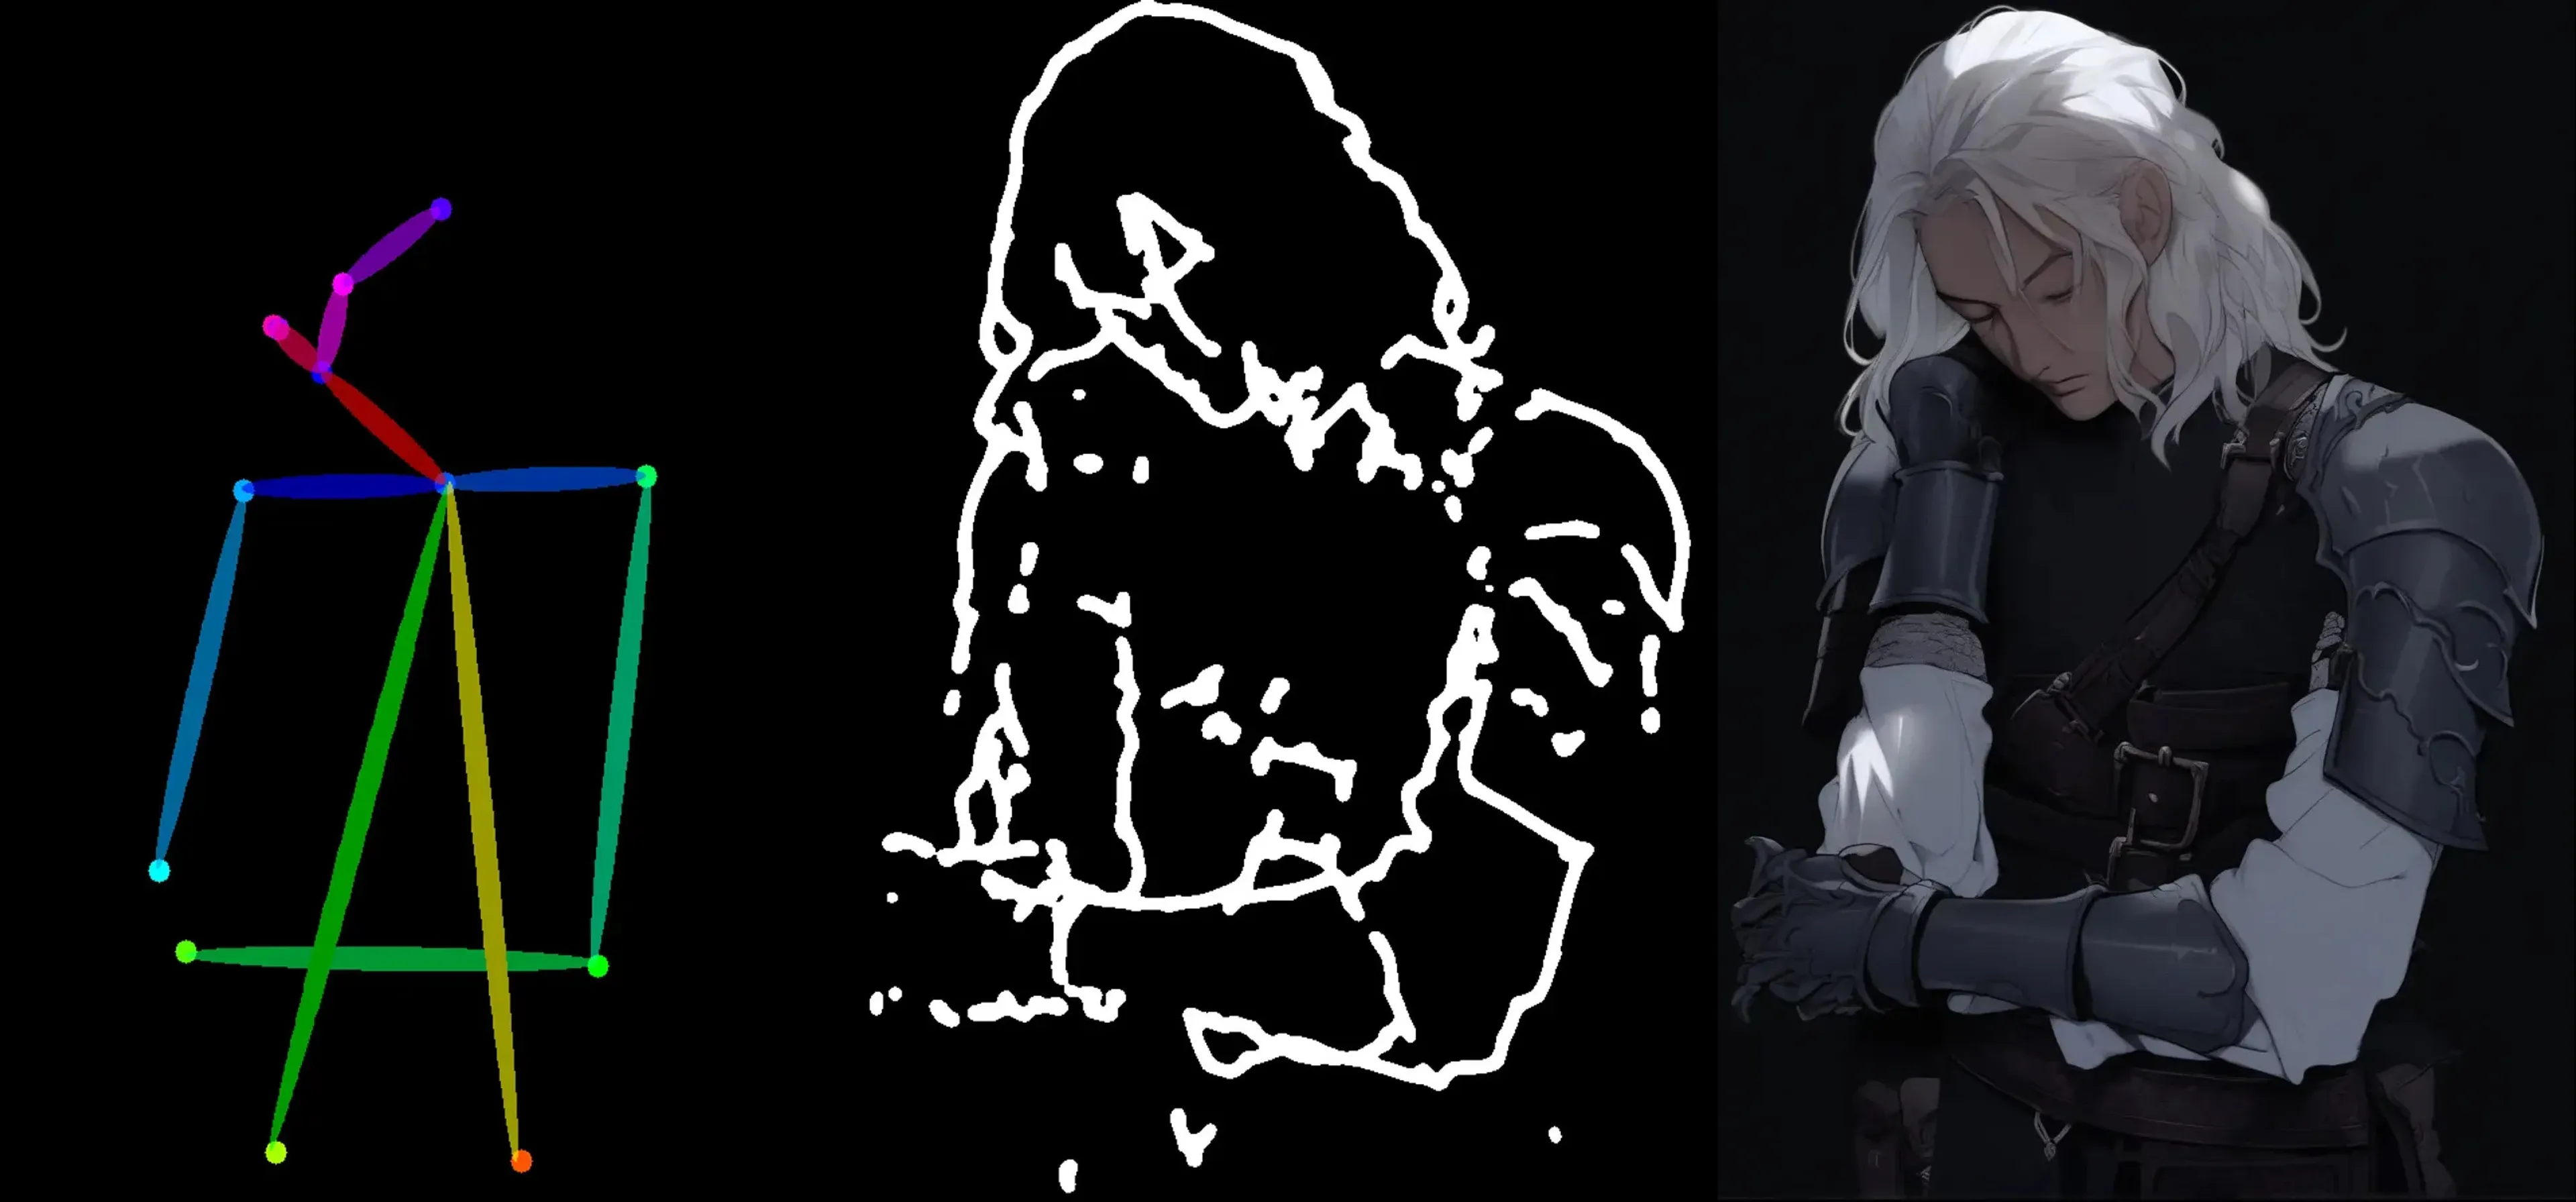
sdxl-controlnet-union/image-to-image
An efficent SDXL multi-controlnet image-to-image model.
diffusion
controlnet
composition
image-to-image
vidu/template-to-video
Vidu Template to Video lets you create different effects by applying motion templates to your images.
motion
template
image-to-video
recraft/v4/create-style
Creates a reusable style from your reference images and returns a style ID you can pass to Recraft V4 Styles image and vector generation.
transform
utility
stylized
training
image-editing/expression-change
Change facial expressions in photos to any emotion you desire, from smiles to serious looks.
stylized
transform
image-to-image
new
nvidia/nemotron-3-5-super/vision
Ask NVIDIA Nemotron 3.5 Super questions about an image: describe scenes, read text and charts, and reason over what it sees.
vision
multimodal
reasoning
image-to-text
firered-image-edit
FireRed Image Edit is FireRed's state of the art open source editing model, re-trained from Qwen Image Edit 2509.
image-editing
firered
image-to-image
image-apps-v2/portrait-enhance
Enhance and refine portrait photos with improved clarity and detail.
image-edit
enhancement
image-to-image
rundiffusion-fal/juggernaut-flux-lora
Juggernaut Base Flux LoRA by RunDiffusion is a drop-in replacement for Flux [Dev] that delivers sharper details, richer colors, and enhanced realism to all your LoRAs and LyCORIS with full compatibility.
image generation
text-to-image
sdxl-controlnet-union
An efficent SDXL multi-controlnet text-to-image model.
diffusion
controlnet
composition
text-to-image
Showing 985 to 1008 of 1684 results