Showing 601 to 624 of 1684 results


Happy Horse 1.1 is Alibaba's #1-ranked video model. This text-to-video endpoint generates 1080p video with synchronized native audio and multilingual lip-sync from a text prompt alone.
happy-horse
video
text
text-to-video


Bria Extract Object uses text prompts to isolate a selected object from an image and return it as an RGBA PNG with a transparent background. Ideal for product, ecommerce, advertising, and creative editing workflows. Bria's Extract Object API leads in product shot extraction, outperforming SAM 3.1 where it counts most for commercial use.
image-to-image
new
marigold-v2
Estimate depth from a single image with Marigold V2, a diffusion-based depth model built on Qwen-Image-Edit, returning a colorized depth map.
depth
utility
image-to-image

LTX-2.3 is a high-quality, fast AI video model available in Pro and Fast variants for text-to-video, image-to-video, and audio-to-video.
stylized
transform
lipsync
audio-to-video
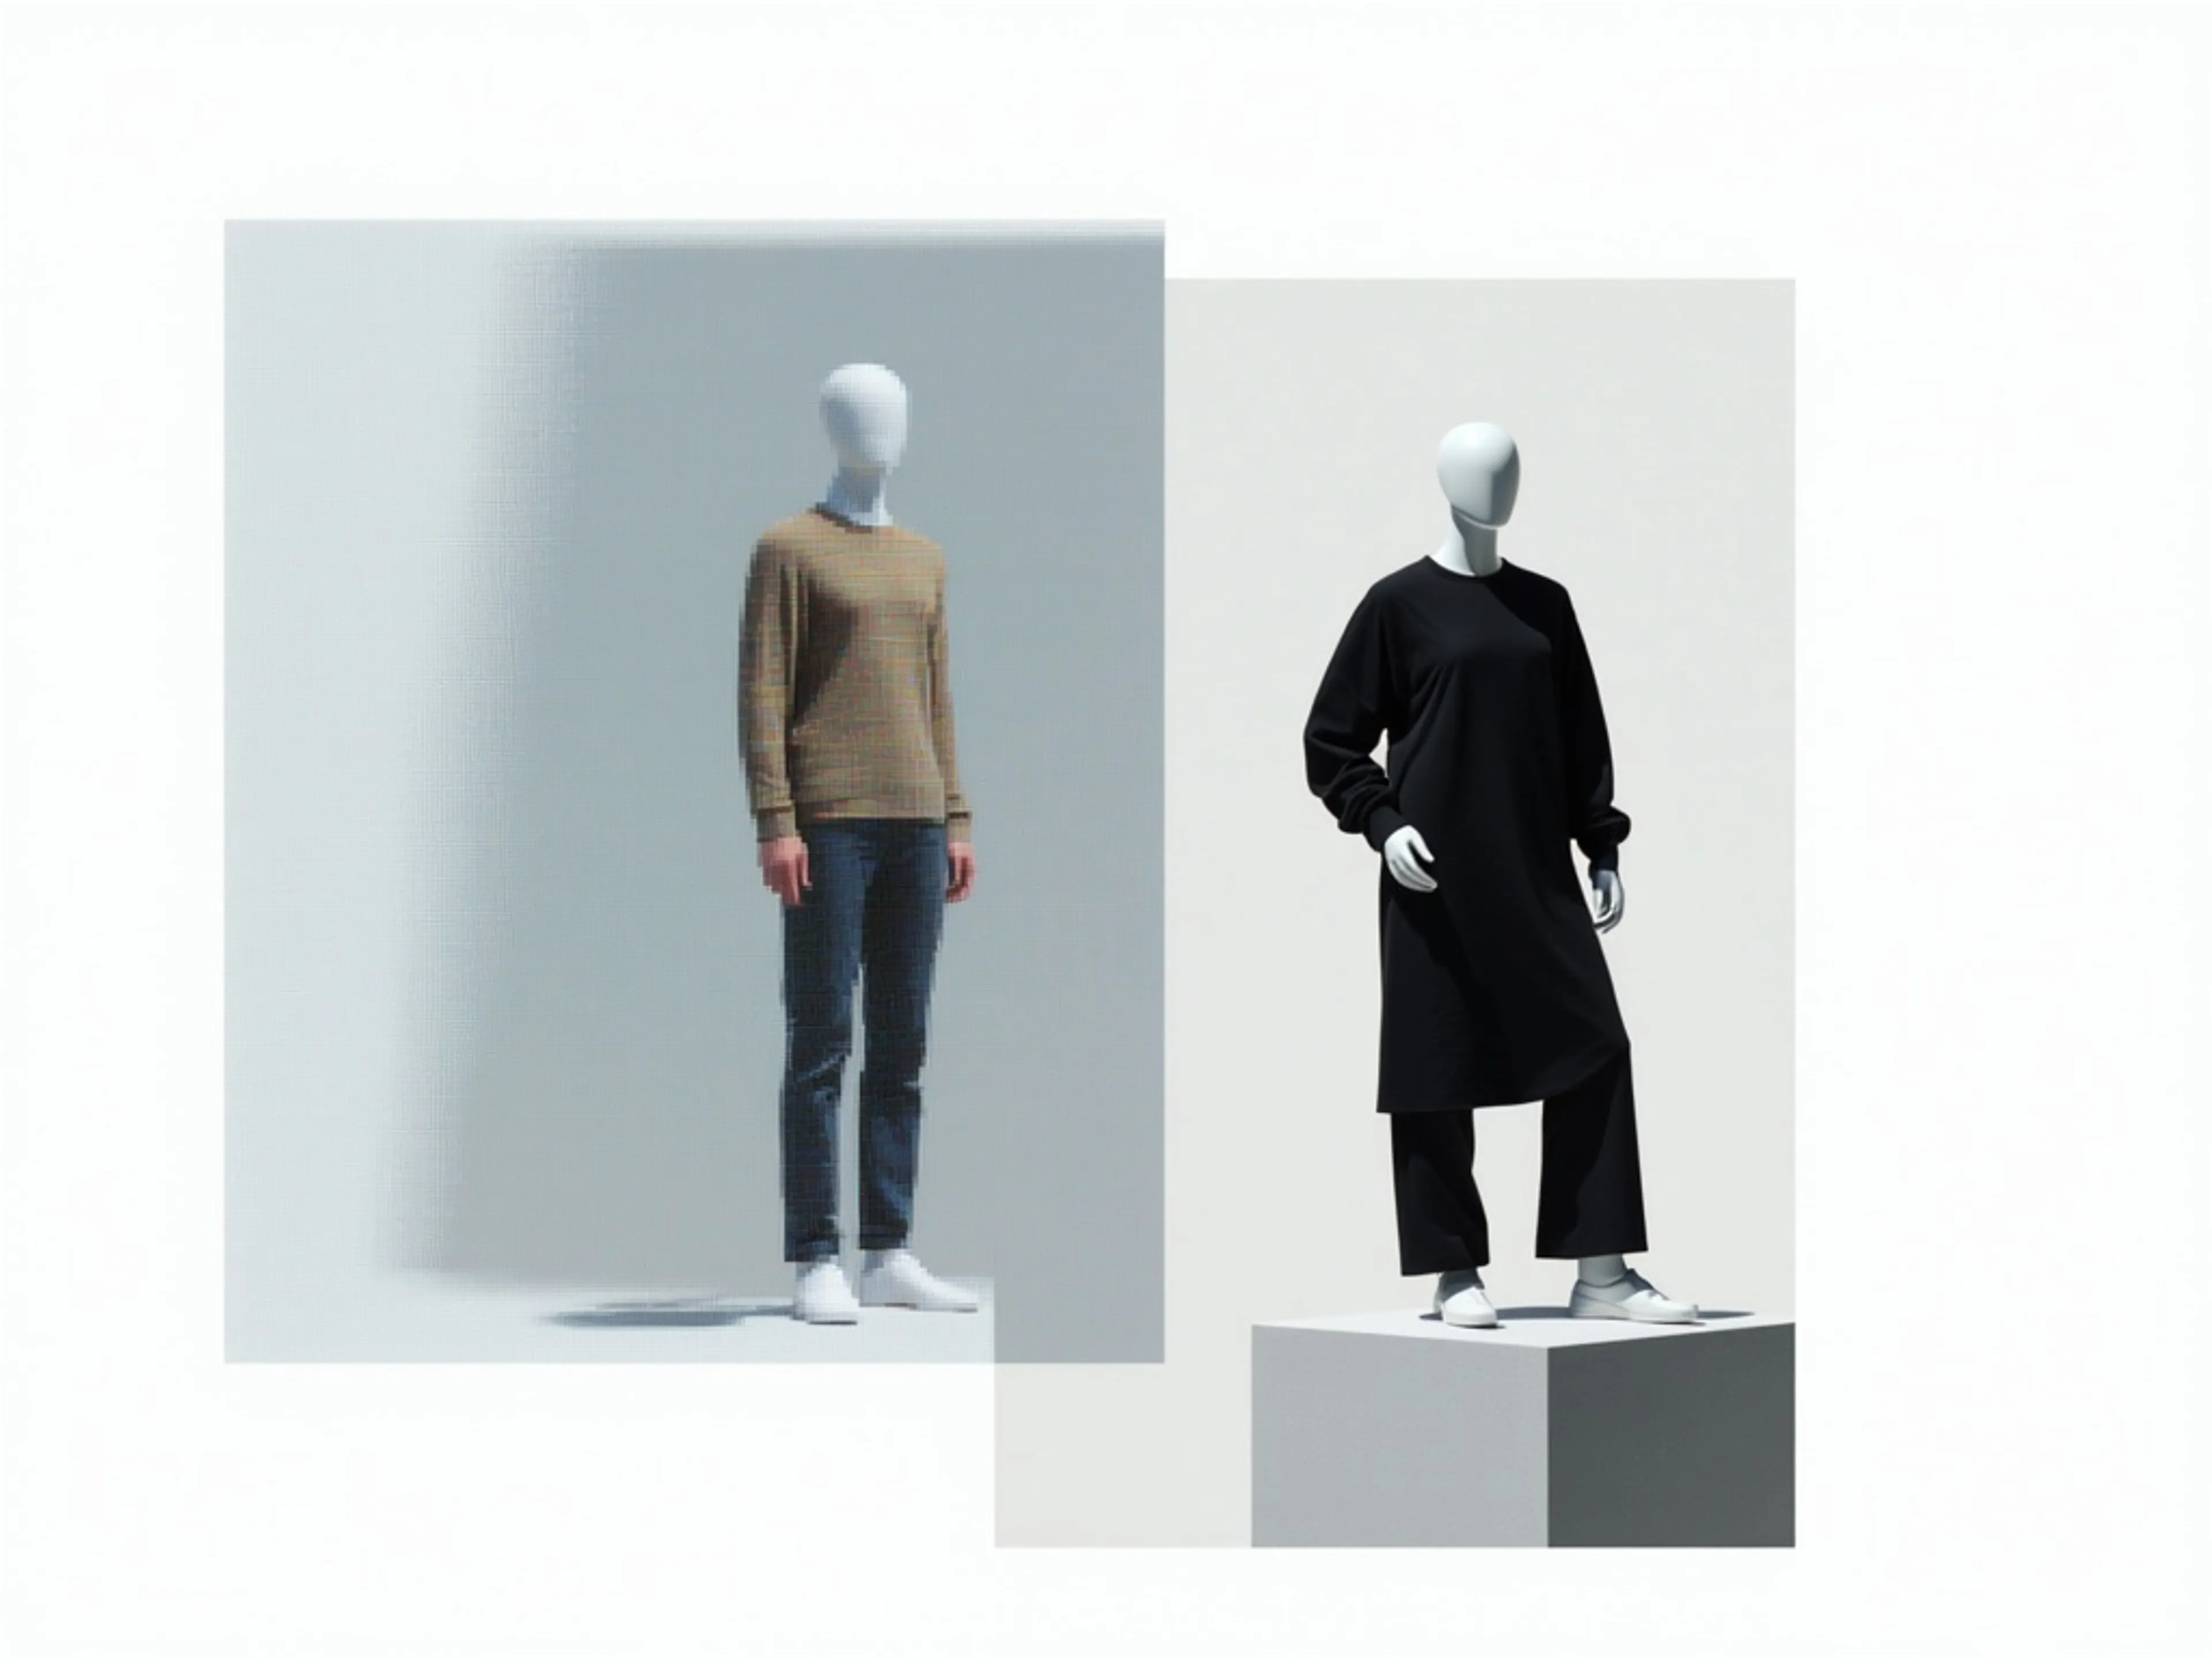
hy-wu-edit
Image editing with HY-WU. Transfer outfits, swap faces, and blend textures instantly—no finetuning needed, just describe what you want and provide reference images.
image-to-image
LTX-2.5 is Lightricks' open-source audio-video model. This endpoint generates video timed to a supplied audio clip in a quality-optimized mode, for final visuals synchronized to music, dialogue, or a soundtrack.
stylized
transform
lip-sync
audio-to-video
kokoro/british-english
A high-quality British English text-to-speech model offering natural and expressive voice synthesis.
speech
text-to-audio


Kling's Native 4K is a video generation model that directly outputs professional-grade 4K video in one step, eliminating the need for post-production upscaling
utility
editing
video-to-video


Generate images with transparent backgrounds using Ideogram Transparent model
stylized
transform
typography
text-to-image
Generate natural multilingual speech from text with fast voice and language control using Qwen Audio 3.0 TTS Flash.
audio
speech-synthesis
multilingual
text-to-speech


FLUX Control LoRA Depth is a high-performance endpoint that uses a control image to transfer structure to the generated image, using a depth map.
lora
style transfer
text-to-image
Precise camera position and angle control (rotation, zoom, vertical movement)
stylized
transform
image-to-image
live-portrait
Transfer expression from a video to a portrait.
expression
animation
image-to-video
instant-character
InstantCharacter creates high-quality, consistent characters from text prompts, supporting diverse poses, styles, and appearances with strong identity control.
personalization
customization
image-to-image
creative-upscaler
Create creative upscaled images.
upscaling
image-to-image
Kling O1 Omni generates new shots guided by an input reference video, preserving cinematic language such as motion, and camera style to produce seamless scene continuity.
video-to-video
meshy/v7/multi-image-to-3d
econstructs a high-fidelity textured 3D model from multiple angle views of one object, with game-ready topology and polygon control
stylized
transform
image-to-3d

Restyle videos up to 30 min long - maintaining maximum detail quality.
video-edit
video-to-video
Wan 2.2's 5B model produces up to 5 seconds of video 720p at 24FPS with fluid motion and powerful prompt understanding
text-to-video
Fast inpainting endpoint for the FLUX.1 Kontext [dev] model with LoRA support, enabling rapid and high-quality image inpainting with reference images, while using pre-trained LoRA adaptations for specific styles, brand identities, and product-specific outputs.
image-editing
image-inpainting
image-to-image
Generate 1080p video with synchronized native audio from a text prompt. Aspect ratios: 16:9, 9:16, 1:1, 4:3, 3:4. Duration: 3–15s.
happy-horse
text-to-video
microsoft/mai-image-2.5-pro
Generate high-fidelity, design-ready images with precise typography, strong prompt alignment, and rich visual detail using Microsoft's flagship MAI Image 2.5 Pro.
photorealism
typography
illustration
text-to-image
Generate videos from images using LTX Video 0.9.1
image-to-video


Luma Uni-1 Max generates a single image at the model's highest fidelity, delivering richer detail and stronger prompt adherence than the base tier for hero-quality stills.
realism
typography
stylized
text-to-image
Showing 601 to 624 of 1684 results