Showing 217 to 240 of 1684 results


Image editing endpoint for the fast Lite version of Seedream 5.0, supporting high quality intelligent image editing with multiple inputs.
bytedance
seedream-5.0-lite
edit
image-to-image
stable-audio-3/medium/text-to-audio
Stable Audio 3 Medium is a 1.4 billion parameter latent diffusion model that generates high-quality stereo music up to 6 minutes from text prompts, trained on fully licensed data for safe commercial use.
music
audio
stereo
text-to-audio
Seedance 2.0 Mini is a faster version of Seedance 2.0 that brings great performance and high generation speed at a lower cost.
stylized
transform
lipsync
image-to-video
openrouter/router/audio
Run any audio capable LLM with fal. Process audio files — transcription, analysis, understanding — using Gemini (Google) models. Supports wav, mp3, aiff, aac, ogg, flac, m4a. Powered by OpenRouter.
unknown


Animates a still image into video with audio. Extends a single frame into coherent motion, grounded in Gemini's physical understanding of how scenes and subjects behave.
stylized
transform
lipsync
image-to-video
sam-3-1/image
SAM 3.1 builds comes with Object Multiplex, a shared-memory approach for joint multi-object tracking that delivers faster speeds with larger number of objects tracked.
segmentation
mask
real-time
image-to-image
Seedream 5.0 Flash is a fast image generation and editing model, built for workflows where speed and budget matter.
realism
typography
stylized
text-to-image


fal-ai/wan/v2.2-A14B/image-to-video
image-to-video


Outpainting generation with FLUX.2 [pro] from Black Forest Labs. Optimized for maximum quality, exceptional photorealism and artistic images.
outpaint
outpainting
image-to-image
Experimental version of FLUX.1 Kontext [max] with multi image handling capabilities
image-to-image
ByteDance's most advanced text-to-video model, fast tier. Lower latency and cost with cinematic output, native audio, multi-shot editing, and director-level camera control.
stylized
transform
lipsync
text-to-video

Professional generative video upscaling powered by Topaz Labs. Starlight models rebuild detail that is not in the source, with Fast variants at half the price. Best for low-quality, compressed or archive footage.
upscale
video
video-to-video


Generate high quality 1080p videos from images using Kling's Turbo 3.0 model, with improved lipsync and multishot generation capabilities.
kling
v3
turbo
image-to-video
Gemini 3.1 Flash Image (a.k.a. Nano Banana 2) is Google's new state-of-the-art fast image generation and editing model
image-to-image
ace-step
Generate music with lyrics from text using ACE-Step
text-to-music
text-to-audio


Isolate audio tracks using ElevenLabs advanced audio isolation technology.
audio
audio-to-audio


Generate high-fidelity images from text in seconds with Krea 2 Turbo, the speed-optimized open-source version of Krea 2, preserving its aesthetic range for rapid ideation.
stylized
transform
typography
text-to-image
clarityai/crystal-upscaler
An advanced image enhancement tool designed specifically for facial details and portrait photography, utilizing Clarity AI's upscaling technology.
image-to-image
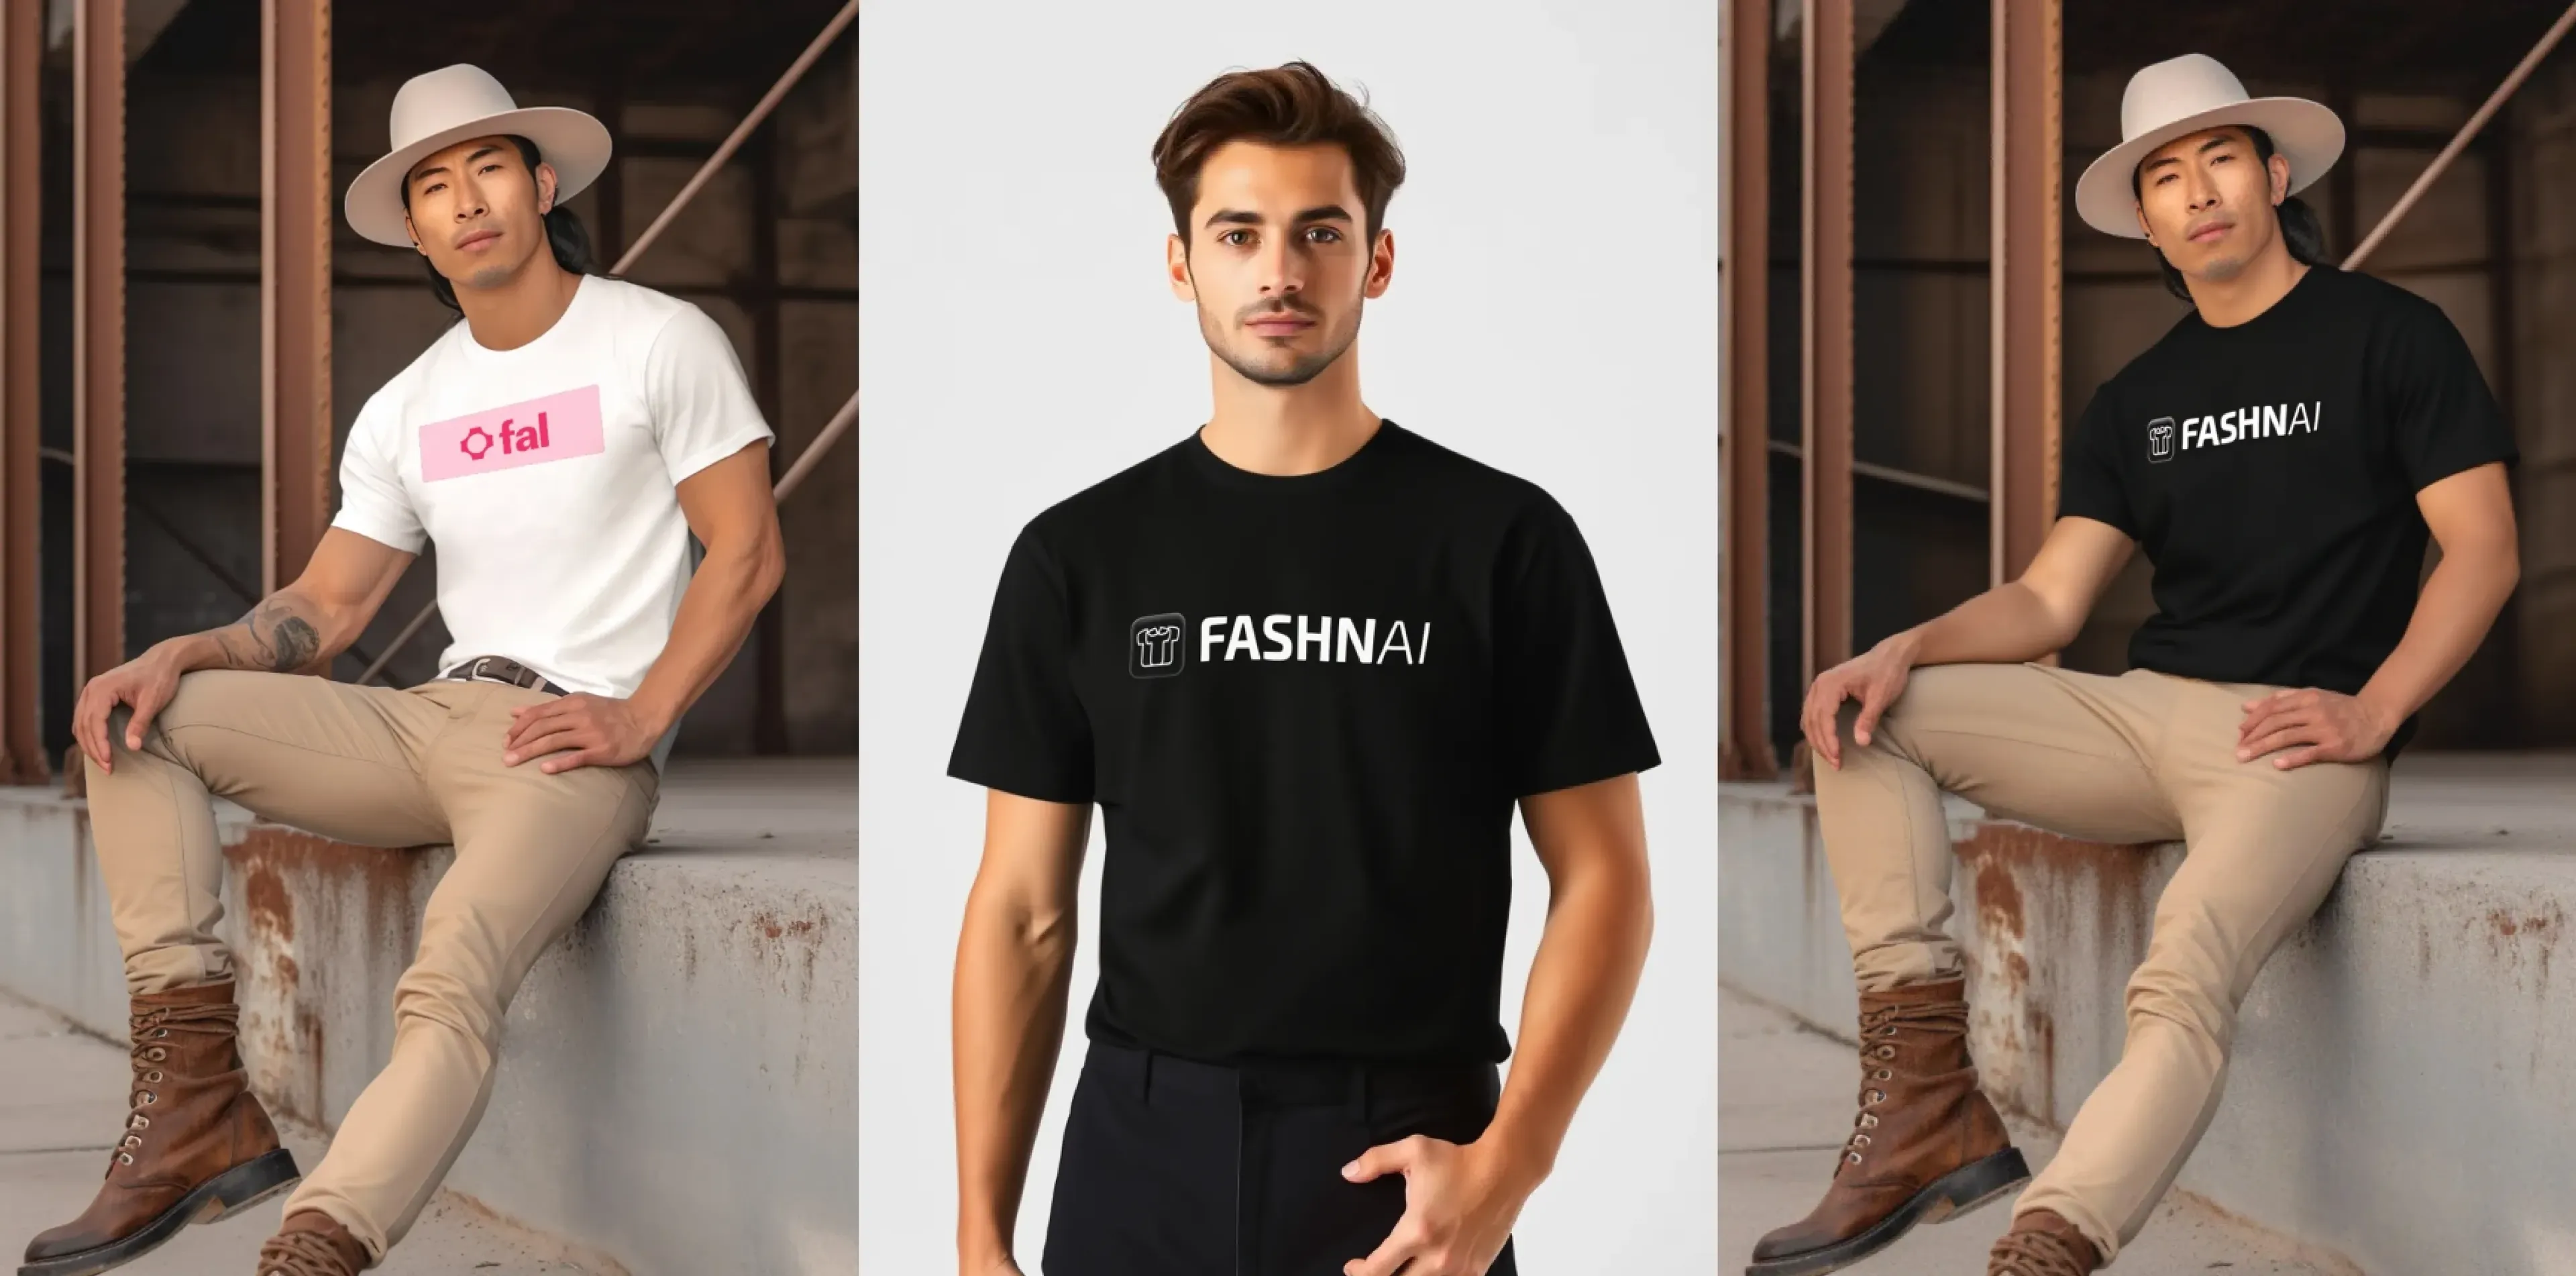
fashn/tryon/v1.6
FASHN v1.6 delivers precise virtual try-on capabilities, accurately rendering garment details like text and patterns at 864x1296 resolution from both on-model and flat-lay photo references.
try-on
fashion
clothing
image-to-image
birefnet/v2/video
Video background removal version of bilateral reference framework (BiRefNet) for high-resolution dichotomous image segmentation (DIS)
utility
editing
video-to-video
audio-understanding
A audio understanding model to analyze audio content and answer questions about what's happening in the audio based on user prompts.
utility
audio
audio-to-audio
Splits a finished image into independent, editable transparent-PNG layers — background plus separate elements, from a text description, returning 2 to 17 layers per call for non-destructive reuse in design tools.
utility
editing
image-to-image
Generates images from a text prompt at resolutions up to 2048×2048, with automatic prompt rewriting and prompt-guided resolution selection, building on Qwen's strength in complex text rendering and precise prompt adherence
stylized
transform
typography
text-to-image


Generate videos with audio from text using Grok Imagine Video.
xai
grok
t2v
text-to-video
Showing 217 to 240 of 1684 results