


Precise, controllable photo re-lighting with structured text inputs. Apply natural lighting styles, soften harsh shadows, and transform scene illumination - production-ready and trained exclusively on licensed data.
bria
fibo-edit
relighting
image-to-image
vidu/q3/text-to-video/turbo
Vidu's Q3 Turbo Model.
text-to-video


FLUX.1 SRPO [dev] is a 12 billion parameter flow transformer that generates high-quality images from text with incredible aesthetics. It is suitable for personal and commercial use.
text-to-image
stable-diffusion-v35-medium
Stable Diffusion 3.5 Medium is a Multimodal Diffusion Transformer (MMDiT) text-to-image model that features improved performance in image quality, typography, complex prompt understanding, and resource-efficiency.
diffusion
typography
style
text-to-image
kokoro/french
An expressive and natural French text-to-speech model for both European and Canadian French.
speech
text-to-audio

FLUX.1 SRPO [dev] is a 12 billion parameter flow transformer that generates high-quality images from text with incredible aesthetics. It is suitable for personal and commercial use.
image-to-image
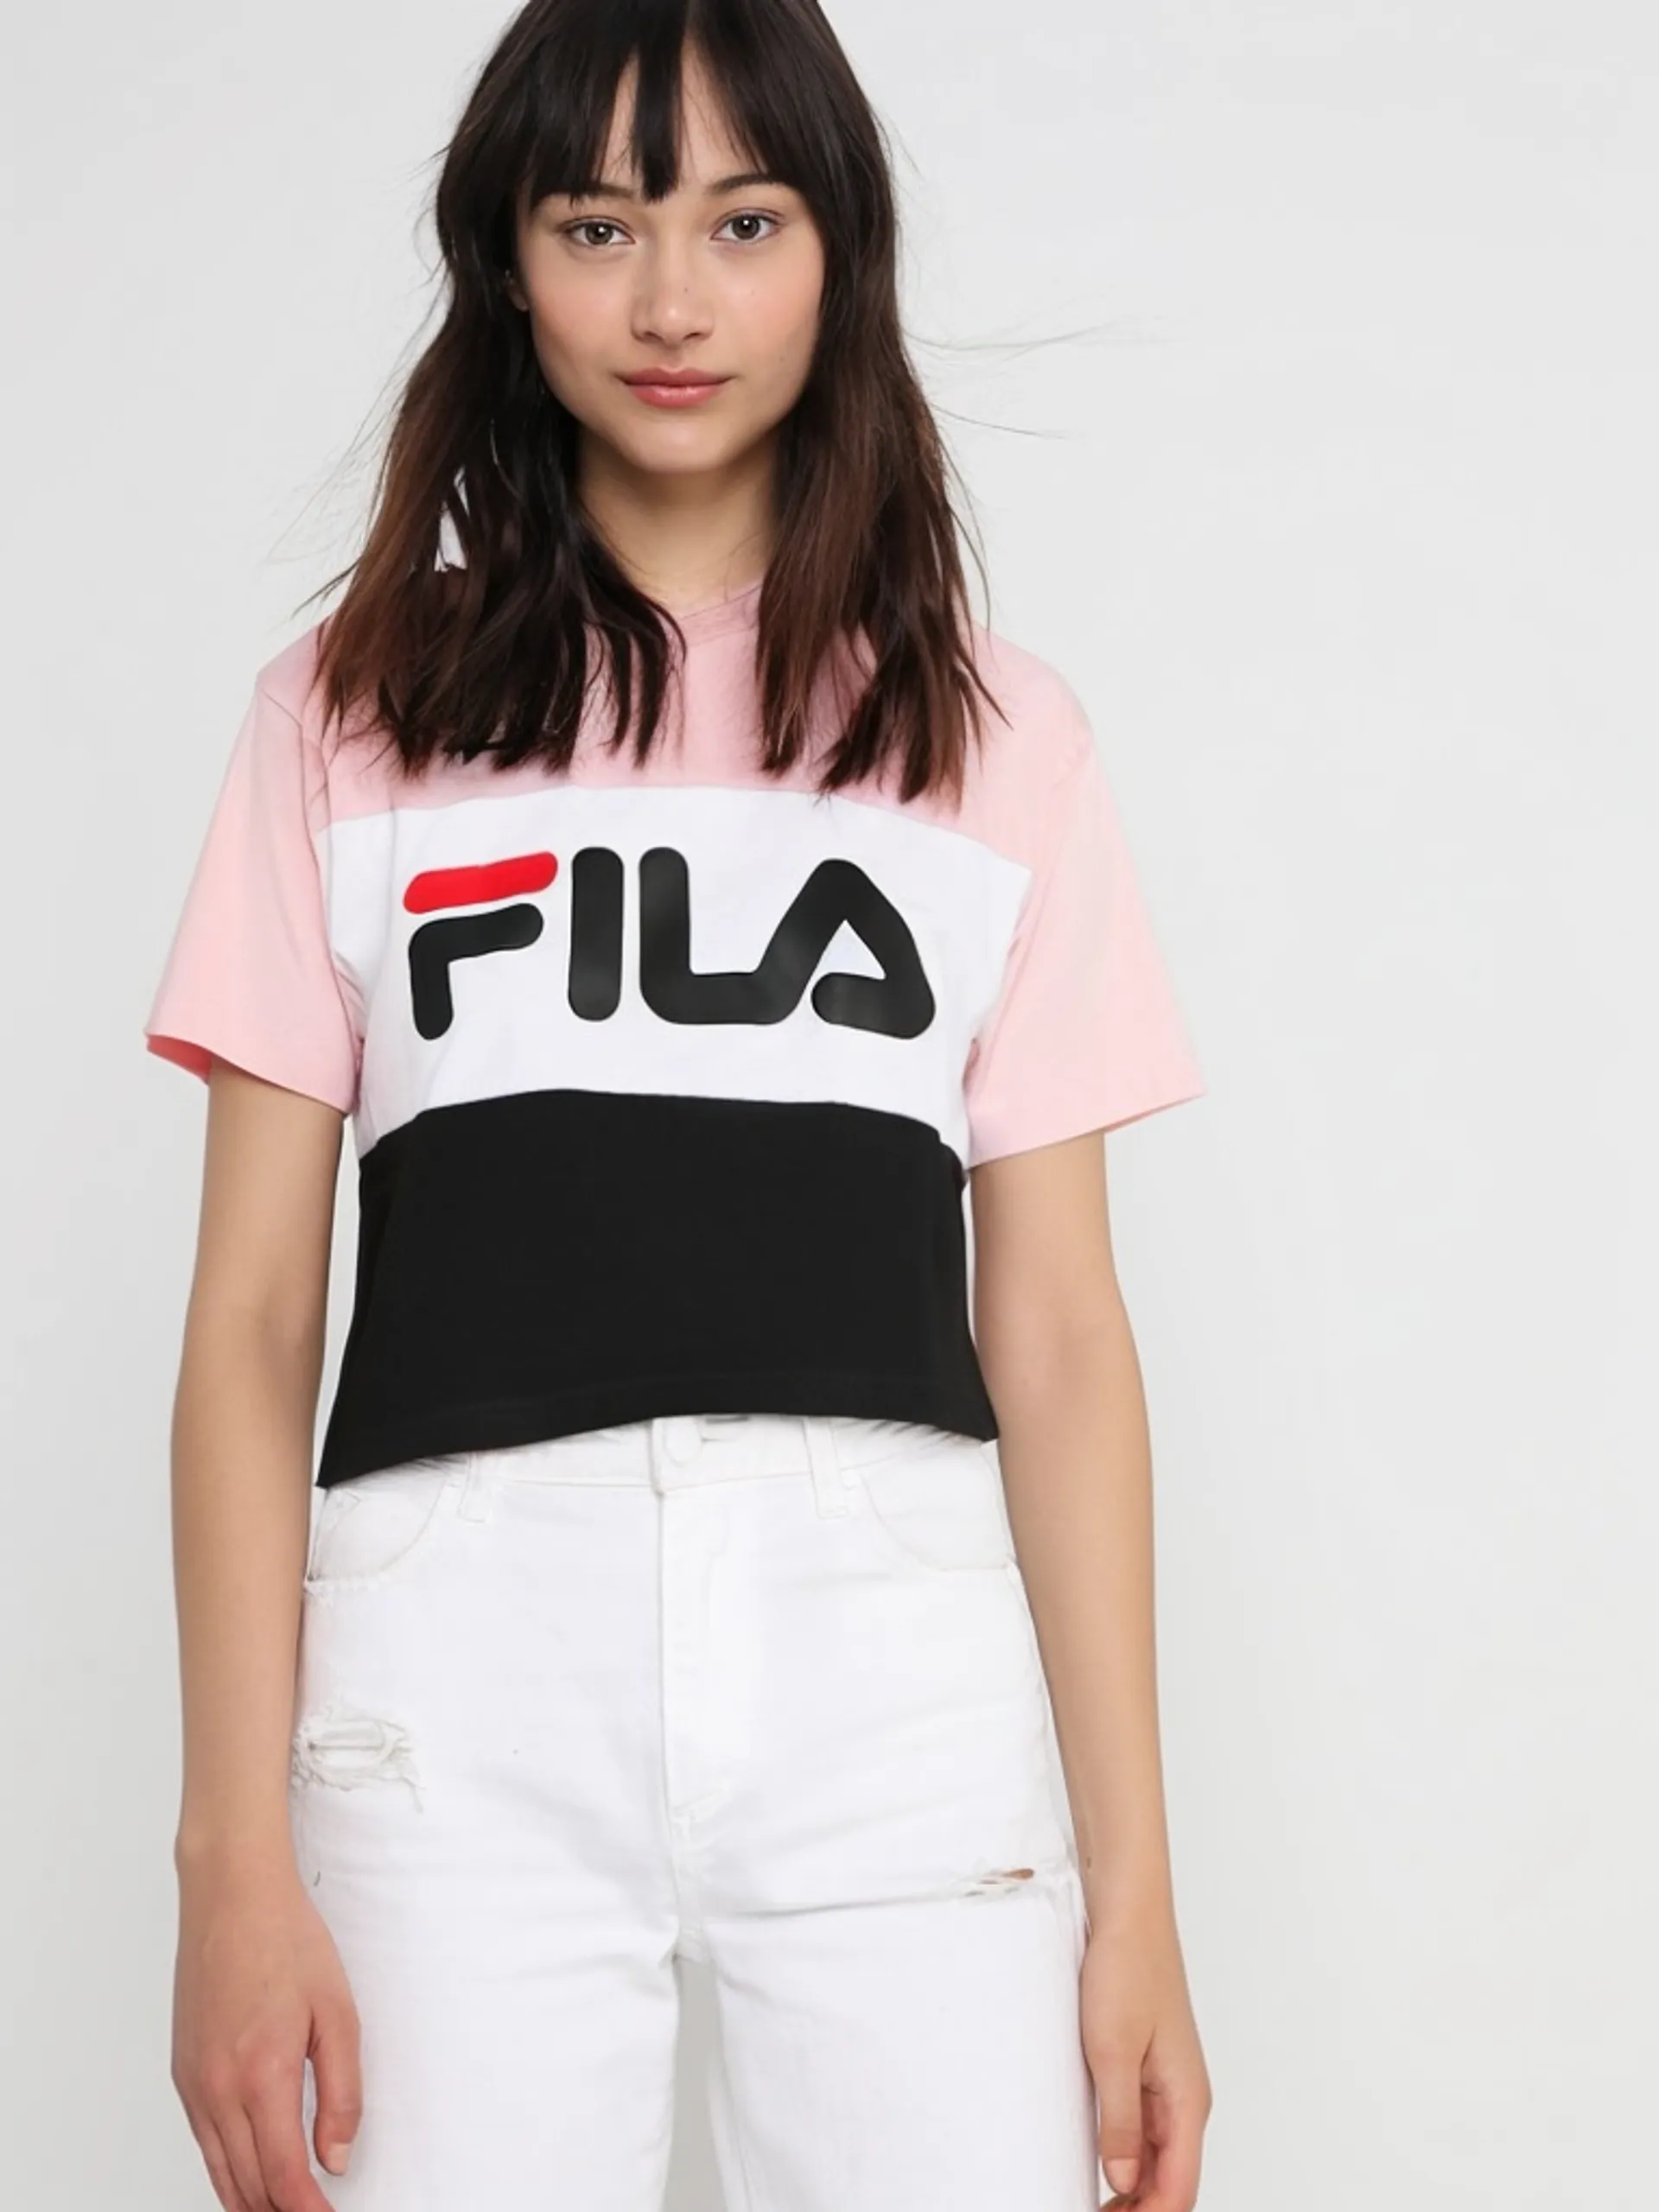
leffa/virtual-tryon
Leffa Virtual TryOn is a high quality image based Try-On endpoint which can be used for commercial try on.
try-on
fashion
clothing
image-to-image
image-editing/retouch
Retouch photos of faces. Remove blemishes and improve the skin.
image-to-image

LTX-2.5 is Lightricks' open-source audio-video model. This endpoint generates video timed to a supplied audio clip in a speed-optimized mode — useful for music-driven content, dialogue-led shorts, and ads keyed to a track.
stylized
transform
lip-sync
audio-to-video


Bring speech to your texts using Qwen3-TTS Custom-Voice model with pre-trained voices or use your custom voice with Qwen3-TTS Clone Voice model
text-to-speech
sana/sprint
Sana Sprint is a text-to-image model capable of generating 4K images with exceptional speed.
text to image
4k
high-speed
text-to-image

Edit outfits, objects, faces, or restyle your video - all with maximum detail retention.
video-edit
video-to-video
vidu/q1/reference-to-video
Generate video clips from your multiple image references using Vidu Q1
stylized
transform
image-to-video

Generate speech from text prompts and different voices using the MiniMax Speech-02 HD model, which leverages advanced AI techniques to create high-quality text-to-speech.
speech
text-to-speech
recraft/v4.1/utility/pro/text-to-image
Recraft V4.1 Utility Pro pairs the high-resolution output of V4.1 Pro with a faster, cost-efficient runtime. Designed for studios shipping large-format work at scale, it makes premium-quality raster generation viable across full creative pipelines.
stylized
transform
typography
text-to-image

LTX-2.3 is a high-quality, fast AI video model available in Pro and Fast variants for text-to-video, image-to-video, and audio-to-video.
stylized
transform
lipsync
video-to-video
ip-adapter-face-id
High quality zero-shot personalization
ip-adapter
personalization
customization
image-to-image
Wan-2.1 Pro is a premium image-to-video model that generates high-quality 1080p videos at 30fps with up to 6 seconds duration, delivering exceptional visual quality and motion diversity from images
image to video
motion
image-to-video
sam2/video
SAM 2 is a model for segmenting images and videos in real-time.
segmentation
mask
real-time
video-to-video
stable-diffusion-v3-medium/image-to-image
Stable Diffusion 3 Medium (Image to Image) is a Multimodal Diffusion Transformer (MMDiT) model that improves image quality, typography, prompt understanding, and efficiency.
diffusion
editing
style
image-to-image
stable-audio-3/small/sfx/base/text-to-audio
Stable Audio 3 Small SFX Base is the foundational 459 million parameter checkpoint generating sound effects from text prompts, intended as the unmodified base for fine-tuning.
sfx
sound-effects
on-device
text-to-audio

Professional SDR-to-HDR conversion powered by Topaz Labs. Hyperion 2.5 redistributes luminance and color while preserving detail in text, faces and motion. Best for giving flat SDR footage a true HDR look.
sdr
video
hdr
video-to-video
nvidia/nemotron-asr-multilingual/asr
Nemotron-ASR-Streaming is a multi lingual, streaming Automatic Speech Recognition (ASR) engineered to deliver high-quality multi lingual transcription across both low-latency streaming and high-throughput batch workloads.
utility
transcribe
speech-to-text

Create seamless transition between images using PixVerse v4.5
stylized
transform
image-to-video
Showing 841 to 864 of 1493 results