Search models...Search by model, task, category and more
Generate high quality video clips from text and image prompts using PixVerse v5
text-to-video

Modify consistent characters while preserving their core identity. Edit poses, expressions, or clothing without losing recognizable character features
character-consistency
image-to-image
nvidia/nemotron-3-nano-omni/vision
Vision reasoning variant of NVIDIA's Nemotron 3 Nano Omni. 30B A3B hybrid Transformer-Mamba MoE - accepts an image plus a prompt and returns text.
nemotron
nvidia
vision-language
image-to-text

microsoft/mai-image-2.5-pro/edit
Apply precise, controllable edits to a reference image while preserving composition, typography, identity, and fine visual detail.
image-editing
typography
photorealism
image-to-image

Generate long videos from prompts and images using LTX Video-0.9.8 13B Distilled and custom LoRA
video
ltx-video
image-to-video
dwpose
Predict poses from images.
pose
utility
image-to-image

Generate video with audio from images using LTX-2.3 Distilled
image-to-video

Generate high-quality images, posters, and logos with Ideogram's latest V4.0q — producing crisp visuals with accurate text rendering, fine detail, and full creative control for polished, ready-to-use designs FRACTION OF A SECOND.
realism
typography
stylized
text-to-image



Generate 1080p video with synchronized native audio from a text prompt. Aspect ratios: 16:9, 9:16, 1:1, 4:3, 3:4. Duration: 3–15s.
happy-horse
text-to-video
recraft/v4/style/text-to-image
Generates raster images that hold a consistent style, from either a saved style ID or reference images attached directly.
realism
typography
stylized
text-to-image
Generate high quality, realistic music with fine controls using Elevenlabs Music v2!
music
text-to-music
text-to-audio

hidream-i1-fast
HiDream-I1 fast is a new open-source image generative foundation model with 17B parameters that achieves state-of-the-art image generation quality within 16 steps.
text-to-image

clarityai/crystal-video-upscaler
Do high precision video upscaling that respects the original video perfectly using Crystal Upscaler's new video upscaling method!
upscale
video-to-video
image-editing/object-removal
Remove unwanted objects or people from your photos while seamlessly blending the background.
stylized
transform
image-to-image



Fast inpainting endpoint for the FLUX.1 Kontext [dev] model with LoRA support, enabling rapid and high-quality image inpainting with reference images, while using pre-trained LoRA adaptations for specific styles, brand identities, and product-specific outputs.
image-editing
image-inpainting
image-to-image



Erase unwanted objects, people, or elements from video with a text prompt. High-fidelity output with strong temporal consistency, trained on licensed data for safe commercial use.
bria
video
erase
video-to-video



Kling AI Avatar Pro: The premium endpoint for creating avatar videos with realistic humans, animals, cartoons, or stylized characters
stylized
transform
image-to-video

MiniMax Hailuo-2.3-Fast Image To Video API (Pro, 1080p): Advanced fast image-to-video generation model with 1080p resolution
image-to-video
live-portrait/image
Transfer expression from a video to a portrait.
expression
animation
image-to-image

FLUX.3 is Black Forest Labs' frontier audio/video model. Generate fast, low-cost draft previews that animate a still image, with a reusable draft cache for full-quality enhancement.
stylized
transform
lipsync
image-to-video
cohere-transcribe
Cohere Transcribe turns your business audio into accurate text, ready for search, analytics, and automation
speech
transcribe
stt
speech-to-text

film
Interpolate images with FILM - Frame Interpolation for Large Motion
interpolation
image-to-image
new
meshy/t2/image-to-3d
Meshy T2 is Meshy's faster Smart Topology model. It converts a single image into a clean, triangle-only 3D mesh with natively separated parts, with a target polycount of up to 15,000 triangles (default 4,000). It generates faster than Meshy T2.5, which suits low-poly assets and speed-sensitive pipelines; optional textures, PBR maps and humanoid rigging are supported.
3d
smart-topology
low-poly
image-to-3d
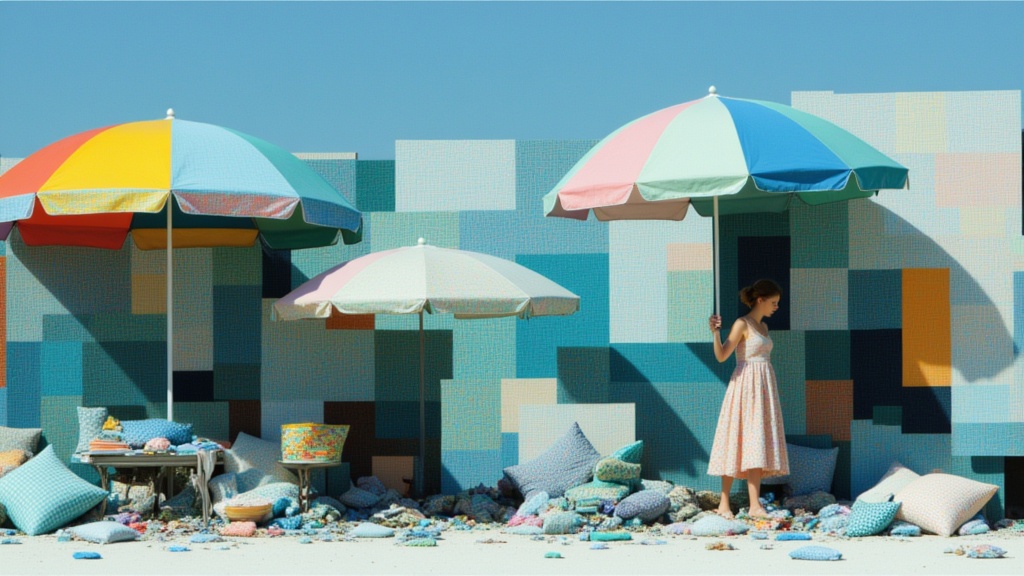
Generate high-fidelity images extremely fast from text with Krea 2 Medium Turbo, supporting aspect ratio, creativity, seed controls, and optional style references.
stylized
transform
typography
text-to-image
Showing 673 to 696 of 1432 results