Showing 1129 to 1152 of 1673 results

post-processing/blur
Apply Gaussian or Kuwahara blur effects with adjustable radius and sigma parameters
stylized
transform
image-to-image

PixVerse Extend model is a video extending tool for your videos using with high-quality video extending techniques
utility
editing
video-to-video
PixVerse Extend model is a video extending tool for your videos using with high-quality video extending techniques
utility
editing
video-to-video
Generate realistic lipsync animations from audio using advanced algorithms for high-quality synchronization with PixVerse Lipsync model
animation
lip sync
video-to-video
image-editing/youtube-thumbnails
Generate YouTube thumbnails with custom text
stylized
transform
image-to-image


Automatically remove backgrounds from videos -perfect for creating clean, professional content without a green screen.
background-removal
video-to-video


LoRA trainer for FLUX.1 Kontext [dev]
training
image-editing/broccoli-haircut
Transform your character's hair into broccoli style while keeping the original characters likeness
stylized
transform
image-to-image
image-editing/wojak-style
Transform your photos into wojak style while keeping the original characters likeness
stylized
transform
image-to-image
image-editing/plushie-style
Transform your photos into cool plushies while keeping the original characters likeness
stylized
transform
image-to-image
Super fast text-to-image endpoint for the FLUX.1 Kontext [dev] model with LoRA support, enabling rapid and high-quality image generation using pre-trained LoRA adaptations for personalization, specific styles, brand identities, and product-specific outputs.
text-to-image

Fast endpoint for the FLUX.1 Kontext [dev] model with LoRA support, enabling rapid and high-quality image editing using pre-trained LoRA adaptations for specific styles, brand identities, and product-specific outputs.
image-editing
image-to-image
omnigen-v2
OmniGen is a unified image generation model that can generate a wide range of images from multi-modal prompts. It can be used for various tasks such as Image Editing, Personalized Image Generation, Virtual Try-On, Multi Person Generation and more!
multimodal
editing
try-on
text-to-image
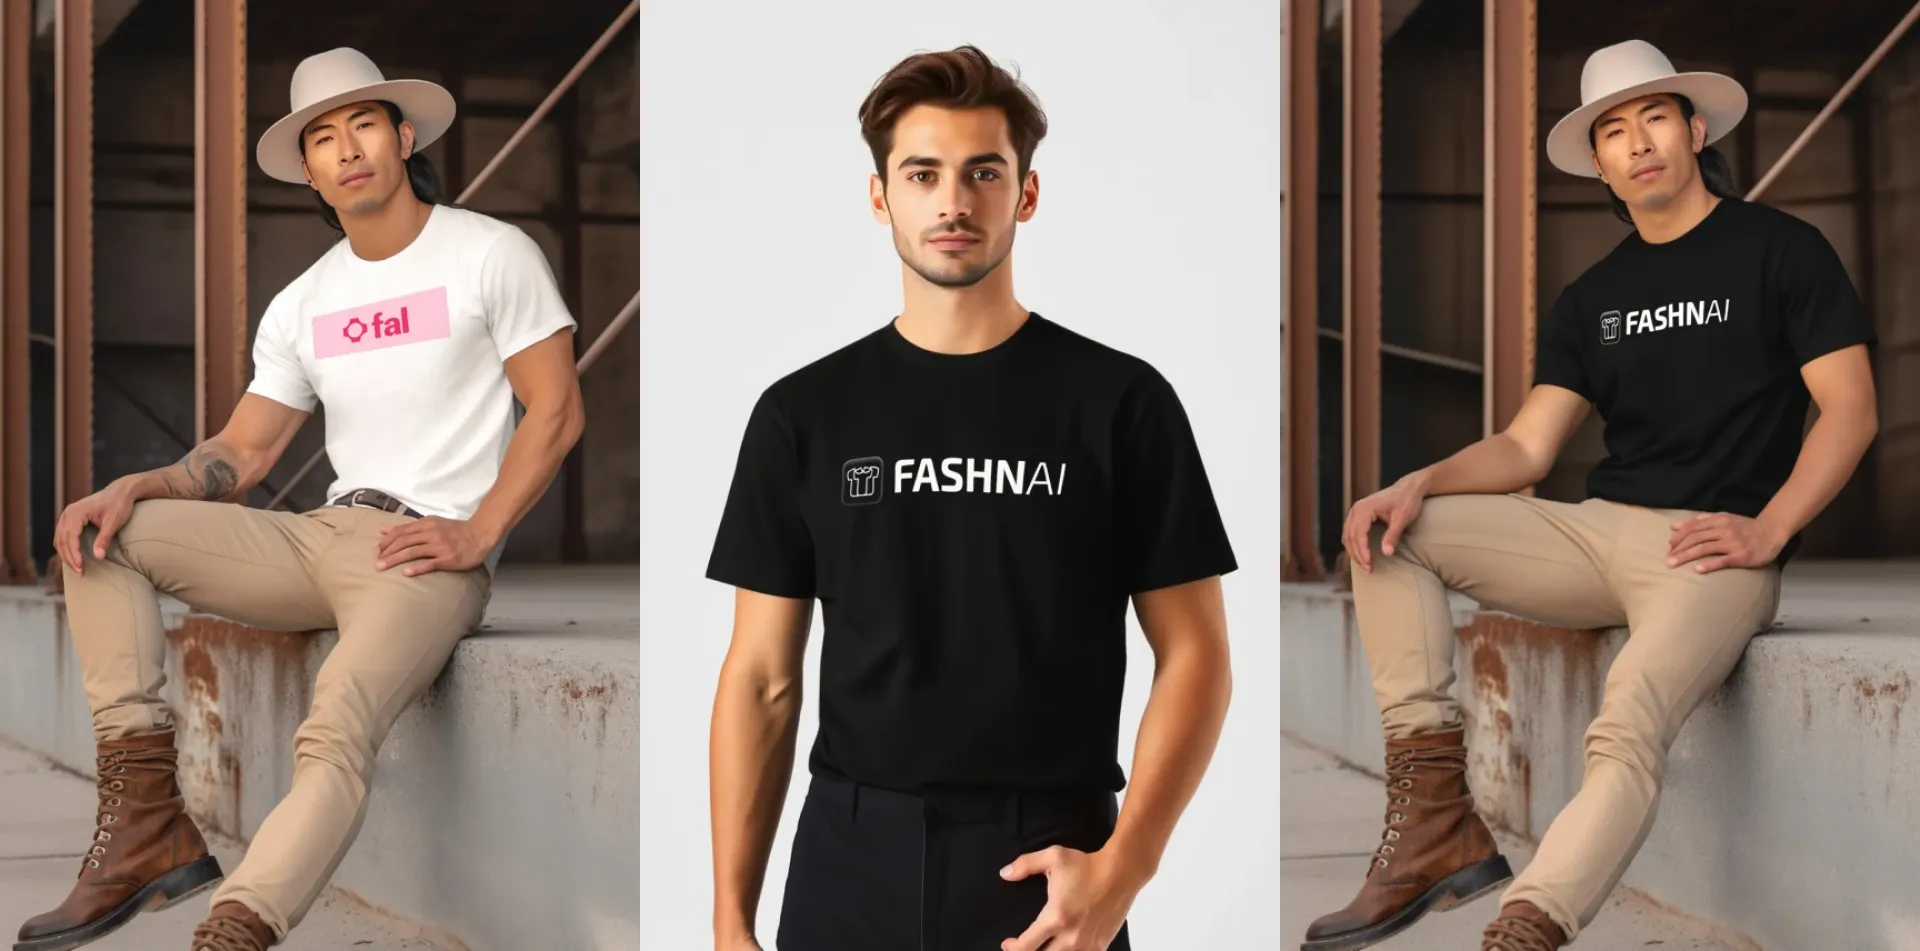
fashn/tryon/v1.6
FASHN v1.6 delivers precise virtual try-on capabilities, accurately rendering garment details like text and patterns at 864x1296 resolution from both on-model and flat-lay photo references.
try-on
fashion
clothing
image-to-image
ai-avatar/single-text
MultiTalk model generates a talking avatar video from an image and text. Converts text to speech automatically, then generates the avatar speaking with lip-sync.
stylized
transform
image-to-video
ai-avatar
MultiTalk model generates a talking avatar video from an image and audio file. The avatar lip-syncs to the provided audio with natural facial expressions.
deprecated
stylized
transform
image-to-video
ai-avatar/multi-text
MultiTalk model generates a multi-person conversation video from an image and text inputs. Converts text to speech for each person, generating a realistic conversation scene.
stylized
transform
image-to-video
ai-avatar/multi
MultiTalk model generates a multi-person conversation video from an image and audio files. Creates a realistic scene where multiple people speak in sequence.
stylized
transform
image-to-video
video-understanding
A video understanding model to analyze video content and answer questions about what's happening in the video based on user prompts.
utility
vision


VACE is a video generation model that uses a source image, mask, and video to create prompted videos with controllable sources.
reframe
video-to-video
VACE is a video generation model that uses a source image, mask, and video to create prompted videos with controllable sources.
image-to-video
text-to-video
video-to-video
VACE is a video generation model that uses a source image, mask, and video to create prompted videos with controllable sources.
image-to-video
text-to-video
video-to-video
VACE is a video generation model that uses a source image, mask, and video to create prompted videos with controllable sources.
image-to-video
text-to-video
video-to-video
VACE is a video generation model that uses a source image, mask, and video to create prompted videos with controllable sources.
image-to-video
text-to-video
video-to-video
Showing 1129 to 1152 of 1673 results