Showing 1633 to 1656 of 1705 results
skyreels-i2v
SkyReels V1 is the first and most advanced open-source human-centric video foundation model. By fine-tuning HunyuanVideo on O(10M) high-quality film and television clips
deprecated
motion
image-to-video
flowedit
The model provides you high quality image editing capabilities.
deprecated
editing
image-to-image
got-ocr/v2
GOT-OCR2 works on a wide range of tasks, including plain document OCR, scene text OCR, formatted document OCR, and even OCR for tables, charts, mathematical formulas, geometric shapes, molecular formulas and sheet music.
deprecated
optical character recognition
high-res
utility
vision


FLUX Control LoRA Canny is a high-performance endpoint that uses a control image using a Canny edge map to transfer structure to the generated image and another initial image to guide color.
deprecated
lora
style transfer
image-to-image
FLUX Control LoRA Canny is a high-performance endpoint that uses a control image to transfer structure to the generated image, using a Canny edge map.
deprecated
lora
style transfer
text-to-image


Imagen3 is a high-quality text-to-image model that generates realistic images from text prompts.
deprecated
text-to-image
Imagen3 Fast is a high-quality text-to-image model that generates realistic images from text prompts.
deprecated
text-to-image
hunyuan-video-img2vid-lora
Image to Video for the Hunyuan Video model using a custom trained LoRA.
deprecated
motion
image-to-video
hunyuan-video-lora/video-to-video
Hunyuan Video is an Open video generation model with high visual quality, motion diversity, text-video alignment, and generation stability. Use this endpoint to generate videos from videos.
deprecated
video to video
motion
lora
video-to-video
janus
DeepSeek Janus-Pro is a novel text-to-image model that unifies multimodal understanding and generation through an autoregressive framework
deprecated
stylized
text-to-image
yue
YuE is a groundbreaking series of open-source foundation models designed for music generation, specifically for transforming lyrics into full songs.
deprecated
music
text-to-audio
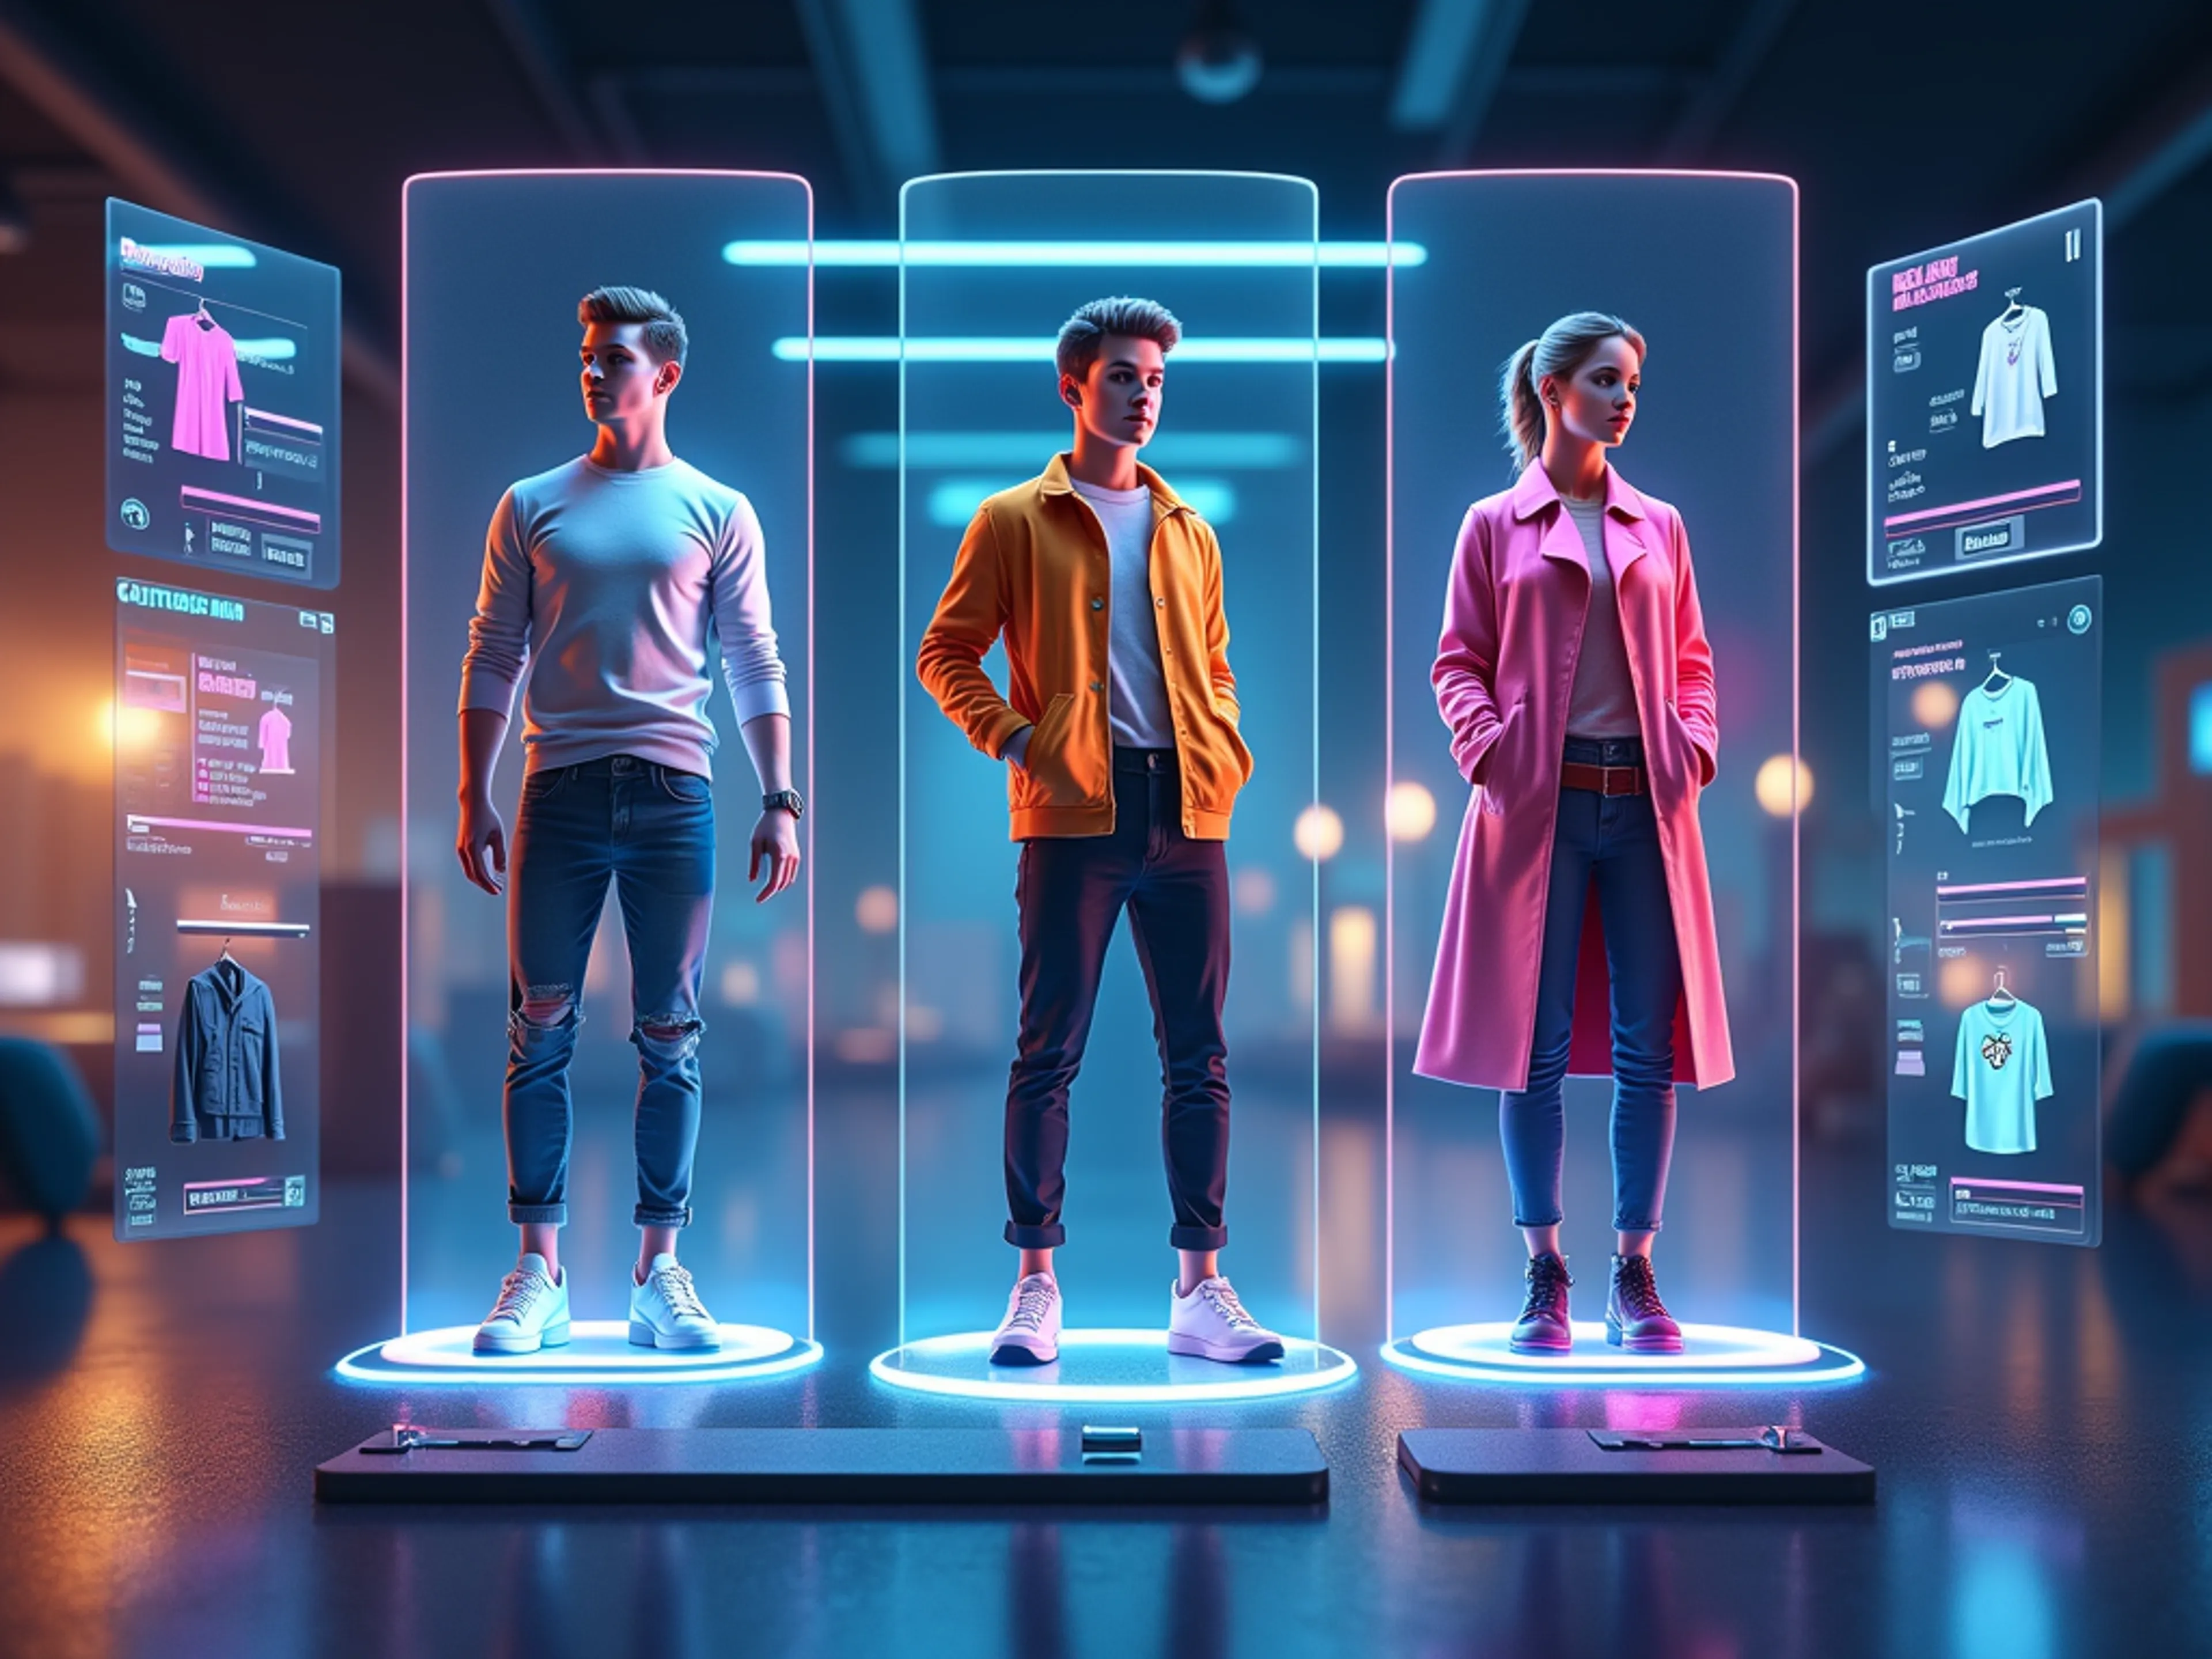


Kling Kolors Virtual TryOn v1.5 is a high quality image based Try-On endpoint which can be used for commercial try on.
deprecated
try-on
fashion
clothing
image-to-image
hunyuan-video-lora
Hunyuan Video is an Open video generation model with high visual quality, motion diversity, text-video alignment, and generation stability
deprecated
text-to-video
cogvideox-5b
Generate videos from prompts using CogVideoX-5B
deprecated
text-to-video
transpixar
Transform text into stunning videos with TransPixar - an AI model that generates both RGB footage and alpha channels, enabling seamless compositing and creative video effects.
deprecated
text-to-video
hunyuan-video-lora-training
Train Hunyuan Video lora on people, objects, characters and more!
deprecated
lora
personalization
training
Generate video clips from your images using Kling 1.6 (std)
deprecated
image-to-video
Generate video clips from your prompts using Kling 1.6 (std)
deprecated
text-to-video
Generate video clips from your images using Kling 1.6 (pro)
deprecated
image-to-video
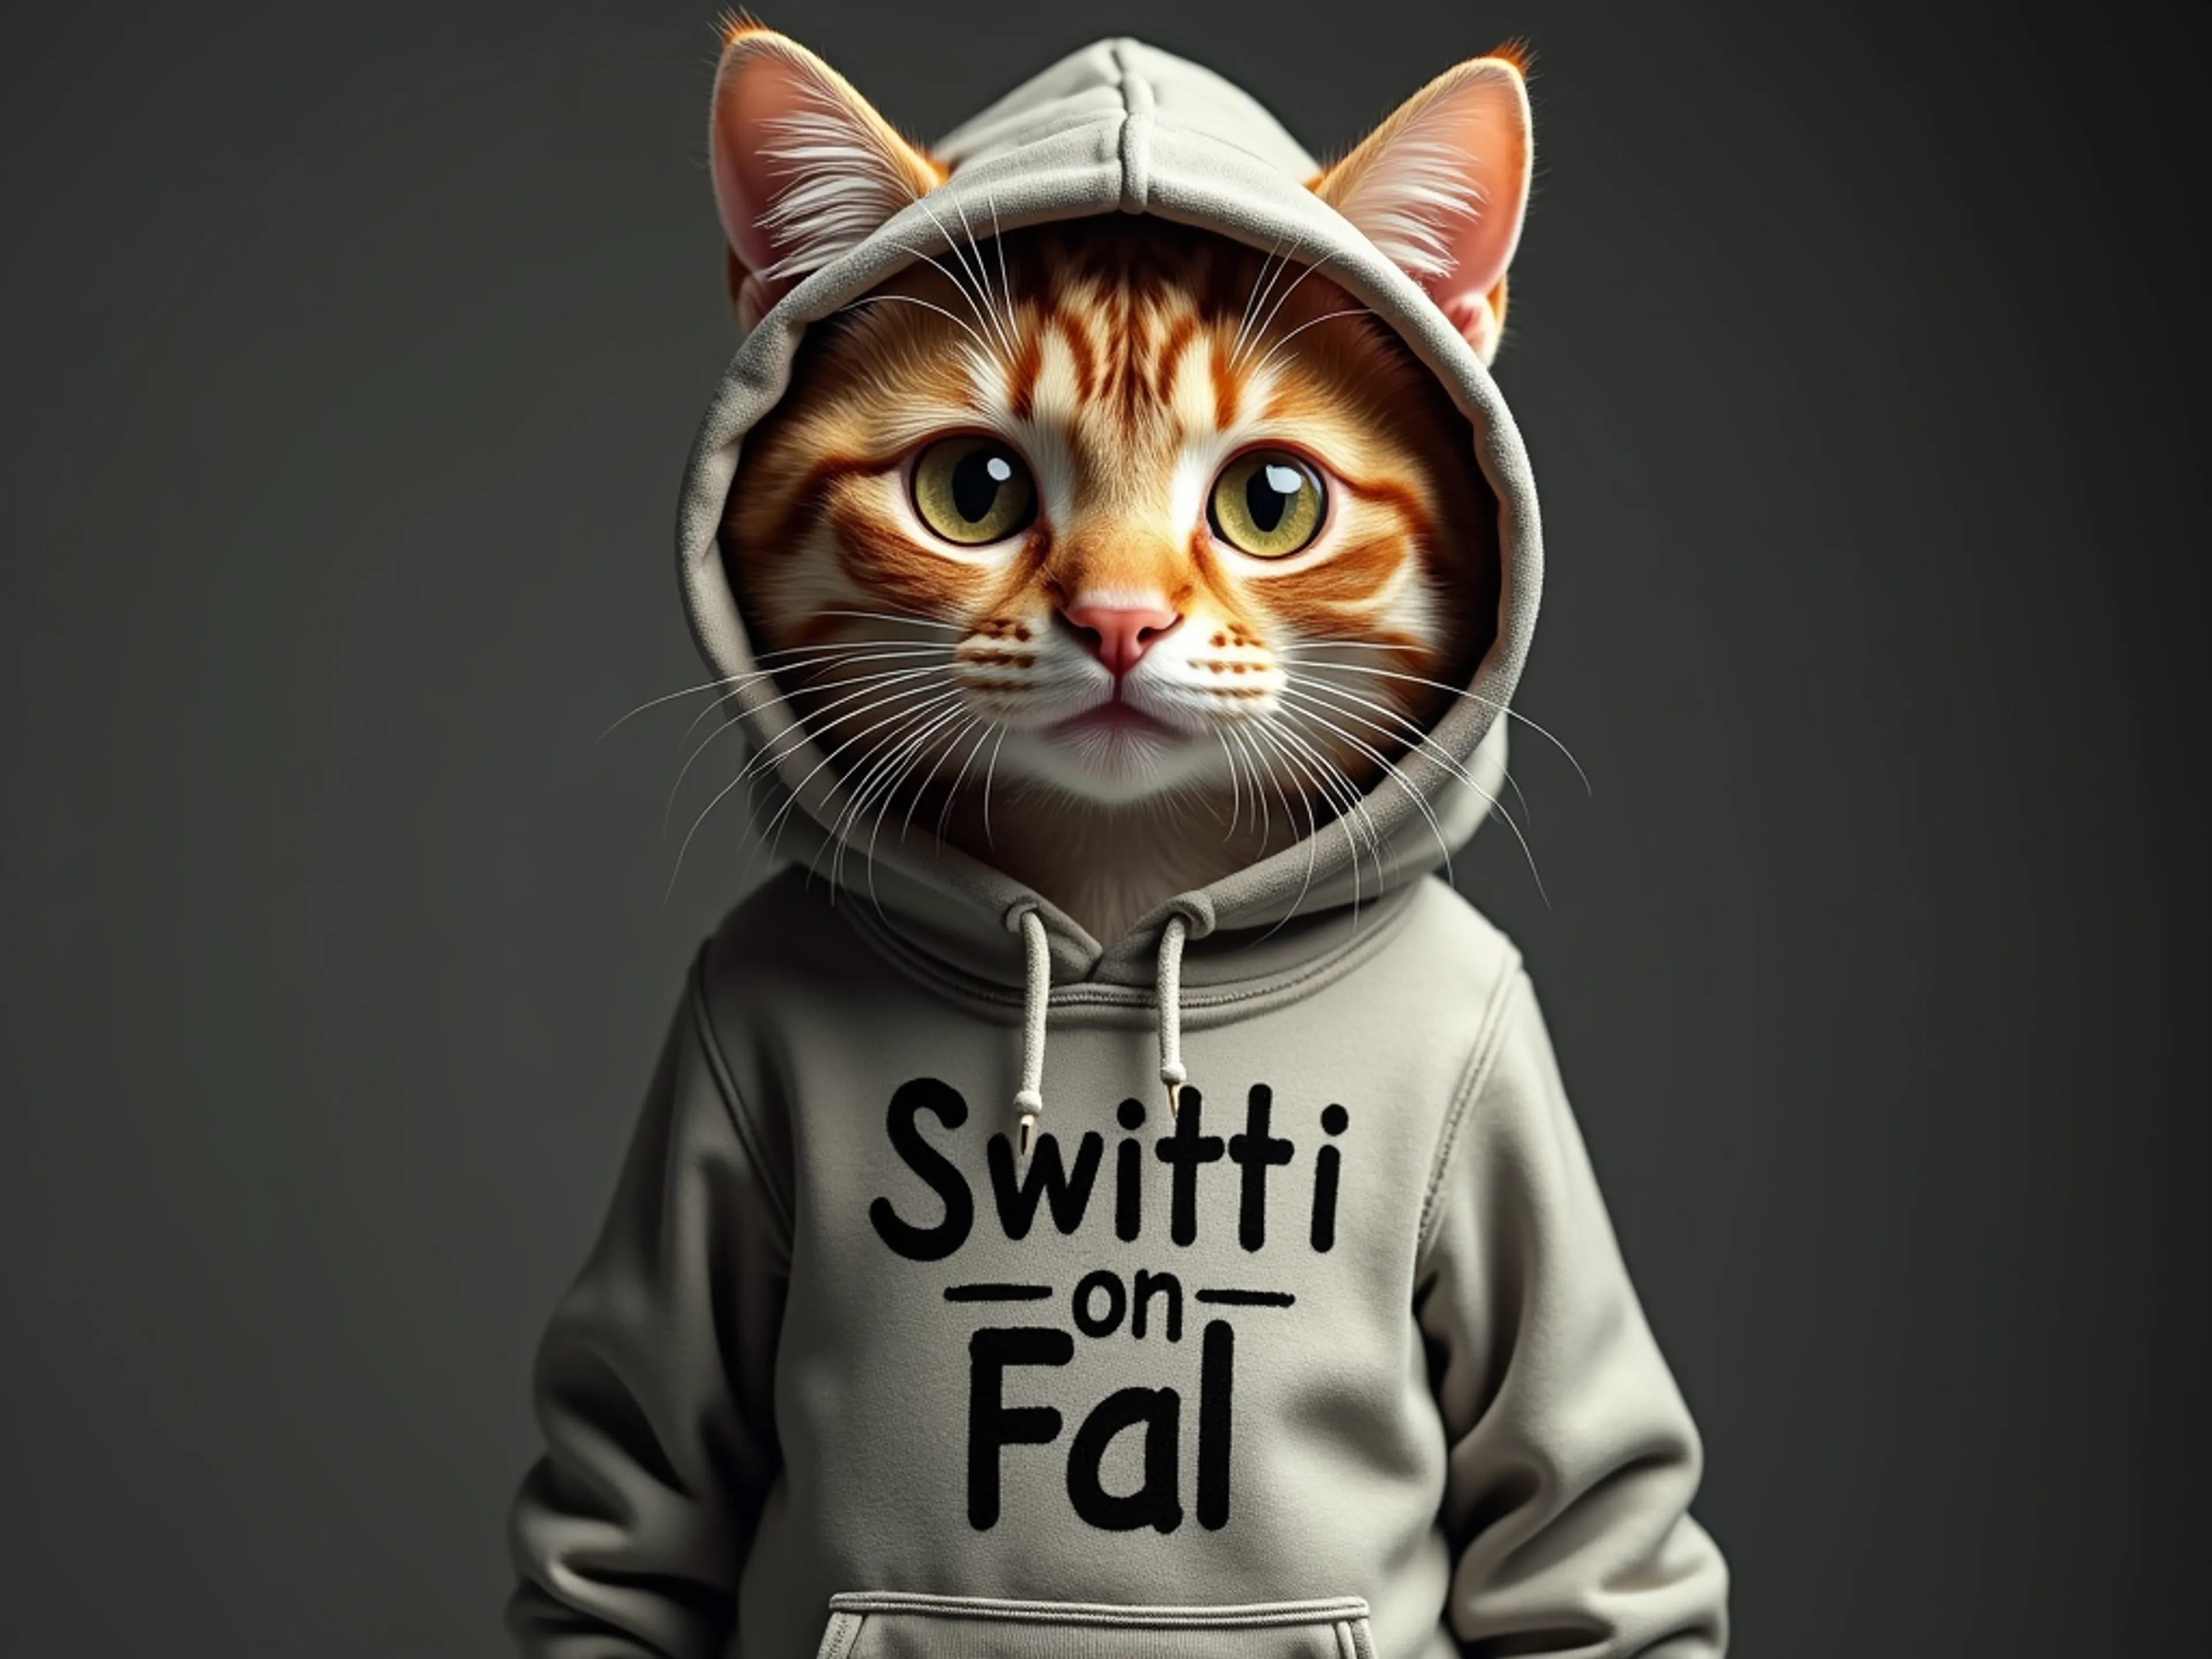
switti
Switti is a scale-wise transformer for fast text-to-image generation that outperforms existing T2I AR models and competes with state-of-the-art T2I diffusion models while being faster than distilled diffusion models.
deprecated
text-to-image
switti/512
Switti is a scale-wise transformer for fast text-to-image generation that outperforms existing T2I AR models and competes with state-of-the-art T2I diffusion models while being faster than distilled diffusion models.
deprecated
text-to-image
dubbing
This endpoint delivers seamlessly localized videos by generating lip-synced dubs in multiple languages, ensuring natural and immersive multilingual experiences
deprecated
animation
lip sync
dubbing
video-to-video
Generate video clips from your prompts using Kling 1.0
deprecated
motion
text-to-video
aura-flow
AuraFlow v0.3 is an open-source flow-based text-to-image generation model that achieves state-of-the-art results on GenEval. The model is currently in beta.
deprecated
typography
style
text-to-image
Showing 1633 to 1656 of 1705 results