Showing 745 to 768 of 1684 results

Generate music from text prompts using the MiniMax model, which leverages advanced AI techniques to create high-quality, diverse musical compositions.
music
text-to-audio
workflow-utilities/blend-video
FFMPEG Utility for Blending Videos
video-to-video


VACE is a video generation model that uses a source image, mask, and video to create prompted videos with controllable sources.
image-to-video
text-to-video
video-to-video


FLUX Control LoRA Depth is a high-performance endpoint that uses a control image using a depth map to transfer structure to the generated image and another initial image to guide color.
lora
style transfer
image-to-image
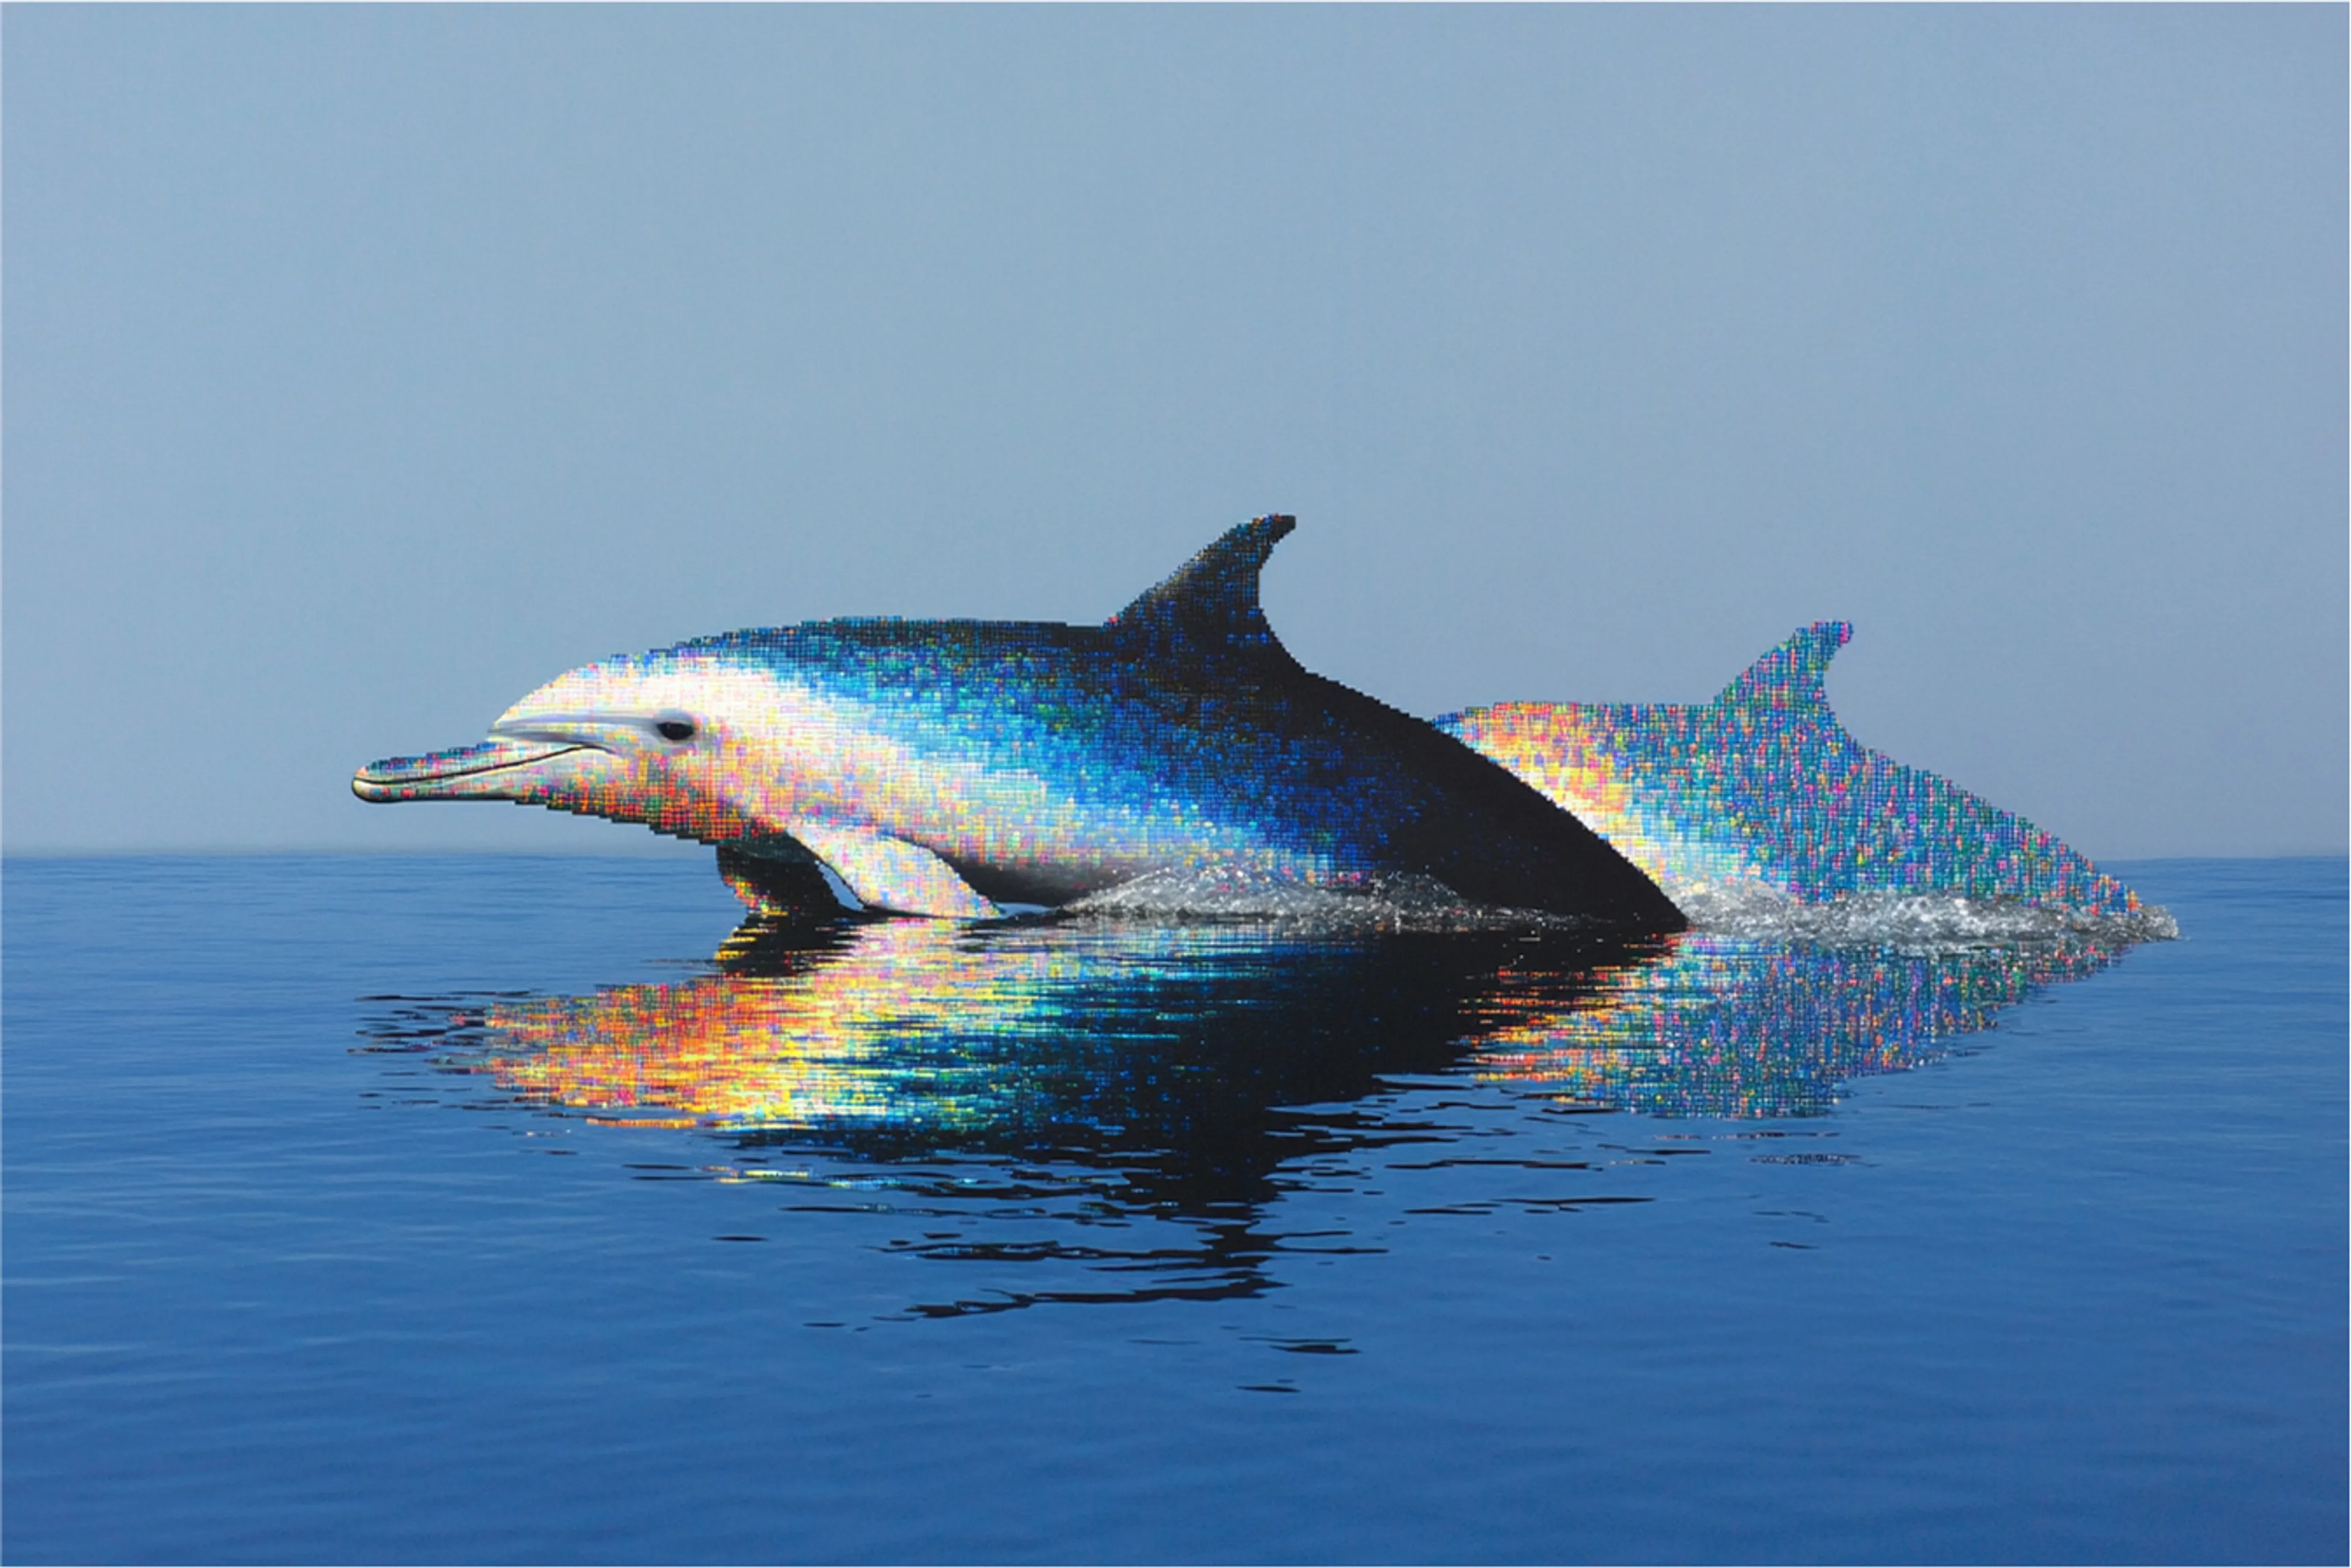
image-editing/background-change
Replace your photo's background with any scene you desire, from beach sunsets to urban landscapes, with perfect lighting and shadows
stylized
transform
image-to-image


Build real-time voice applications powered by Grok. Stream audio and text bidirectionally via WebSocket for voice assistants, phone agents, and interactive voice systems.
xai
grok
voice
speech-to-speech
dia-tts
Dia directly generates realistic dialogue from transcripts. Audio conditioning enables emotion control. Produces natural nonverbals like laughter and throat clearing.
text-to-speech
kokoro/spanish
A natural-sounding Spanish text-to-speech model optimized for Latin American and European Spanish.
speech
text-to-audio


Seed 2.0 Mini is a high-performance multimodal model optimized for low latency and high concurrency. It supports text, image, and video input with 256K context and configurable thinking/reasoning modes.
llm


Erase unwanted objects, people, or elements from video with a text prompt. High-fidelity output with strong temporal consistency, trained on licensed data for safe commercial use.
bria
video
erase
video-to-video
image-preprocessors/lineart
Line art preprocessor.
preprocess
utility
sketch
image-to-image
openrouter/router/enterprise
Run any LLM (Large Language Model) with fal, powered by OpenRouter.
llm
Wan-2.2 video-to-video is a video model that generates high-quality videos with high visual quality and motion diversity from text prompts and source videos.
video-to-video
cat-vton
Image based high quality Virtual Try-On
try-on
fashion
clothing
image-to-image
Images into video with synchronized audio using MiniMax H3; your image becomes the first frame, prompt optional, with trained LoRA support for subject consistency.
utility
editing
image-to-video
Wan 2.5 image-to-image model.
image-to-image
vidu/q3/text-to-video/turbo
Vidu's Q3 Turbo Model.
text-to-video

Generate film-grade videos from text prompts with native audio, up to 1080p and 15 seconds, using PixVerse C1.
video-generation
pixverse
cinematic
text-to-video
image-editing/hair-change
Experiment with different hairstyles, from bald to any style you can imagine, while maintaining natural lighting and realistic results.
stylized
transform
image-to-image
sam-audio/span-separate
Audio separation with SAM Audio. Isolate any sound using natural language—professional-grade audio editing made simple for creators, researchers, and accessibility applications.
sam-audio
audio-to-audio
Endpoint for Qwen's Image Editing Plus model also known as Qwen-Image-Edit-2509. Has superior text editing capabilities and multi-image support.
image-editing
high-quality-text
image-to-image
LoRA endpoint for the Qwen Image Edit Plus model.
image-editing
image-to-image
Image-to-image editing with LoRA support for FLUX.2 [klein] 4B Base from Black Forest Labs. Specialized style transfer and domain-specific modifications.
image-to-image


Transform images, elements, and text into consistent, high-quality video scenes, ensuring stable character identity, object details, and environments.
image-to-video
Showing 745 to 768 of 1684 results