Z-Image Turbo ControlNet | [image-to-image]
Tongyi-MAI's Z-Image Turbo delivers ControlNet-guided image generation at $0.0065 per megapixel through a 6-billion parameter architecture. This model trades raw parameter count for specialized control mechanisms, canny edge detection, depth mapping, and pose guidance, that preserve structural fidelity during image-to-image transformations. Built for designers and developers who need precise spatial control without the inference overhead of larger diffusion models.
Use Cases: Product visualization with reference geometry | Character pose transfer workflows | Architectural rendering from depth maps
Z-Image Turbo operates at roughly 3-5x more cost-effective rates than traditional ControlNet implementations by optimizing the 6B parameter base for rapid inference. At $0.0065 per megapixel, you're running 153 megapixels per dollar, ideal for batch processing workflows where structural guidance matters more than photorealistic perfection.
| Metric | Result | Context |
|---|
| Model Size | 6 billion parameters | Optimized for inference speed vs 70B+ alternatives |
| Inference Steps | 1-8 configurable | Default 8 steps balances quality and latency |
| Cost per Megapixel | $0.0065 | 153 megapixels per $1.00 on fal |
| Control Methods | 4 preprocessing modes | None, canny edge, depth map, pose detection |
| Batch Generation | Up to 4 images per request | Parallel generation with shared control input |
| Related Endpoints | Standard image-to-image, LoRA variants | ControlNet vs direct transformation vs custom training |
Structural Control Without Compromise
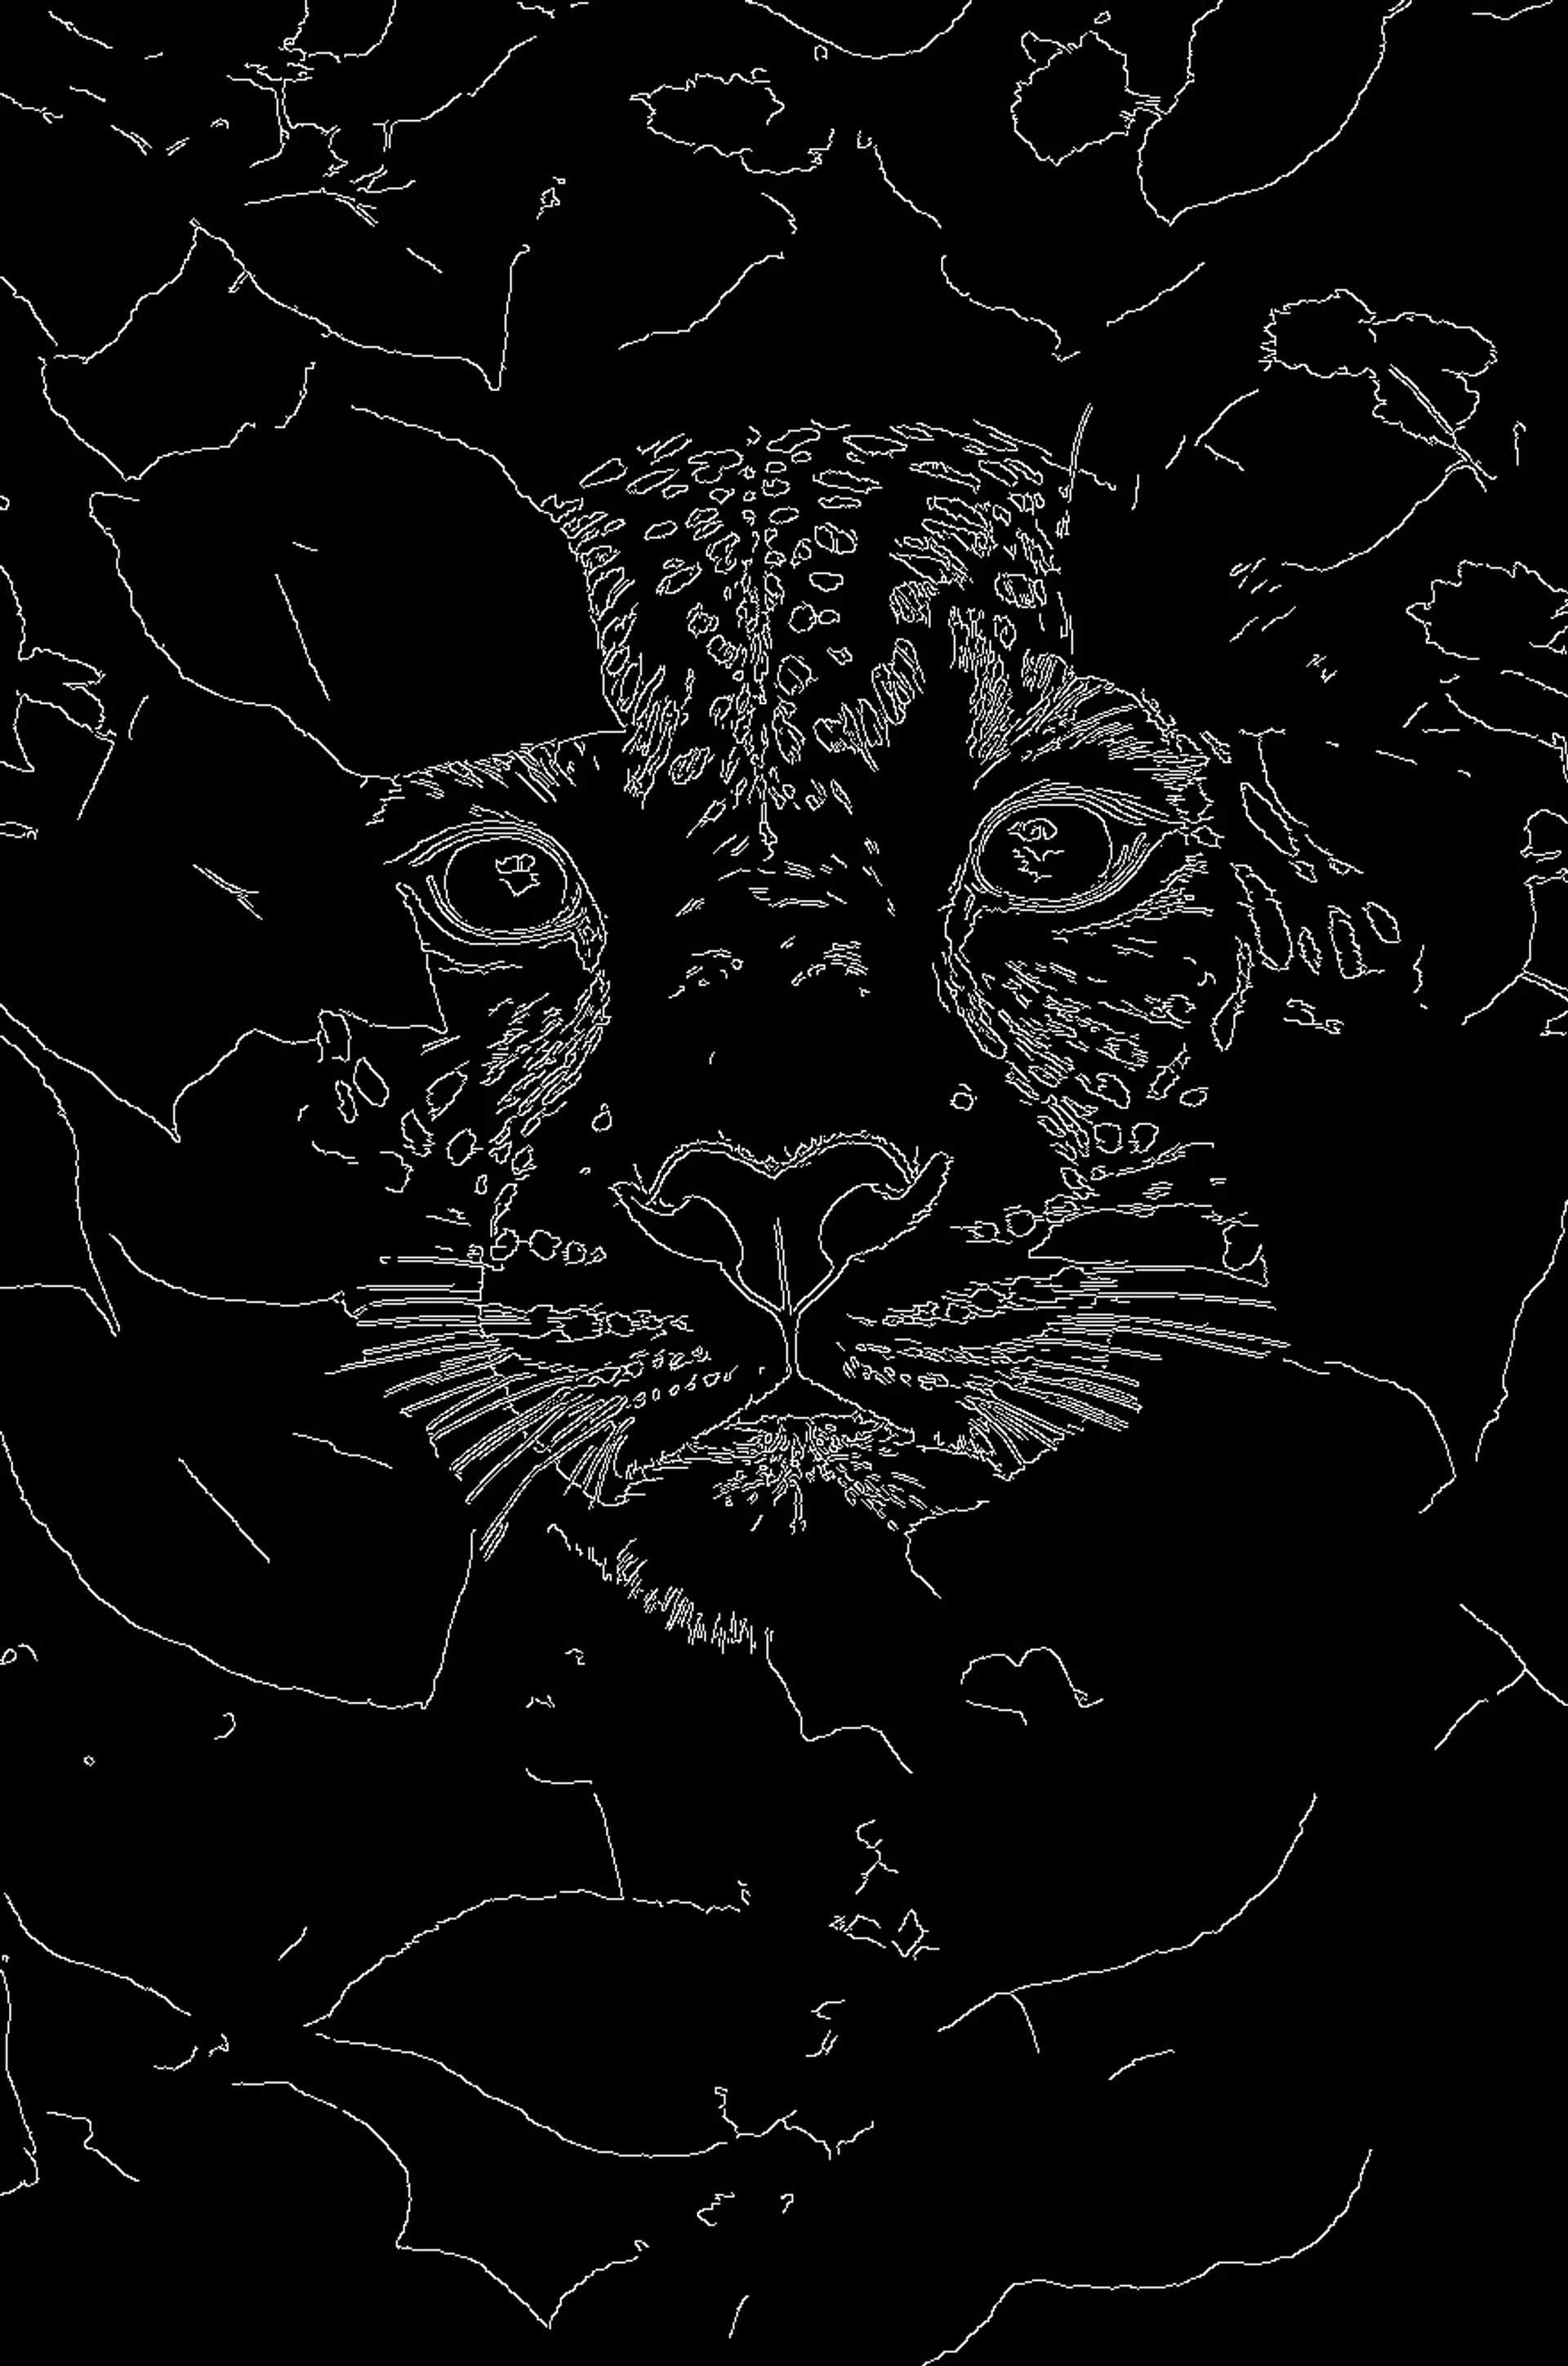
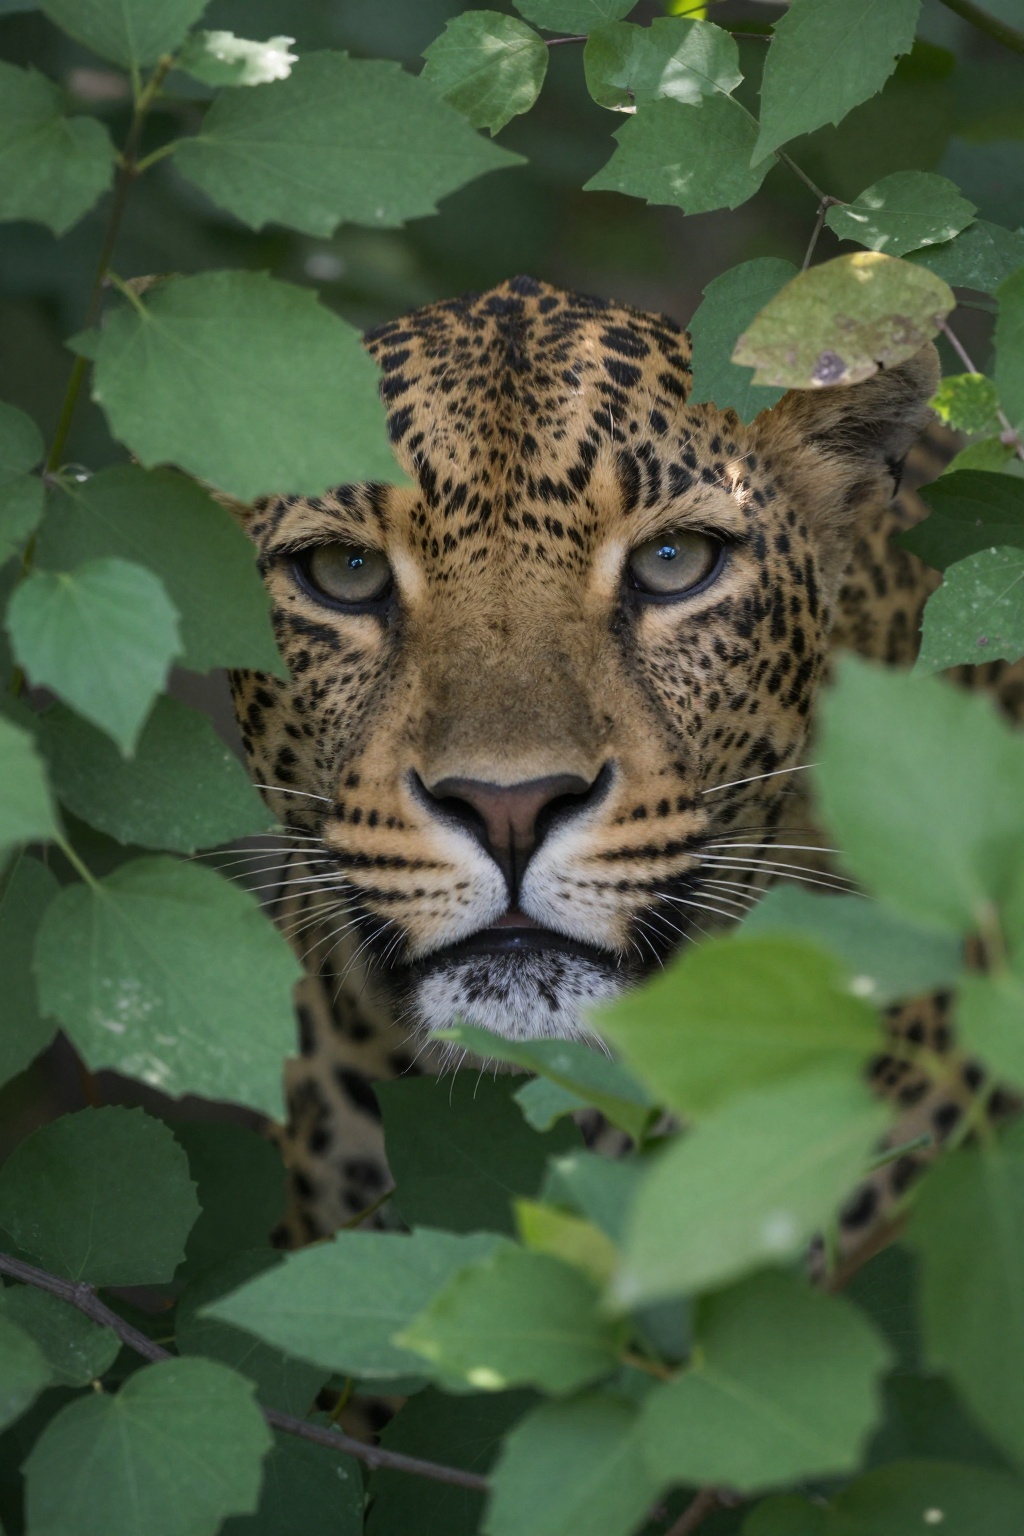
Z-Image Turbo routes your prompt through three parallel conditioning pathways: text embedding, reference image structure, and optional preprocessing filters. Unlike pure text-to-image models that hallucinate spatial relationships, this architecture extracts edge maps, depth channels, or skeletal poses from your input, then enforces those constraints during diffusion.
What this means for you:
- Configurable control strength (0-1 scale): Dial conditioning intensity from 0.9 for strict adherence to 0.3 for loose interpretation, critical when your reference image has good composition but needs significant style deviation
- Temporal control windowing: Apply ControlNet guidance only during steps 0-40% of generation (configurable start/end), letting early diffusion lock structure while late steps refine aesthetics
- Four preprocessing modes: Feed raw images directly or auto-extract canny edges (sharp boundaries), depth maps (spatial layering), or pose skeletons (human/character positioning) without external tools
- Multi-format output with safety: Generate 1-4 variants simultaneously in JPEG, PNG, or WebP with optional built-in safety filtering, batch testing style variations while maintaining structural consistency
Technical Specifications
| Spec | Details |
|---|
| Architecture | Z-Image Turbo 6B |
| Input Formats | Text prompt + reference image URL (JPEG, PNG, WebP, GIF, AVIF) |
| Output Formats | JPEG, PNG, WebP with configurable dimensions |
| Preprocessing Options | None, Canny edge detection, Depth estimation, Pose detection |
| Control Parameters | Scale (0-1), temporal start/end windowing, inference steps (1-8) |
| License | Commercial use permitted |
API Documentation | Quickstart Guide | Enterprise Pricing
How It Stacks Up
Z-Image Turbo Standard ($0.0065/MP) – The ControlNet variant adds structural guidance preprocessing for $0.0065 per megapixel, same base cost. Standard image-to-image prioritizes direct style transfer without intermediate edge/depth extraction, ideal for texture swaps and color grading where spatial relationships already match your target. ControlNet trades processing simplicity for precise geometric control when your reference structure needs enforcement.
FASHN Virtual Try-On V1.5 – Z-Image Turbo ControlNet offers general-purpose structural conditioning across edge, depth, and pose modalities for diverse creative workflows. FASHN specializes in garment-to-body fitting with proprietary try-on algorithms optimized for fashion e-commerce, trading generality for domain-specific accuracy in clothing visualization.
 fal-ai/z-image/turbo/controlnet