Best AI Image Generators
Unlock the future of creativity with these text to image, AI image generator models.
Showing 73 to 96 of 223 results
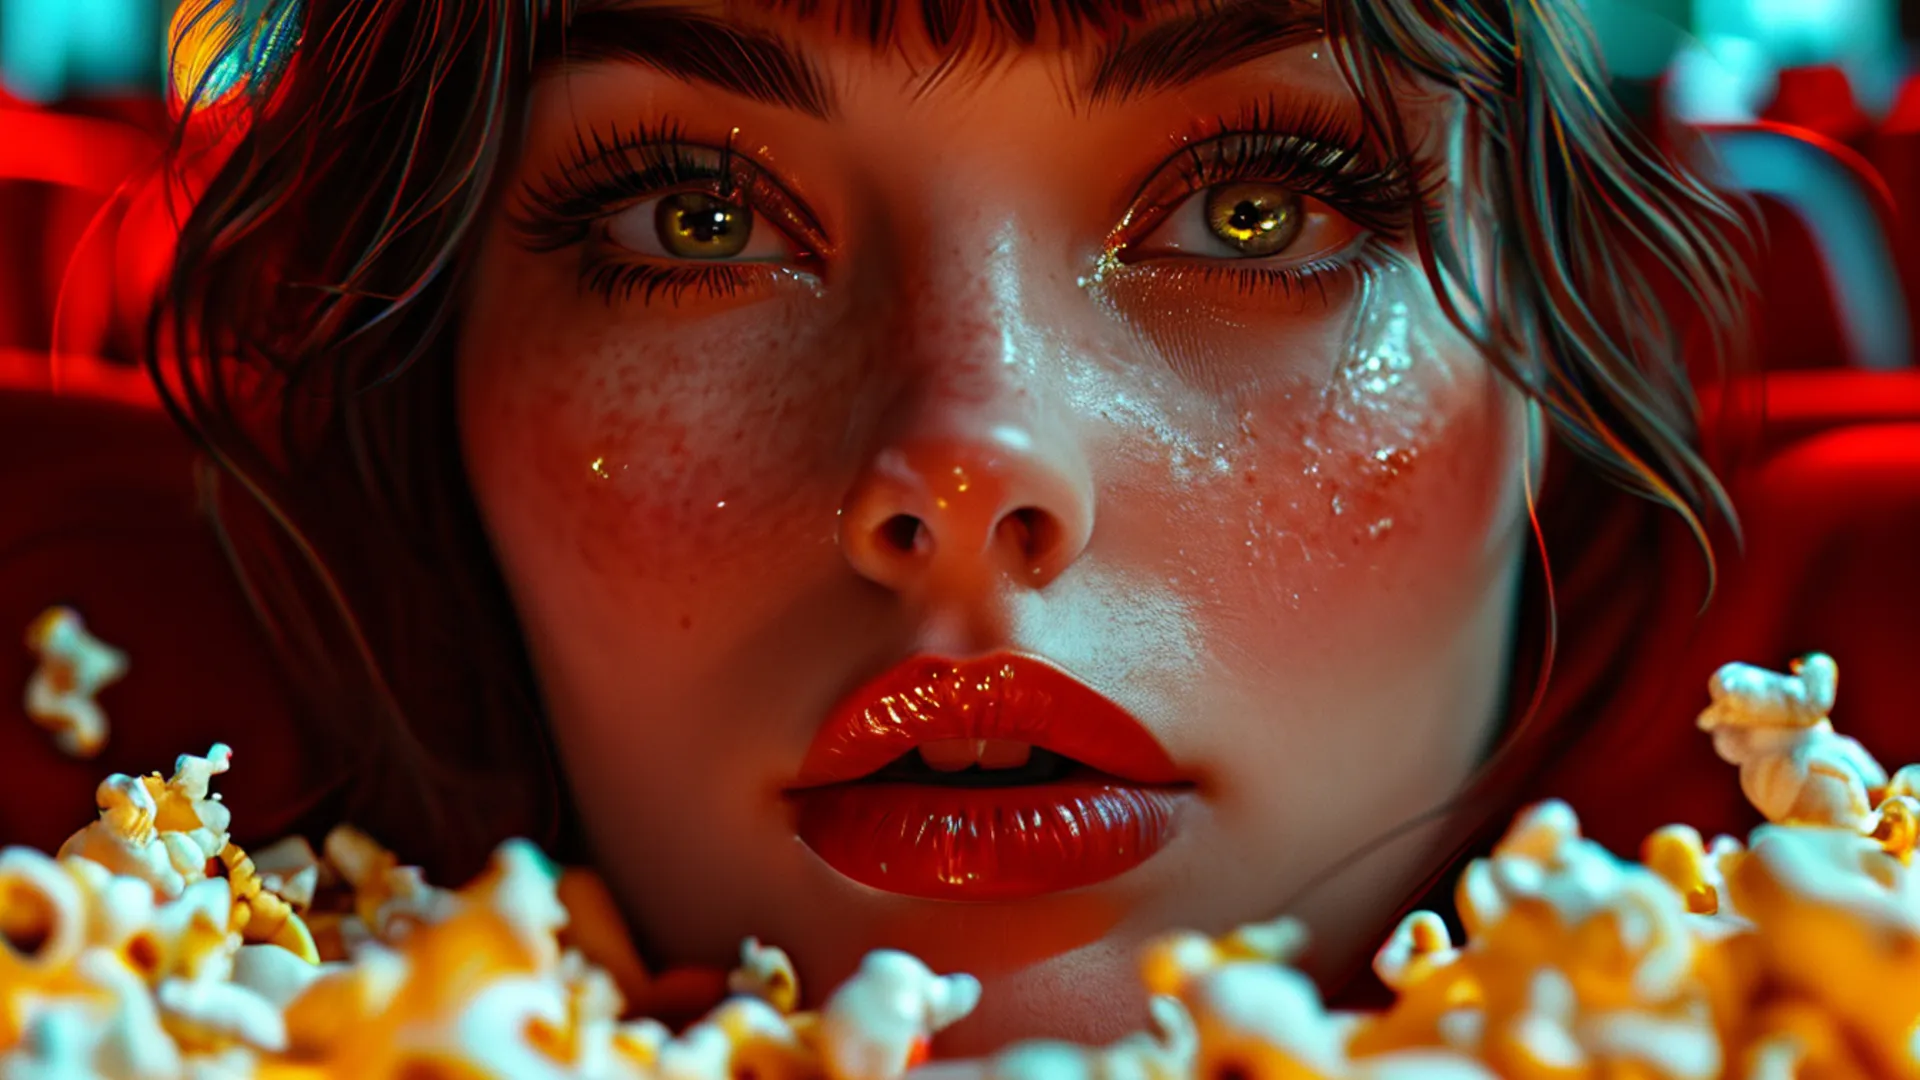
Sana can synthesize high-resolution, high-quality images with strong text-image alignment at a remarkably fast speed, with the ability to generate 4K images in less than a second.
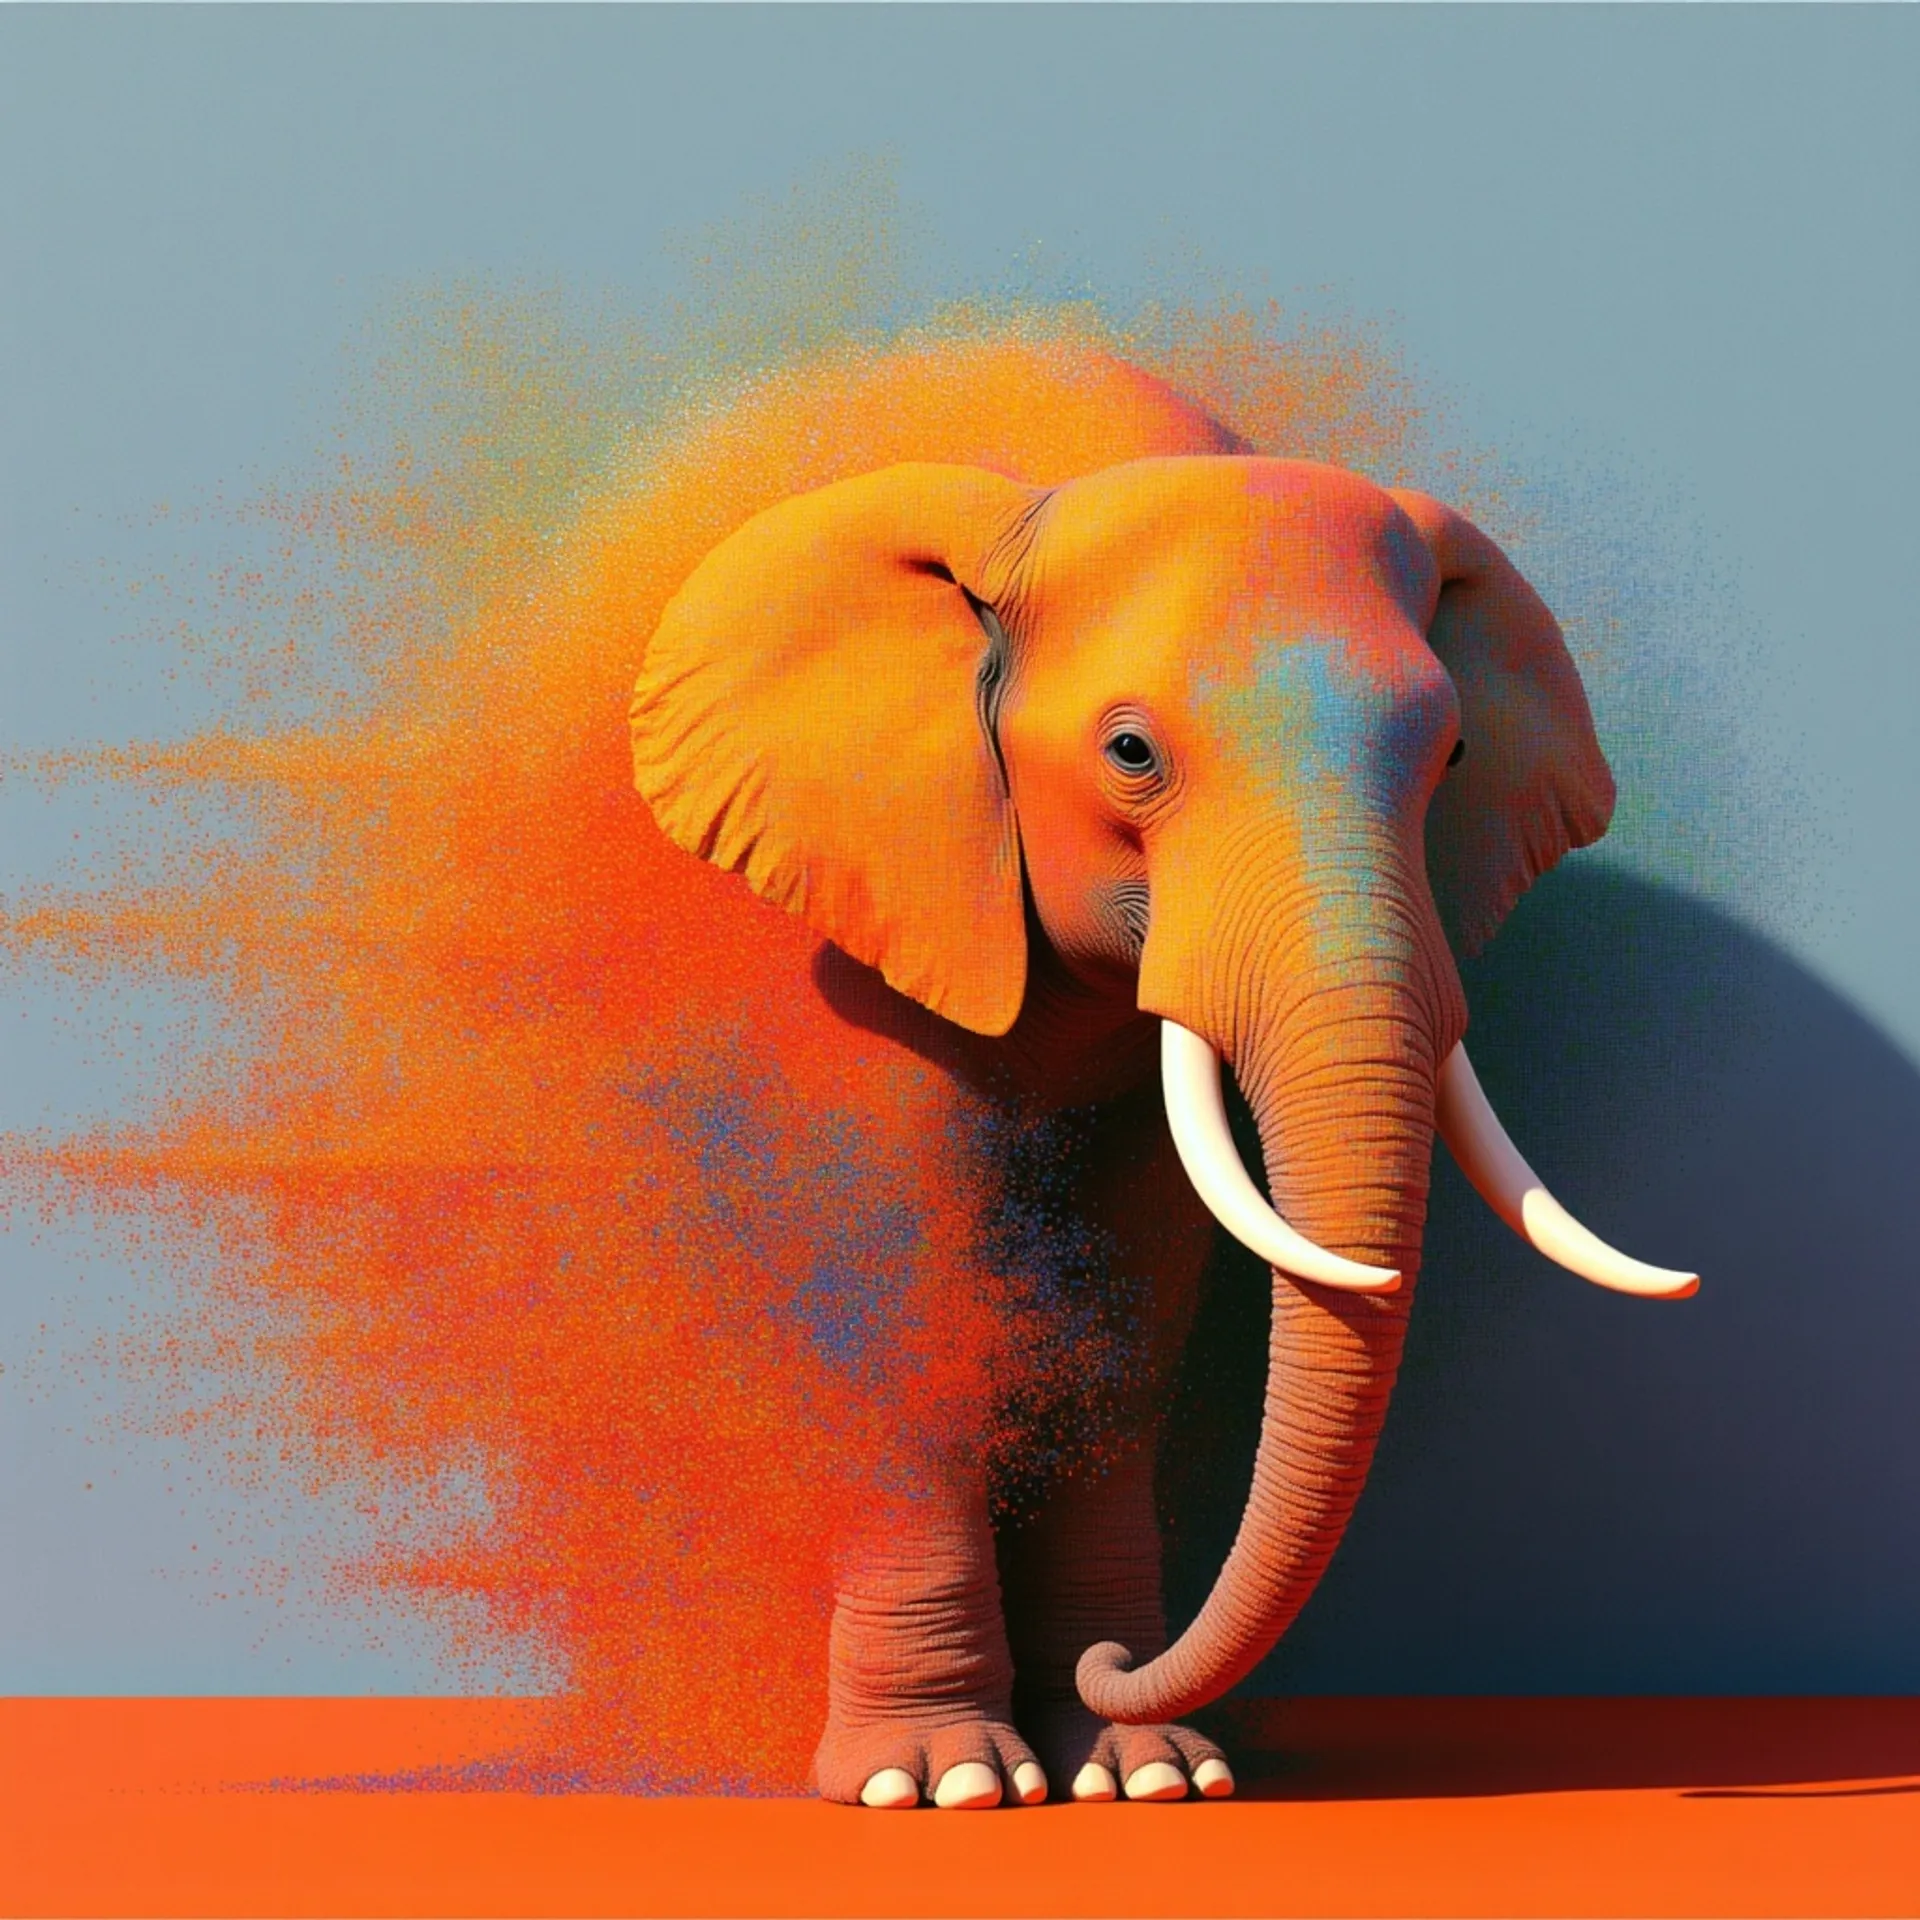
Leverage the state-of-the-art capabilities of Hunyuan Image 3.0 to generate visual content that effectively conveys the messaging of your written material.
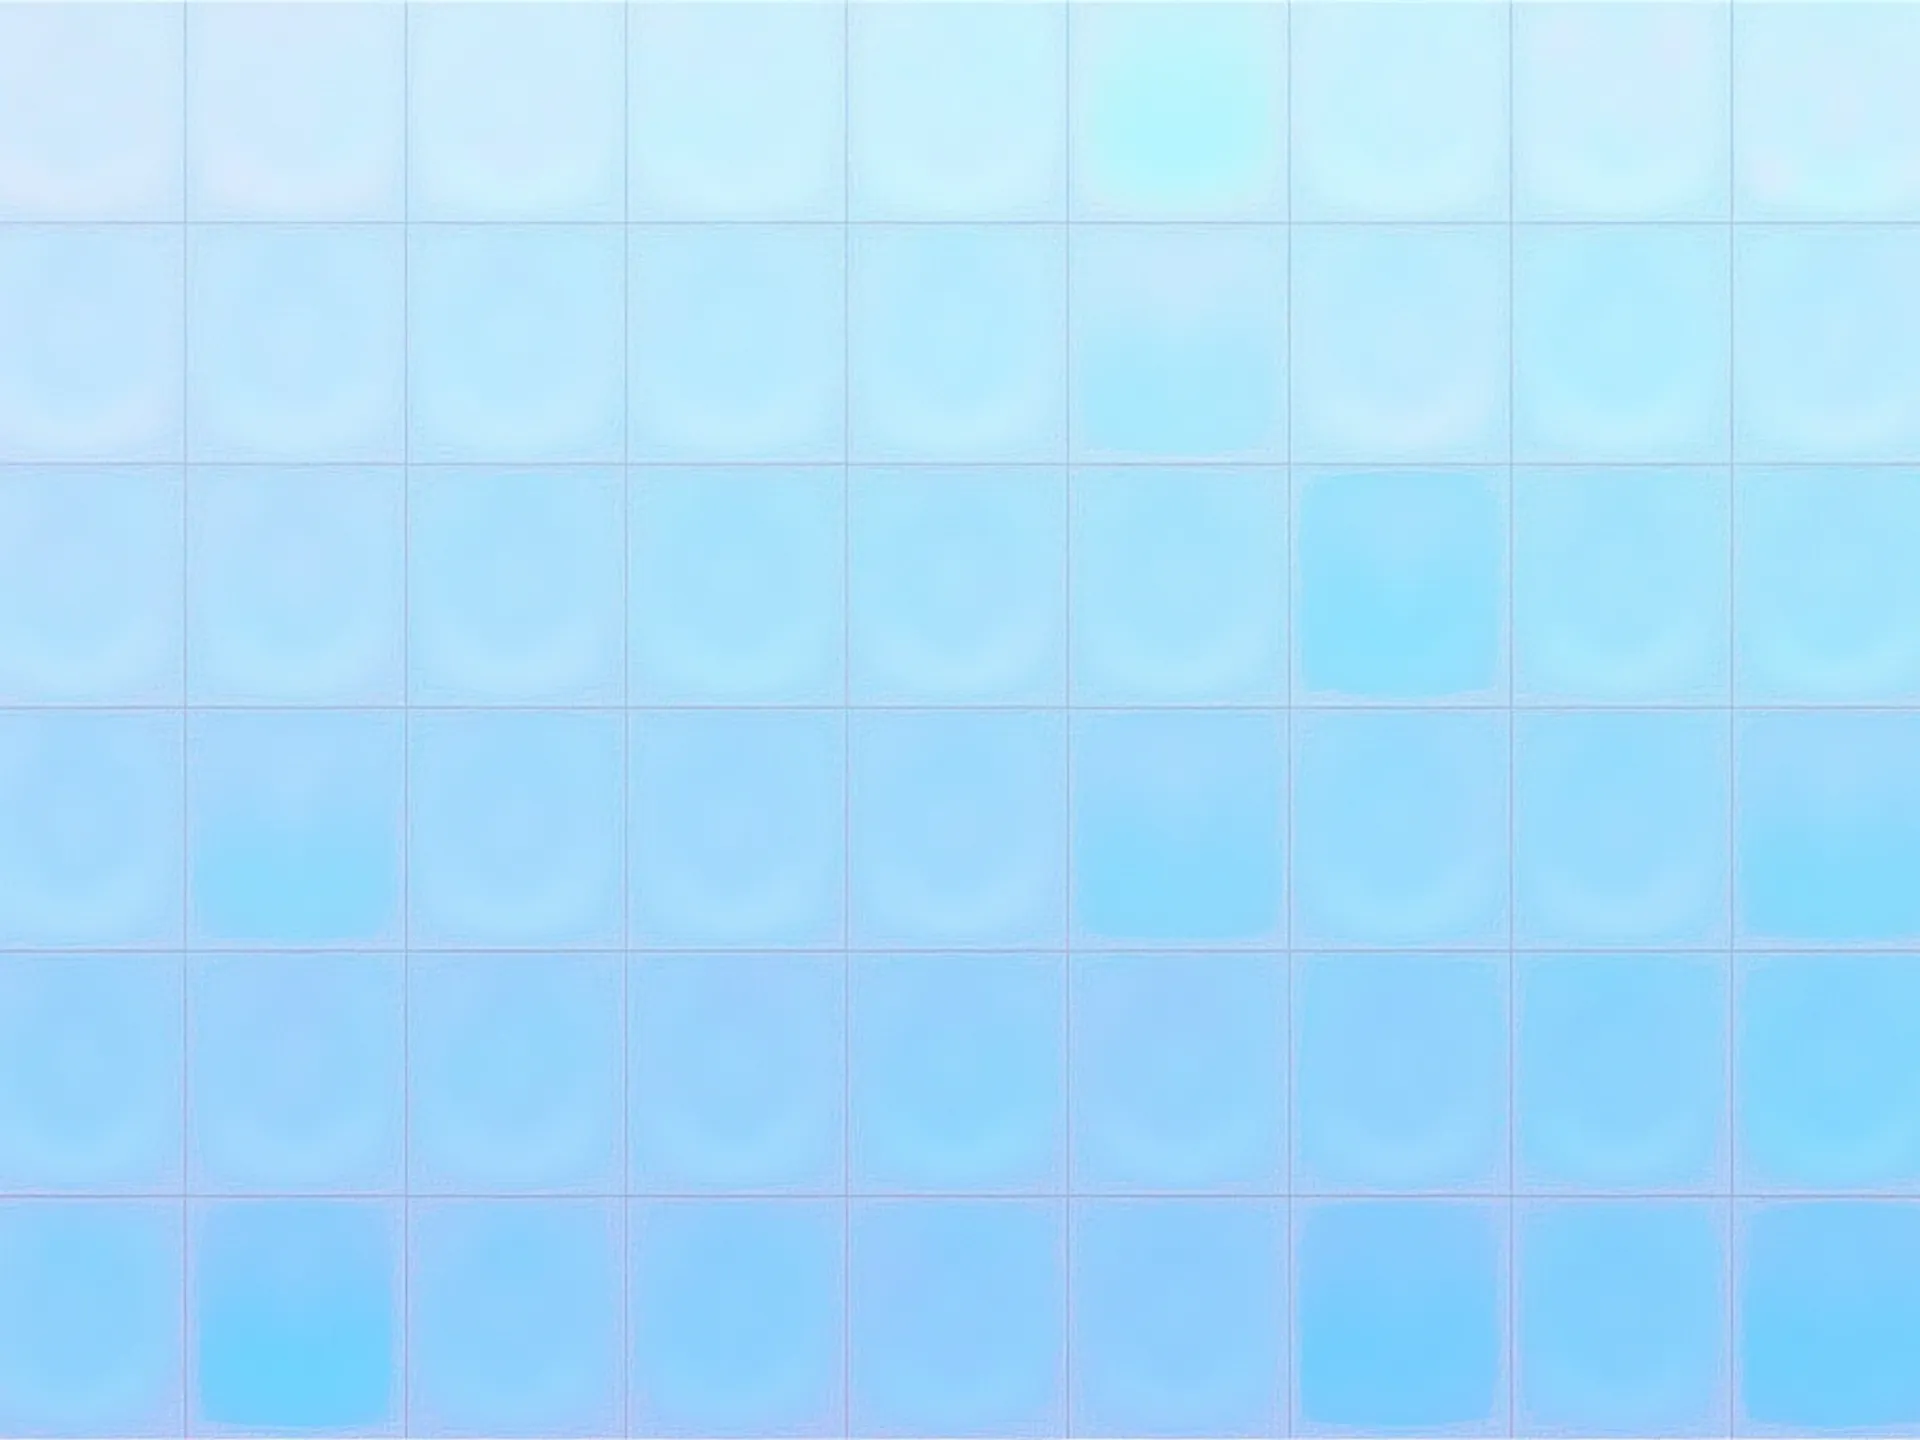

Generate seamlessly tiling photorealistic images from text using Z-Image Turbo


Super fast endpoint for the FLUX.1 [dev] inpainting model with LoRA support, enabling rapid and high-quality image inpaingting using pre-trained LoRA adaptations for personalization, specific styles, brand identities, and product-specific outputs.
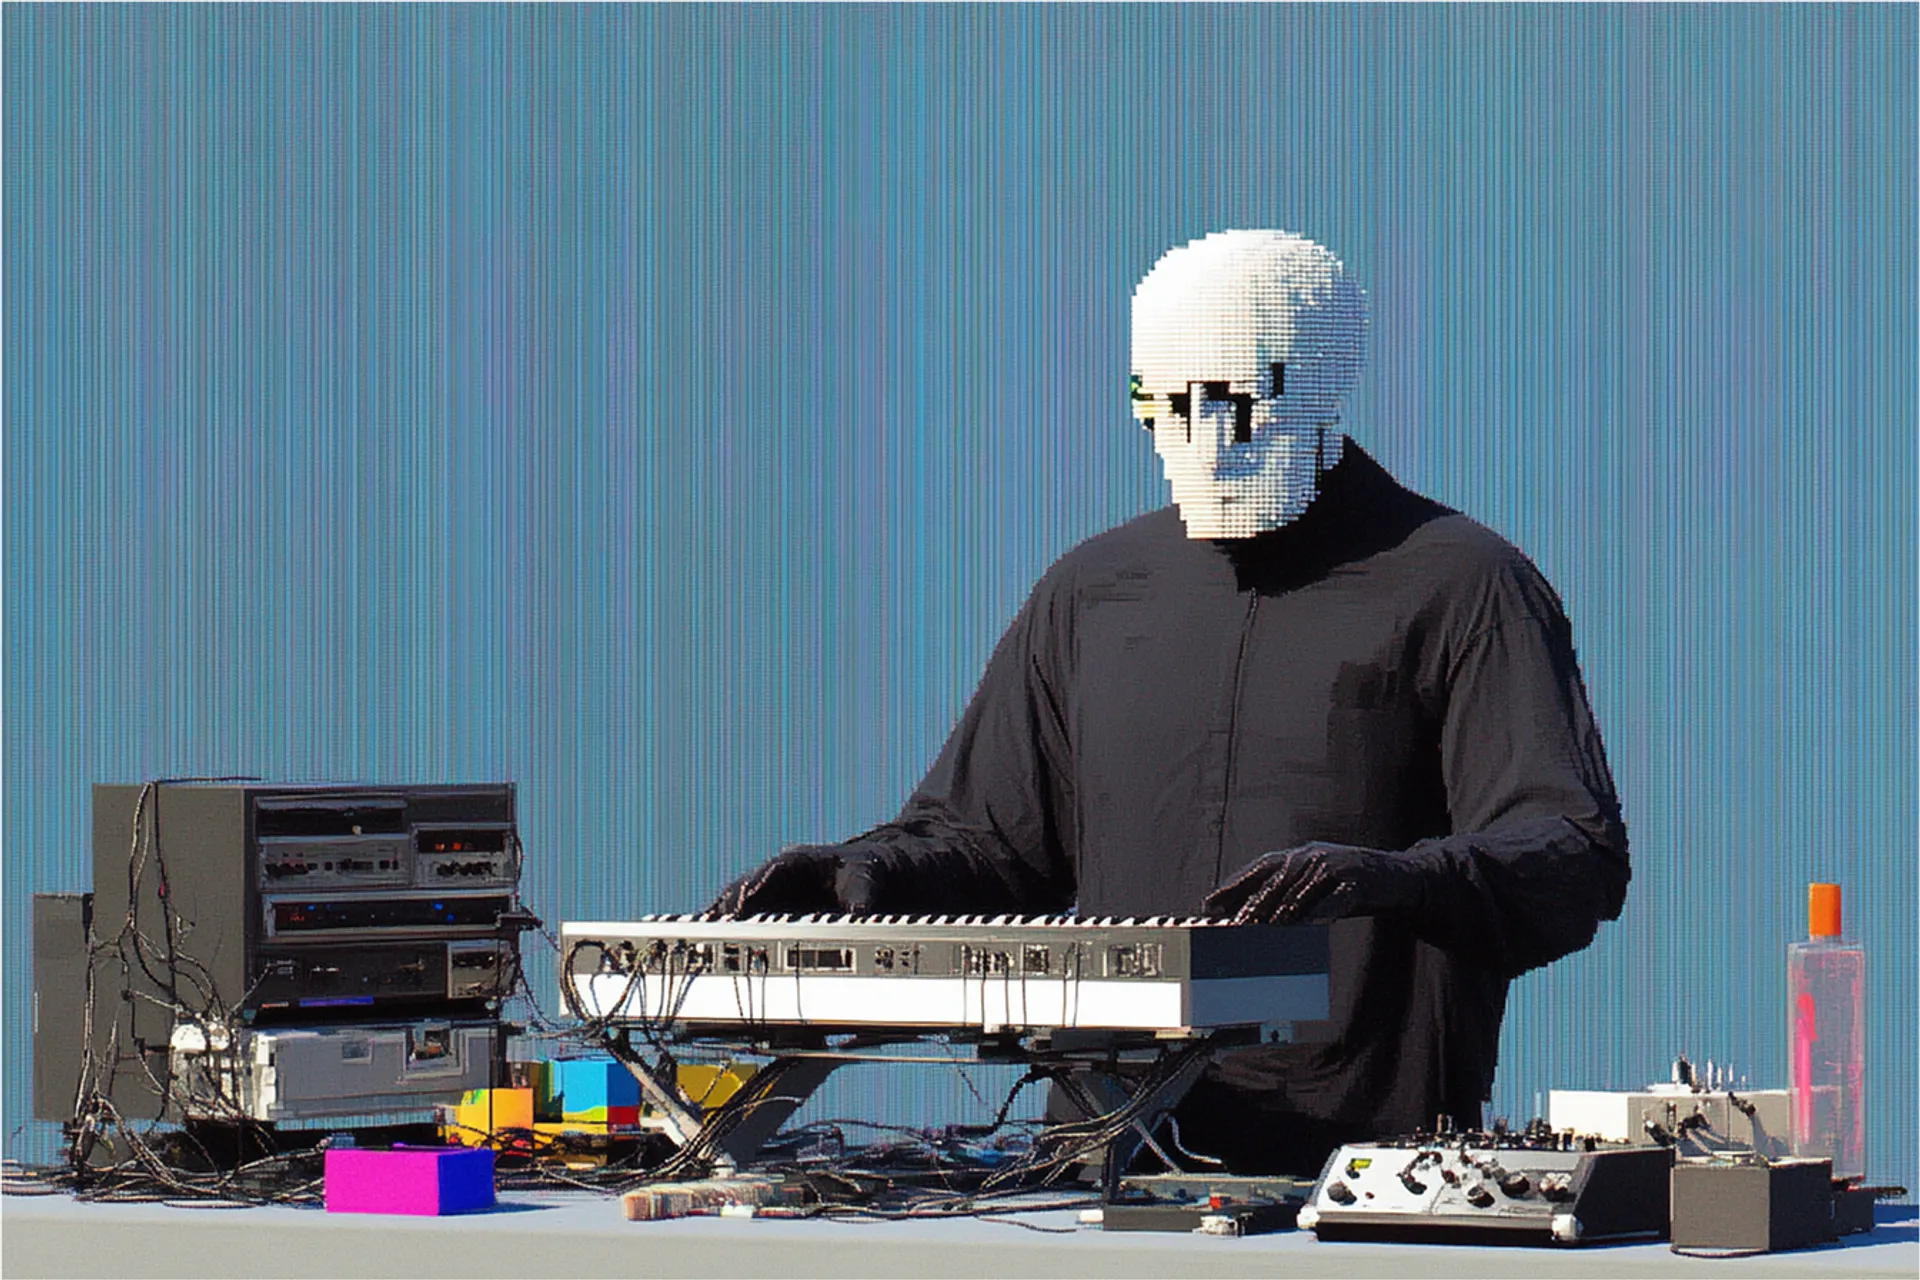
FLUX.1 Kontext [max] text-to-image is a new premium model brings maximum performance across all aspects – greatly improved prompt adherence.

LoRA inference endpoint for Qwen Image 2512, an improved version of Qwen Image with better text rendering, finer natural textures, and more realistic human generation.

Generate high-quality images, posters, and logos with Ideogram's latest V4.0q — producing crisp visuals with accurate text rendering, fine detail, and full creative control for polished, ready-to-use designs FRACTION OF A SECOND.
Generate high-quality images, posters, and logos with Ideogram's latest V4.0q — producing crisp visuals with accurate text rendering, fine detail, and full creative control for polished, ready-to-use designs IN A SECOND.
Run Any Stable Diffusion model with customizable LoRA weights.

Generate high-fidelity images extremely fast from text with Krea 2 Medium Turbo, supporting aspect ratio, creativity, seed controls, and optional style references.
Generate premium-quality images from text prompts using the enhanced WAN 2.7 Pro model with superior detail and composition.
Recraft V4.1 Pro Vector generates large-format, fully editable SVGs with the structural clarity professional illustrators expect. Built for poster art, complex brand assets, and detailed scene illustration, it scales without losing geometric integrity.
Stable Diffusion 3.5 Large is a Multimodal Diffusion Transformer (MMDiT) text-to-image model that features improved performance in image quality, typography, complex prompt understanding, and resource-efficiency.
Generate images with transparent backgrounds using Ideogram Transparent model
Generates raster images that hold a consistent style, from either a saved style ID or reference images attached directly.
Z-Image is the foundation model of the Z- Image family, engineered for good quality, robust generative diversity, broad stylistic coverage, and precise prompt adherence.

HiDream-I1 fast is a new open-source image generative foundation model with 17B parameters that achieves state-of-the-art image generation quality within 16 steps.
FLUX Control LoRA Depth is a high-performance endpoint that uses a control image to transfer structure to the generated image, using a depth map.

Luma Uni-1 turns a text prompt into a single high-fidelity image, with control over aspect ratio and visual style, plus optional web-sourced and reference-image guidance for sharper grounding.
Instruct version of Hunyuan-Image 3.0, with internal reasoning capabilities.
Unified image generation with HiDream-O1-Image. Create, edit, and personalize high-resolution images up to 2K—single native model handles text-to-image, editing, and custom subjects without external components.
Luma Uni-1 Max generates a single image at the model's highest fidelity, delivering richer detail and stronger prompt adherence than the base tier for hero-quality stills.
High-quality text-to-image model by Baidu. Supports English, Chinese, and Japanese prompts with built-in prompt expansion.
Generate high-fidelity, design-ready images with precise typography, strong prompt alignment, and rich visual detail using Microsoft's flagship MAI Image 2.5 Pro.
Every image model on fal shares the same SDK pattern. Swapping Nano Banana 2 for FLUX.2 [dev] or GPT Image 2 is a one-line endpoint change, with the auth flow and queue behavior unchanged.
bashnpm install --save @fal-ai/client
bashexport FAL_KEY="YOUR_API_KEY"
jsimport { fal } from "@fal-ai/client";

const result = await fal.subscribe("fal-ai/nano-banana-2", {
  input: { prompt: "A photorealistic Tokyo cafe at golden hour" }
});
GPT Image 2, Nano Banana 2, Ideogram V3, and Recraft V3 and V4 all treat typography as a primary capability.
The FLUX family covers most photoreal production work on fal, with a few partner models filling specific niches.
For high-volume work on fal, the Turbo and distilled models generate in roughly 1,2 seconds.
You can generate low-resolution drafts on a Turbo model to scout the prompt space, then run only the keepers through a higher-fidelity model at full resolution.
Image generation on fal is priced per output. Some models charge per megapixel of image area, others charge per image.
| Model | Price |
|---|---|
| Seedream V4.5 | $0.04 / image |
| Nano Banana 2 | $0.08 / image at 1K (1.5x at 2K, 2x at 4K) |
| Nano Banana Pro | $0.15 / image |
As a worked example, a team generating 1,000 marketing images per month at 1K resolution pays roughly:


