Best AI Image Generators
Unlock the future of creativity with these text to image, AI image generator models.
Showing 193 to 216 of 217 results

Pony V7 is a finetuned text to image for superior aesthetics and prompt following.
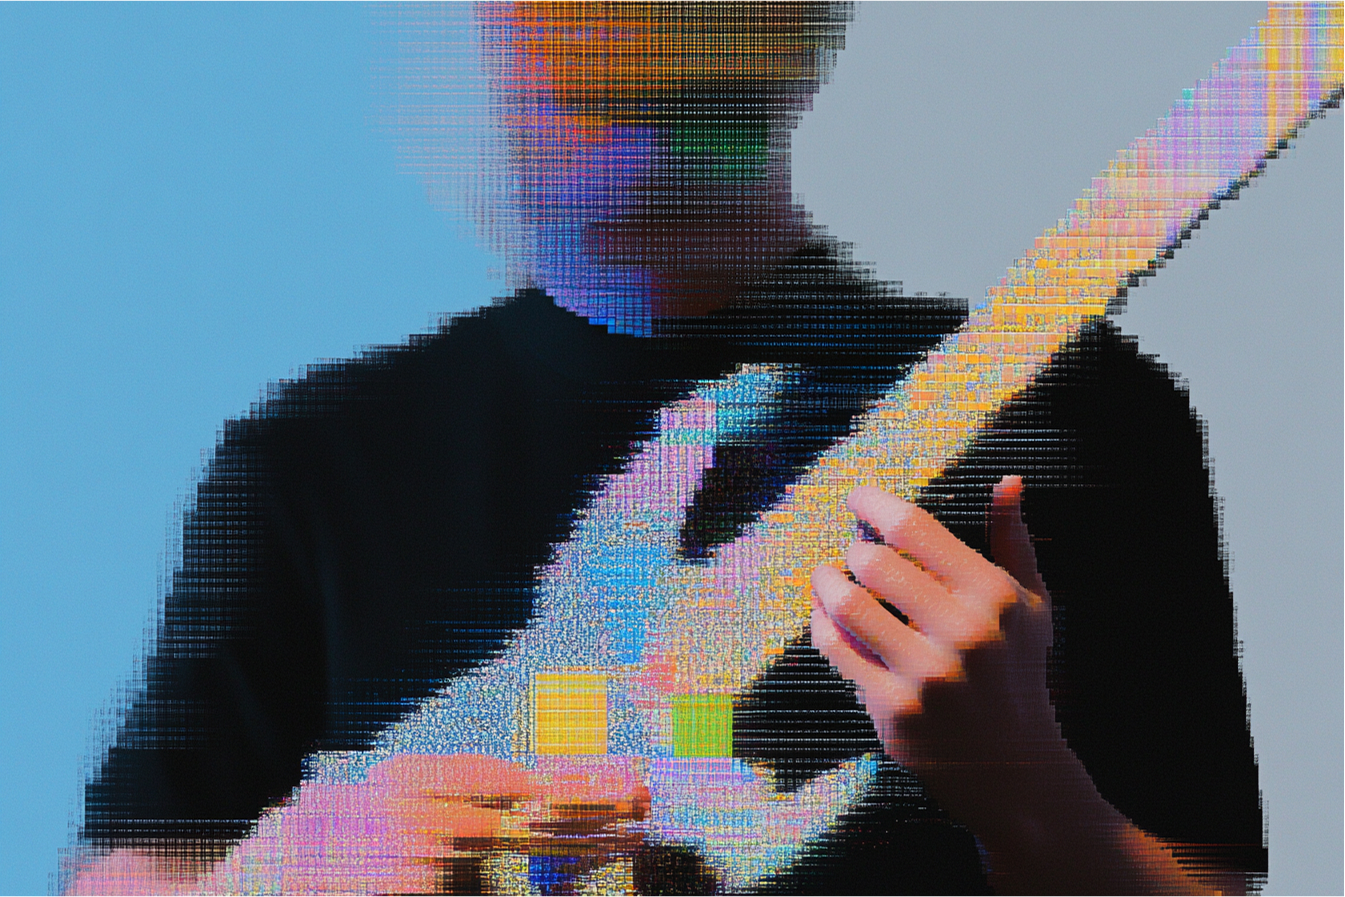
F Lite is a 10B parameter diffusion model created by Fal and Freepik, trained exclusively on copyright-safe and SFW content.
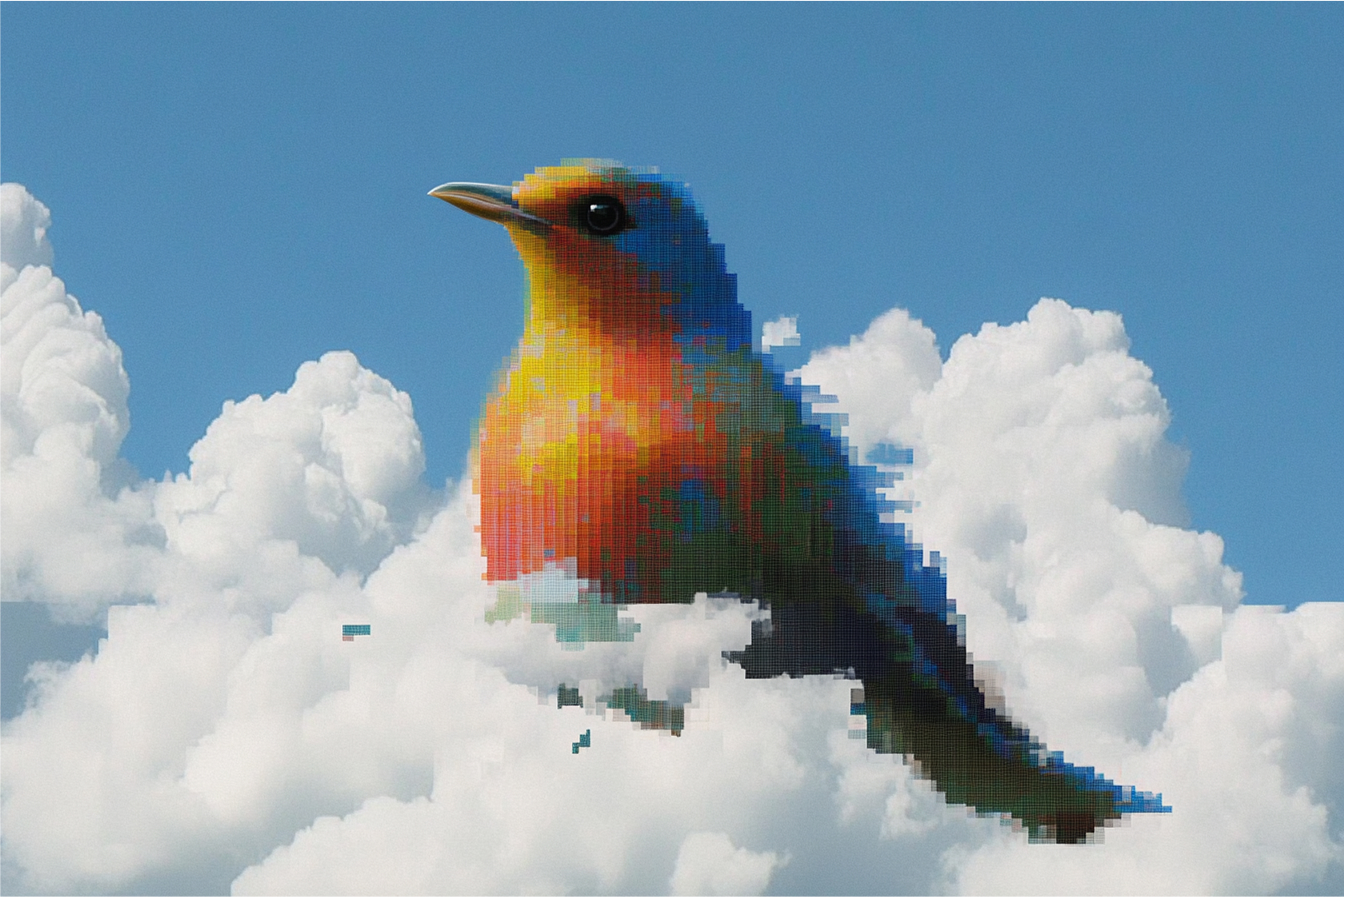
F Lite is a 10B parameter diffusion model created by Fal and Freepik, trained exclusively on copyright-safe and SFW content. This is a high texture density variant of the model.

HiDream-I1 dev is a new open-source image generative foundation model with 17B parameters that achieves state-of-the-art image generation quality within seconds.

Juggernaut Base Flux LoRA by RunDiffusion is a drop-in replacement for Flux [Dev] that delivers sharper details, richer colors, and enhanced realism to all your LoRAs and LyCORIS with full compatibility.

Generate high quality images from text prompts using CogView4. Longer text prompts will result in better quality images.


FLUX Control LoRA Depth is a high-performance endpoint that uses a control image to transfer structure to the generated image, using a depth map.

FLUX Control LoRA Canny is a high-performance endpoint that uses a control image to transfer structure to the generated image, using a Canny edge map.
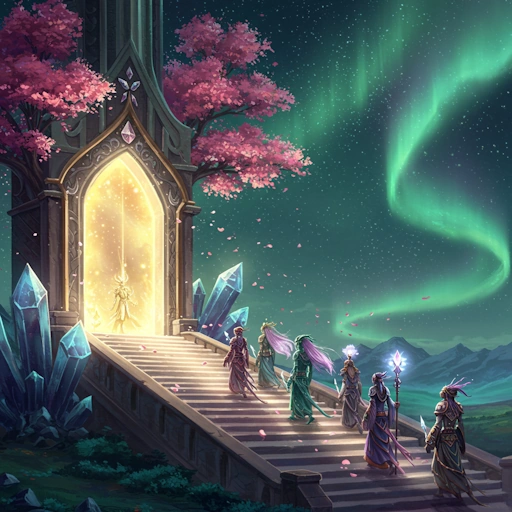
Imagen3 is a high-quality text-to-image model that generates realistic images from text prompts.
Imagen3 Fast is a high-quality text-to-image model that generates realistic images from text prompts.
DeepSeek Janus-Pro is a novel text-to-image model that unifies multimodal understanding and generation through an autoregressive framework
Switti is a scale-wise transformer for fast text-to-image generation that outperforms existing T2I AR models and competes with state-of-the-art T2I diffusion models while being faster than distilled diffusion models.
Switti is a scale-wise transformer for fast text-to-image generation that outperforms existing T2I AR models and competes with state-of-the-art T2I diffusion models while being faster than distilled diffusion models.

AuraFlow v0.3 is an open-source flow-based text-to-image generation model that achieves state-of-the-art results on GenEval. The model is currently in beta.

OmniGen is a unified image generation model that can generate a wide range of images from multi-modal prompts. It can be used for various tasks such as Image Editing, Personalized Image Generation, Virtual Try-On, Multi Person Generation and more!

FLUX.1 [pro] new is an accelerated version of FLUX.1 [pro], maintaining professional-grade image quality while delivering significantly faster generation speeds.
Super fast endpoint for the FLUX.1 [schnell] model with subject input capabilities, enabling rapid and high-quality image generation for personalization, specific styles, brand identities, and product-specific outputs.

Collection of SDXL Lightning models.

Dreamshaper model.

State-of-the-art open-source model in aesthetic quality

Generate realistic images.
SDXL with an alpha channel.

Generate Images with ControlNet.

Fooocus extreme speed mode as a standalone app.
Every image model on fal shares the same SDK pattern. Swapping Nano Banana 2 for FLUX.2 [dev] or GPT Image 2 is a one-line endpoint change, with the auth flow and queue behavior unchanged.
bashnpm install --save @fal-ai/client
bashexport FAL_KEY="YOUR_API_KEY"
jsimport { fal } from "@fal-ai/client";

const result = await fal.subscribe("fal-ai/nano-banana-2", {
  input: { prompt: "A photorealistic Tokyo cafe at golden hour" }
});
GPT Image 2, Nano Banana 2, Ideogram V3, and Recraft V3 and V4 all treat typography as a primary capability.
The FLUX family covers most photoreal production work on fal, with a few partner models filling specific niches.
For high-volume work on fal, the Turbo and distilled models generate in roughly 1,2 seconds.
You can generate low-resolution drafts on a Turbo model to scout the prompt space, then run only the keepers through a higher-fidelity model at full resolution.
Image generation on fal is priced per output. Some models charge per megapixel of image area, others charge per image.
| Model | Price |
|---|---|
| Seedream V4.5 | $0.04 / image |
| Nano Banana 2 | $0.08 / image at 1K (1.5x at 2K, 2x at 4K) |
| Nano Banana Pro | $0.15 / image |
As a worked example, a team generating 1,000 marketing images per month at 1K resolution pays roughly: